
Open-Source ChatGPT Alternative (2026, Free)
 Identifying ChatGPT · Mark source
This hub lists open-weight chat and completion models that people compare with ChatGPT-class hosted products. ChatGPT is named only to identify that product class. We copy licenses and parameter counts from official cards. We do not rank writing quality against ChatGPT. Latest additions include Reflection Beam (Apache-2.0 501B/23B, weights 2026-10-16), Kimi K3 (2.8T/104B, Kimi K3 License), Hy-Memory (30B-A3B writer + MemHub), NVIDIA Nemotron 3.5 Super VL and Bolt. Coding agents hang off Cursor and Copilot hubs.
- Open WebUI — Self-hosted chat UI for Ollama and OpenAI-compatible APIs, with a branding-restricted license.
- LibreChat — MIT self-hosted chat UI with agents, MCP, and many provider connectors.
- Jan — Apache-2.0 desktop app that runs chat models 100% offline on your computer.
How we pick
- Official Hugging Face card we could open (README or API).
- License and parameter figures copied from that card.
- No unsourced “beats ChatGPT” claims; self-reported tables stay labeled self-reported.
Comparison
| Name | License | Developer | Parameters | Type / modalities |
|---|---|---|---|---|
| Open WebUI | other | See page | See page | See page |
| LibreChat | MIT | See page | See page | See page |
| Jan | Apache-2.0 | See page | See page | See page |
| DeepInfer | Apache-2.0 | See page | See page | See page |
| vLLM | Apache-2.0 | See page | See page | See page |
| Headroom | Apache-2.0 | See page | See page | See page |
| DeepSeek-V4.1-Flash | MIT | DeepSeek-AI | 552B backbone | text, image |
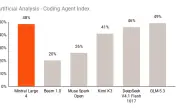
| Reflection Beam | Apache-2.0 | Reflection | 501.3B | text |
| Kimi K3 | other | Moonshot AI | 2.8T | text, image, video |
| Hy-Memory | Apache-2.0 | Tencent Hunyuan | 30B | text |
| Ling-3.1-flash | MIT | inclusionAI (Ant Group) | 560B | text |
| MiniCPM-V 4.7 | Apache-2.0 | OpenBMB (THUNLP and ModelBest, per the MiniCPM-V README) | 35.2B (HF safetensors BF16) | image, text, video, document |
| Muse Spark Open | other | Meta (Meta Platforms, Inc. / Meta Platforms Ireland Limited) | 816B | text, image, audio, video |
| Nemotron 3.5 Super VL | other | NVIDIA Corporation | 120B | text, image, video |
| Nemotron 3.5 Bolt | other | NVIDIA Corporation | 74B | text, image, video |
| Ornith-1.5-122B | MIT | Ornith | 122B (card) | text |
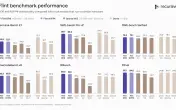
| Flint | Apache-2.0 | Recursive | 39.8B | text |
| Sage-A1.5 | Apache-2.0 | Shanghai AI Laboratory (InternScience) | 35B (card); ~36.0B (HF safetensors) | text, image |
| Carbon-X | Apache-2.0 | Hugging Face Bio (Hugging Face, Zhongguancun Academy, TIGEM / University of Naples Federico II) | 14.8B (card); 14,822,046,720 (HF safetensors) | text, dna |
| MiniMax M3.1 Flash | other | MiniMax | 428B (card) | text, image, video |
| Raon-1-mini | Apache-2.0 | KRAFTON AI | 28.8B | text |
| GLM-5.3-Flash | MIT | Z.ai | 320B (card) | text, image, video |
| MiMo-V2.6-Flash | MIT | Xiaomi MiMo | 309B (card) | text, image, video, audio |
| Nanbeige4.3-33B | Apache-2.0 | Nanbeige (BOSS Zhipin) | 33B (card) | text |
| Qwen3.8-27B | Apache-2.0 | Qwen | 27B (card) | text, image, video |
| Spark-X2.6-4B | Apache-2.0 | XHToken (SparkLLM Team) | 4B (card) | text |
| LFM3 | other | Liquid AI | 1.73B (LFM3-1.7B text) | text, image, video, audio, speech |
| LFM3-Omni-2B | other | Liquid AI | 2.17B (card) | text, image, video, audio, speech |
| LFM3-1.7B | other | Liquid AI | 1.73B (card) | text |
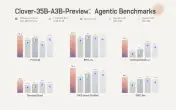
| Clover-35B-A3B-Preview | Apache-2.0 | DiffuSpace | 35B (card) | text |
| Mistral Large 4 | other | Mistral AI | ~1T (card) | text, image |
| Mage-VL-Cowork | Apache-2.0 | Microsoft Mage Team | 4.74B (HF safetensors BF16) | image, text |
| Granite Switch 4.1 | Apache-2.0 | IBM | 8.78B (8B card safetensors) | text, audio, speech |
UIs added 2026-10-19: Open WebUI, LibreChat, Jan. Compare Open WebUI vs ChatGPT. Identification page: ChatGPT.
Listed models: LFM3-1.7B (Liquid AI text 1.73B / 256K, 635 likes, added 2026-11-01; not Omni; compare vs LFM3-Omni-2B), Mage-VL-Cowork (Microsoft Apache-2.0 ~4.7B hybrid CUA VLM, 93 likes, added 2026-11-01; not Iris-3B T2I), Granite Switch 4.1 (IBM Apache-2.0 8B+30B compose, 55 likes on 8B, added 2026-11-01), Clover-35B-A3B-Preview (DiffuSpace Apache-2.0 diffusion MoE, 35B/~3B, 128K, 176 likes, added 2026-10-31; compare vs Flint), LFM3-Omni-2B (Liquid AI 2.17B omni, text+speech out, 227 likes, added 2026-10-31; not LFM3-1.7B text), Mistral Large 4 (ungated ~1T/52B multimodal MoE, Ecosystem Open-Weight; MaaS needs a separate Mistral commercial license; 1,301 likes, added 2026-10-30; compare vs Muse Spark Open), LFM3 (Liquid AI ~2B edge family, 160 likes on LFM3-1.7B, added 2026-10-28; not LFM2.5-24B-A2B; compare vs LFM2.5-24B-A2B), Spark-X2.6-4B (XHToken Apache-2.0 ~4B on-device agent, 514 likes, added 2026-10-26; not Meta Muse Spark Open; compare vs LFM2.5-24B-A2B), Nanbeige4.3-33B (Nanbeige / BOSS Zhipin Apache-2.0 33B text teacher, 512K, 365 likes, added 2026-10-26; compare vs Qwen3.8-27B), Qwen3.8-27B (Qwen Apache-2.0 27B native VLM, 18,393 likes, identification page for that vs pair), DeepSeek-V4.1-Flash (1017 checkpoint), GLM-5.3-Flash (Z.ai MIT 320B/18B multimodal MoE, 2,941 likes, added 2026-10-25; compare vs Flash-1017), MiMo-V2.6-Flash (Xiaomi Flash-RL, card MIT tag / no LICENSE blob, 309B/15B, 582 likes, added 2026-10-25), MiniMax M3.1 Flash (MiniMax Community License 428B/23B multimodal MoE, 259 likes, weights last modified 2026-10-23; compare vs Flash-1017), Raon-1-mini (KRAFTON Apache-2.0 28.8B/4.3B preview, 148 likes, added 2026-10-24), Ornith-1.5-122B (MIT 122B MoE, added 2026-10-22), Flint (Apache-2.0 39.8B/2.5B local coding MoE, 533 likes, added 2026-10-23), Sage-A1.5 (Apache-2.0 35B science/agent VLM, 223 likes, added 2026-10-23), Carbon-X (Apache-2.0 14.8B DNA+text chat, 74 likes, added 2026-10-23; not a general ChatGPT stand-in and not clinically validated), Reflection Beam, Kimi K3, Hy-Memory, Ling-3.1-flash, MiniCPM-V 4.7, Muse Spark Open, Nemotron 3.5 Super VL, and Nemotron 3.5 Bolt. Other open LLMs also live on closed LLM APIs (today: Kolibri-1, LFM2.5-24B-A2B; LFM3 and Nemotron 3.5 Bolt are listed on both hubs). Image generators are on Midjourney-class alternatives. Compare Mistral Large 4 vs Muse Spark Open, LFM3 vs LFM2.5-24B-A2B, Spark-X2.6-4B vs LFM2.5-24B-A2B, Nanbeige4.3-33B vs Qwen3.8-27B, GLM-5.3-Flash vs DeepSeek-V4.1-Flash, MiniMax M3.1 Flash vs DeepSeek-V4.1-Flash, Flint vs Ornith-1.5-122B, Sage-A1.5 vs Ornith-1.5-122B, Ornith-1.5-122B vs DeepSeek-V4.1-Flash, Beam vs Muse Spark Open and DeepSeek-V4.1-Flash vs Kimi K3. Coding agents: Claude Code alternatives. Workspace clones: Notion alternatives (AppFlowy). Workspace AI: Notion AI alternatives. Pixel editors: PhotoCraft vs GIMP.
Sourced snapshot
| Field | DeepSeek-V4.1-Flash (2026-10-13) | MiniCPM-V 4.7 (2026-10-15) | Muse Spark Open (2026-10-16) | Nemotron 3.5 Super VL (2026-10-17) | Nemotron 3.5 Bolt (2026-10-17) |
|---|---|---|---|---|---|
| Host | huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash (not gated) | huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B (not gated) | huggingface.co/meta-models/Muse-Spark-Open-816B-A42B (gated: manual) | huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Super-VL-120B-A12B-BF16 (not gated) | huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Bolt-74B-A9B-BF16 (not gated) |
| HF likes / downloads | 4,462 / 1,272,612 | 631 / 4,157 | 264 / 402 | 142 / 40 | 50 / — |
| License | MIT | Apache-2.0 (card + GitHub LICENSE) | Muse Model License (SPDX other; limited commercial) | OpenMDW-1.1 (commercial-friendly) | OpenMDW-1.1 (commercial-friendly) |
| Size | 552B backbone / 8B prefill · 16B decode | ~35.2B BF16 (35B-A3B MoE); 1B variant ~1.55B | 816B total / 42B active sparse MoE | 120B total / 12B active hybrid MoE | 74B total / 9B active LatentMoE |
| Job | Images + text in, text out | Image/video/document + text in, text out (on-device VLM) | Text + image + audio + video in, text out | Text + image + video in, text out | Text + image + video in, text out (local-agent VLM) |
| Context | 1M tokens | — | 1M tokens | 1M tokens | 256K tokens |
| Hardware | Vendor figures omitted | iPhone 17 Pro Max claim (vendor) | ≥700 GB VRAM (NVFP4, vendor) | 2× H100 or 1× GB200 (NVFP4, vendor) | 24GB VRAM (IQ2 variant, vendor) |
| Quality vs ChatGPT | Not independently tested | Not independently tested | Not independently tested | Not independently tested | Not independently tested |
October 19 additions
| Field | DeepSeek-V4.1-Flash-1017 (2026-10-19) | Reflection Beam (2026-10-19) | Kimi K3 (2026-10-19) | Hy-Memory (2026-10-19) |
|---|---|---|---|---|
| Host | huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash-1017 (not gated) | huggingface.co/reflection/Beam-1.0-501B-A23B (not gated) | huggingface.co/moonshotai/Kimi-K3 (not gated) | huggingface.co/tencent/Hy-Memory-30B-A3B (not gated) |
| HF likes / downloads | 1,333 / 10,233 | 148 / 1,591 | 11,761 / 1,030,720 | 188 / 1,187 |
| License | MIT | Apache-2.0 | Kimi K3 License (SPDX other) | Apache-2.0 |
| Size | 552B backbone / 8B prefill · 16B decode | 501.3B / 23.4B sparse MoE | 2.8T / 104B LatentMoE | 30B / ~3B writer MoE |
| Job | Images + text in, text out | Text in, text out (coding/agents) | Image-text-to-text | Memory writer for external stores |
| Context | 1M tokens | 1M tokens | 1M tokens | Not independently verified |
| Quality vs ChatGPT | Not independently tested | Not independently tested | Not independently tested | Not independently tested |
Arena.ai Code Arena WebDev (open-source filter, 18 October 2026 snapshot) lists DeepSeek-V4.1-Flash-20261017 (Max) at open-source #1 (score 1670) and Kimi K3 (Max) at #2 (1655). That is a third-party leaderboard, not a forkalt ranking and not a ChatGPT column.
Why DeepSeek-V4.1-Flash is on a ChatGPT hub
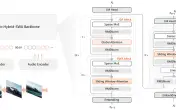
“Open source ChatGPT alternative” is a durable query. The new-term we could source on 2026-10-13 from a public, ungated card is DeepSeek-V4.1-Flash: MIT, 552B backbone, 8B/16B active, 1M context, 4,462 likes, created 2026-09-10. It natively takes images and text and emits text. That is the same job family as a hosted chat product, not a proof that it substitutes for ChatGPT’s applications, memory, or browsing.
ChatGPT is OpenAI’s hosted chat product. We use the ChatGPT mark only to identify the search. We did not copy OpenAI pricing or model names into a quality table.
Local versus hosted
The MIT weights are on Hugging Face. The card also links chat.deepseek.com, which is a hosted UI. If your requirement is “run weights on hardware I control,” start from the Hugging Face repo and the inference/ notes on the card — and budget for a 552B-backbone MoE. If your requirement is “a free chat box,” that hosted UI is a different artifact and is not what this hub ranks.
There is no GitHub repository deepseek-ai/DeepSeek-V4.1-Flash (404 on 2026-10-13). Encoding helpers are at deepseek-ai/deepseek-recipe.
What we left out
Other open chat checkpoints (including models already identified elsewhere on forkalt) will join this list when we attach them explicitly. Kolibri-1 stays on the generic closed-API hub so German/English MoE facts are not rewritten as a ChatGPT claim. MiniCPM-V 4.7 is attached here as an on-device multimodal option, not as a ChatGPT quality ranking. Muse Spark Open is attached as a gated Meta multimodal MoE identification row — datacenter-class VRAM, not a ChatGPT substitute.
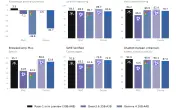
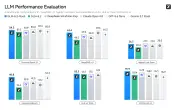
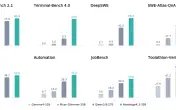
Self-reported GPQA / Terminal-Bench / DeepSWE numbers on the DeepSeek card are quoted on the model page and labeled self-reported. They are not a ChatGPT comparison.
How to choose
- Need Mistral’s ungated ~1T/52B multimodal MoE (text+image, 1M, Ecosystem Open-Weight; MaaS extra license): Mistral Large 4. Compare Mistral Large 4 vs Muse Spark Open.
- Need Liquid’s text 1.73B / 256K card (not Omni, not LFM2.5): LFM3-1.7B. Compare LFM3-1.7B vs LFM3-Omni-2B. Family map: LFM3. Dedicated omni card: LFM3-Omni-2B. Compare family vs the older MoE: LFM3 vs LFM2.5-24B-A2B.
- Need Microsoft’s Apache-2.0 ~4.7B hybrid computer-use VLM (GUI + bash): Mage-VL-Cowork. Not Iris-3B.
- Need IBM’s Apache-2.0 8B+30B Switch (chat + decision aLoRA + embedded TurboCTC): Granite Switch 4.1. Speech-only family: Granite Speech 5.0.
- Need DiffuSpace’s Apache-2.0 diffusion 35B-A3B (128K, Qwen3.6 base): Clover-35B-A3B-Preview. Compare Clover-35B-A3B-Preview vs Flint.
- Need Apache-2.0 ~4B on-device text (Ollama/llama.cpp named; not Meta Muse Spark): Spark-X2.6-4B. Compare Spark-X2.6-4B vs LFM2.5-24B-A2B.
- Need a 33B Apache-2.0 text teacher (512K, agent/coding card): Nanbeige4.3-33B. Compare Nanbeige4.3-33B vs Qwen3.8-27B.
- Need Qwen’s 27B native VLM (262K, Apache-2.0 LICENSE file): Qwen3.8-27B.
- Need Z.ai’s MIT 320B/18B multimodal MoE: GLM-5.3-Flash. Compare GLM-5.3-Flash vs DeepSeek-V4.1-Flash.
- Need Xiaomi’s 309B/15B Flash-RL card (MIT tag; no LICENSE blob): MiMo-V2.6-Flash.
- Need MiniMax’s 428B/23B multimodal MoE and can accept the Community License (attribution + $20M revenue trigger): MiniMax M3.1 Flash. Compare MiniMax M3.1 Flash vs DeepSeek-V4.1-Flash.
- Need a compact Apache-2.0 preview MoE (28.8B/4.3B, Korean+agent card): Raon-1-mini.
- Need Apache-2.0 39.8B/2.5B local coding MoE with GGUF/Ollama: Flint. Compare Flint vs Ornith-1.5-122B.
- Need Apache-2.0 35B science/agent VLM (256K, orchestration/verification): Sage-A1.5. Compare Sage-A1.5 vs Ornith-1.5-122B.
- Need MIT 122B MoE coding/agent weights and a vLLM/SGLang recipe: Ornith-1.5-122B. Compare Ornith-1.5-122B vs DeepSeek-V4.1-Flash.
- Need MIT multimodal weights with a 1M context figure and the 1017 checkpoint: DeepSeek-V4.1-Flash.
- Need MIT 560B/25B hybrid MoE (card 1M context; config.json 262,144): Ling-3.1-flash.
- Need ungated Apache-2.0 text MoE for coding/agents (501B/23B, Mirror CLI): Reflection Beam. Compare Beam vs Muse Spark Open.
- Need 2.8T-class open multimodal weights and can accept the Kimi K3 License: Kimi K3. Compare DeepSeek-V4.1-Flash vs Kimi K3.
- Need an agent memory writer (30B-A3B) plus SDK/MemHub, not a chat model: Hy-Memory.
- Need Apache-2.0 on-device VLM with a 35B-A3B MoE plus a 1B sibling: MiniCPM-V 4.7. iPhone 13+ tok/s / 3 GB is a vendor claim.
- Need gated Meta 816B/42B multimodal MoE (1M context; datacenter-class VRAM): Muse Spark Open. Blog quality adjectives stay vendor claims.
- Need ungated NVIDIA datacenter VLM (120B/12B, 1M context, OpenMDW-1.1 commercial-friendly): Nemotron 3.5 Super VL. Compare with Nemotron 3.5 Super VL vs Muse Spark Open.
- Need local-agent VLM that fits in 24GB VRAM (74B/9B, 256K context, Ollama-ready): Nemotron 3.5 Bolt. Vendor RTX 84 tok/s claim.
- Need NVIDIA speech / file ASR, not a chat VLM: Nemotron 3.5 Transcribe on Otter.ai alternatives. Do not mix that id with Bolt or Super VL.
- Need the Aleph Alpha German/English MoE already sourced on this site: Kolibri-1.
- Need a self-hosted chat UI (branding clause): Open WebUI — Open WebUI vs ChatGPT.
- Need a MIT self-hosted UI: LibreChat.
- Need an offline desktop app: Jan.
- Need DeepSeek’s official inference engine for the 1017 checkpoint: DeepInfer (Apache-2.0, 13,104 stars, 2026-10-21) — DeepInfer vs vLLM.
- Need a general Apache-2.0 LLM server: vLLM (94,459 stars, v0.32.0, 2026-10-21).
- Need embeddings rather than chat: OpenAI embeddings alternatives.
What “open” does not mean
DeepSeek-V4.1-Flash weights are MIT and not gated. That is a stronger “take the files home” story than LTX-2.5 or SAM 3. It is still a 552B-backbone MoE with 1M context in the README. “Free” on this hub means the card’s price is not a SaaS SKU; it does not mean a laptop GPU will load the full model. We have not published a quantization recipe.
The card’s comparison table names Opus-5.0, GPT-5.6 Sol, K3, GLM-5.3, and DeepSeek’s own V4-Pro / V4-Flash. ChatGPT as a product is not a column. Treating any of those rows as “beats ChatGPT” would be editorial malpractice. Self-reported GPQA Diamond 90.9 and Terminal-Bench 2.1 90.6 stay on the model page with selfReported: true.
Prompt encoding is not a default Jinja template. If you wire this checkpoint into a generic OpenAI-compatible proxy without encoding/ or deepseek-recipe (381 GitHub stars on 2026-10-13), you are off the official path. Hosted chat.deepseek.com is convenient and not the MIT weights.
See also closed LLM APIs, classification APIs, Cursor alternatives (Headroom compression layer, Orca orchestrator, DeepSeek Harness MIT runtime — added 2026-10-25), Perplexity alternatives, and AI Chat & Agents. Serving stacks added 2026-10-21: DeepInfer, vLLM, DeepInfer vs vLLM. Community chat (not an LLM UI): Discord alternatives.
Listed options
Open WebUI
Self-hosted chat UI for Ollama and OpenAI-compatible APIs, with a branding-restricted license.
LibreChat
MIT self-hosted chat UI with agents, MCP, and many provider connectors.
Jan
Apache-2.0 desktop app that runs chat models 100% offline on your computer.
DeepInfer
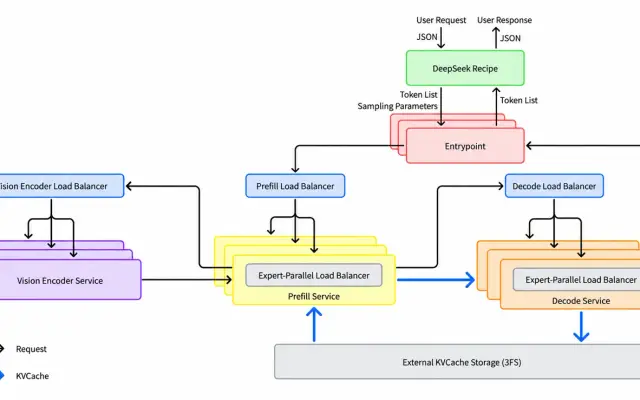
Apache-2.0 official inference framework for DeepSeek models, released as offline serving.
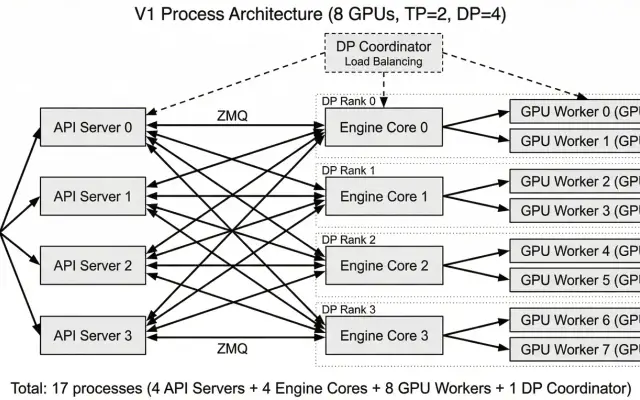
vLLM
Apache-2.0 high-throughput LLM inference and serving engine (PagedAttention).
Headroom
Apache-2.0 context compression layer for AI agents (library, proxy, MCP).
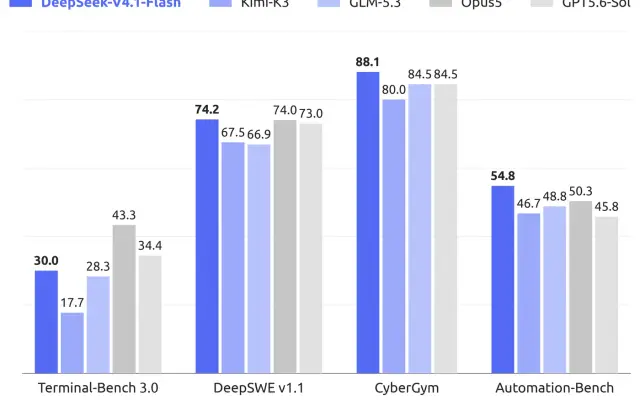
DeepSeek-V4.1-Flash
MIT multimodal MoE (552B backbone, 8B/16B active, 1M context); 1017 checkpoint opened 2026-10-17.
Reflection Beam
Reflection 501B/23B Apache-2.0 sparse MoE for coding and long-horizon agents; weights opened 2026-10-16.
Kimi K3
Moonshot 2.8T/104B open-weight multimodal MoE with 1M context under the Kimi K3 License.
Hy-Memory
Tencent Hunyuan memory-writer MoE (30B-A3B) plus Hy-Memory SDK and MemHub for agent memory.
Ling-3.1-flash
inclusionAI MIT 560B/25B hybrid-linear MoE with official SGLang and vLLM recipes.
MiniCPM-V 4.7
OpenBMB on-device multimodal VLM; first MoE in the MiniCPM-V series (35B-A3B + 1B).
Muse Spark Open
Meta natively multimodal sparse MoE (816B total / 42B active), 1,048,576-token context.
Nemotron 3.5 Super VL
NVIDIA vision-language MoE (120B total / 12B active) with 1M-token context, reasoning mode, native speculative decoding.
Nemotron 3.5 Bolt
NVIDIA compact vision-language MoE (74B total / 9B active) for local agentic tasks; 24GB IQ2-quantized variant.
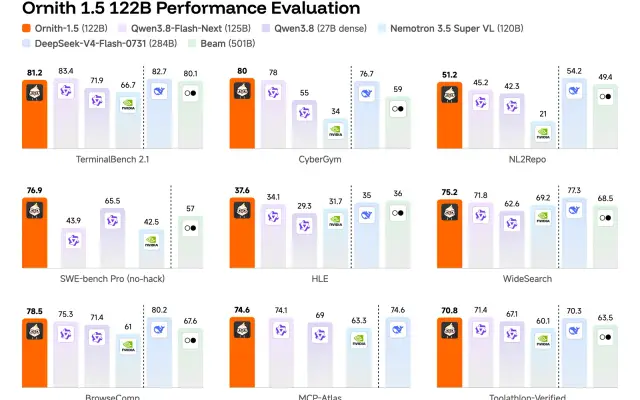
Ornith-1.5-122B
MIT 122B MoE coding/agent model with 262k context and OpenAI-style tool calling.
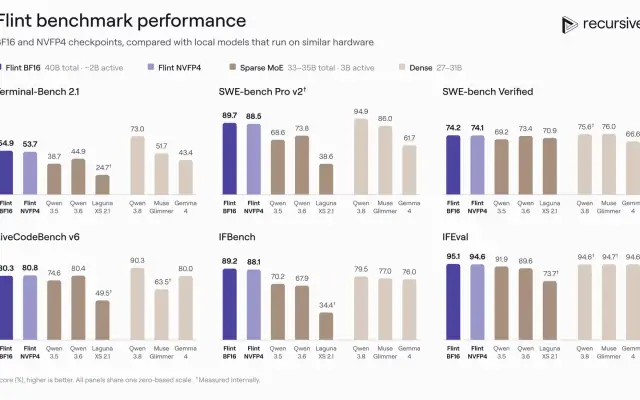
Flint
Recursive Apache-2.0 39.8B/2.5B local coding-agent MoE with GGUF, INT4, and Ollama tags.
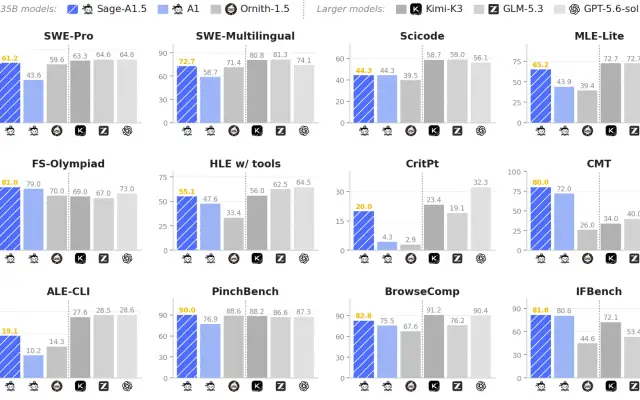
Sage-A1.5
Shanghai AI Lab Apache-2.0 35B MoE science/agent VLM with orchestration and self-verification.
Carbon-X
Hugging Face Bio Apache-2.0 14.8B DNA+text chat model with a hybrid 6-mer tokenizer.
MiniMax M3.1 Flash
Open-weight multimodal MoE (card 428B/23B, 1M context) under the MiniMax Community License.
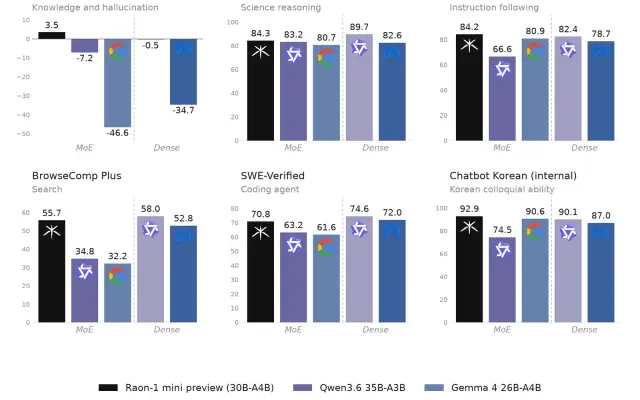
Raon-1-mini
Apache-2.0 preview compact MoE (28.8B/4.3B) from KRAFTON AI, trained from scratch.
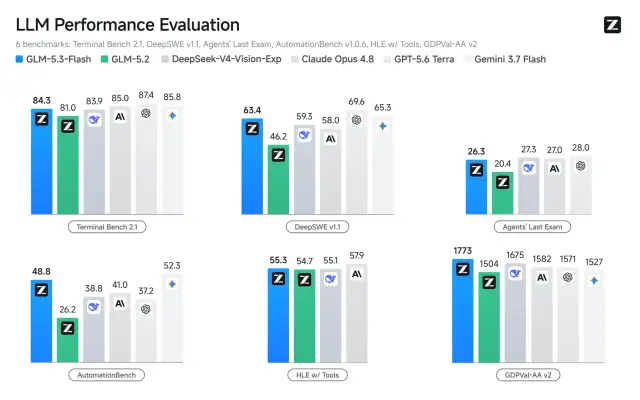
GLM-5.3-Flash
MIT multimodal MoE (card 320B/18B, 1M context) from Z.ai’s GLM-5 series.
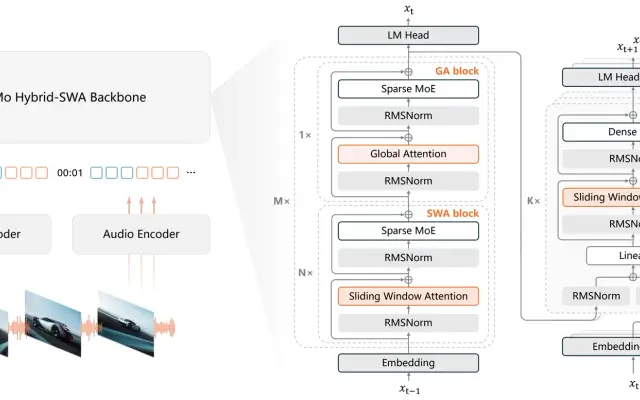
MiMo-V2.6-Flash
Xiaomi MIT Flash-RL MoE (card 309B/15B, 1M) with text, image, video, and audio.
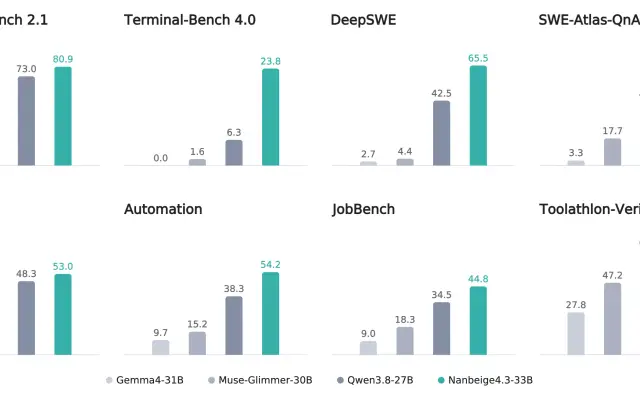
Nanbeige4.3-33B
Apache-2.0 33B text agent teacher from Nanbeige (BOSS Zhipin) with 512K context.
Qwen3.8-27B
Apache-2.0 27B native vision-language model from Qwen with 262K context.
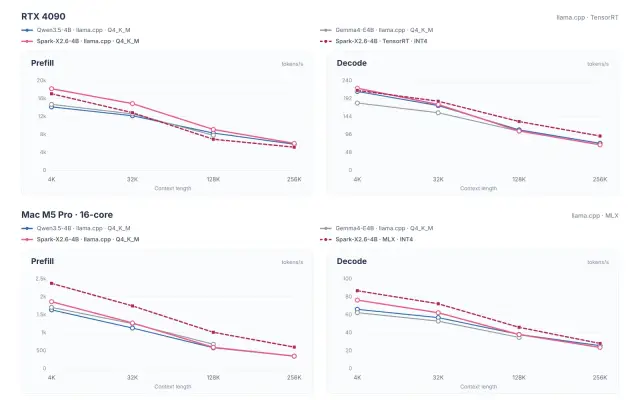
Spark-X2.6-4B
XHToken Apache-2.0 ~4B on-device agent/coding LLM. Not Meta Muse Spark Open.
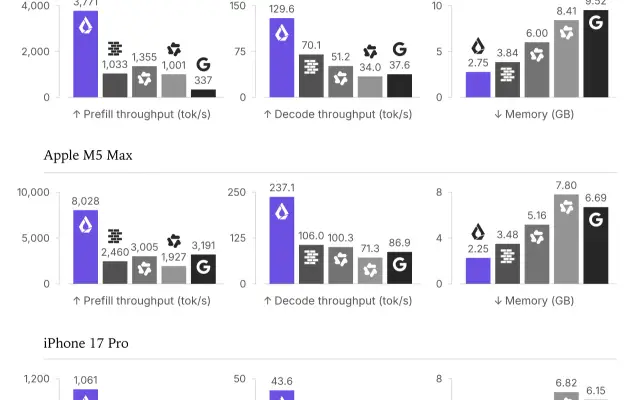
LFM3
Liquid AI ~2B edge family (text/VL/audio/omni/d1). Not LFM2.5-24B-A2B.
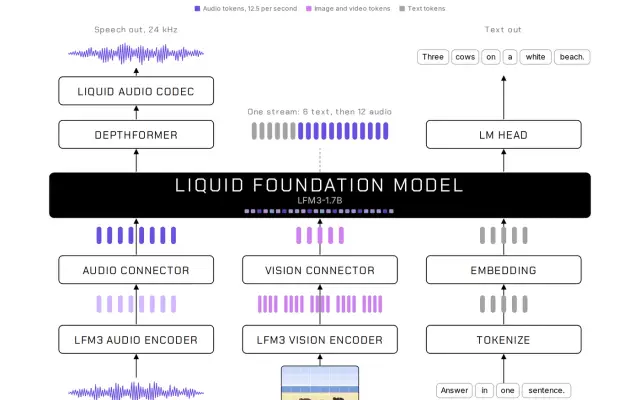
LFM3-Omni-2B
Liquid AI 2.17B omni — text/image/video/audio in, text+speech out. Not LFM3-1.7B or LFM2.5.
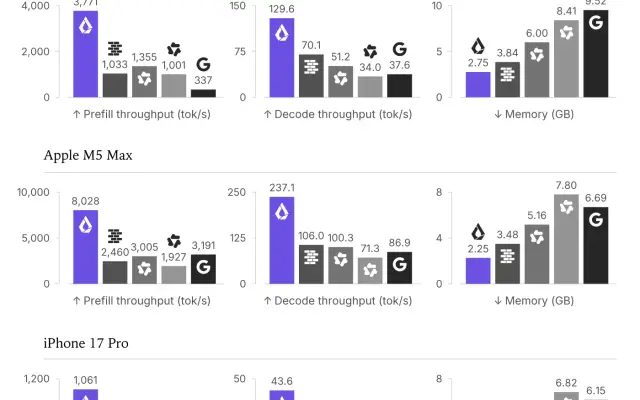
LFM3-1.7B
Liquid AI 1.73B edge text LLM, 256K. Not LFM3-Omni-2B and not LFM2.5.
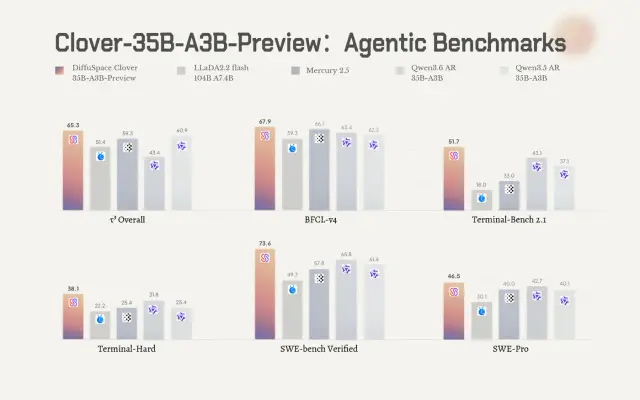
Clover-35B-A3B-Preview
DiffuSpace Apache-2.0 diffusion-language MoE (~35B/3B active), 128K, from Qwen3.6-35B-A3B.
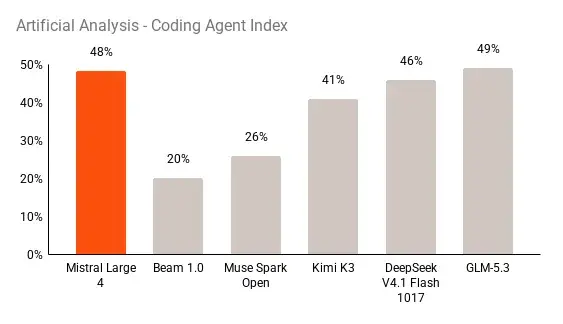
Mistral Large 4
Mistral ~1T/52B ungated multimodal MoE (text+image→text), 1M context. Le Chonk.
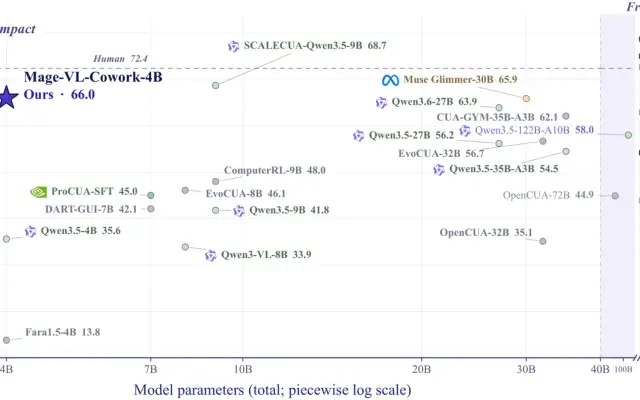
Mage-VL-Cowork
Microsoft Apache-2.0 ~4.7B hybrid computer-use VLM (GUI + bash). Not T2I.
Granite Switch 4.1
IBM Apache-2.0 modular 8B+30B Switch — chat, decision aLoRA, embedded ASR.
FAQ
Is there a free open-source ChatGPT alternative I can run locally?
Sourced rows, not a ranking. DeepSeek-V4.1-Flash-1017 publishes MIT weights (1,333 likes on the 1017 card as of 2026-10-19; original Flash card still has 4,635). Reflection Beam publishes ungated Apache-2.0 501.3B/23.4B text weights (148 likes; opened 2026-10-16). Kimi K3 publishes ungated 2.8T/104B multimodal weights under the Kimi K3 License (11,761 likes). MiniCPM-V 4.7 is Apache-2.0 on-device VLM. Muse Spark Open is gated Meta 816B/42B. Spark-X2.6-4B is a different project: XHToken’s ungated Apache-2.0 ~4B on-device agent (514 likes, 2026-10-26). “Locally” means the weights are downloadable (Muse after a manual gate); datacenter-class VRAM is vendor-quoted, not measured here.
Does it match ChatGPT quality?
We have no sourced bake-off against ChatGPT. The DeepSeek card and the Muse Spark Open card include self-reported tables versus named models; those are upstream, not a ChatGPT verdict.
Why isn’t Kolibri-1 on this list?
Kolibri-1 is an open MoE on the separate closed-LLM-API hub. This ChatGPT hub lists DeepSeek-V4.1-Flash, MiniCPM-V 4.7, and Muse Spark Open. Both hubs link to each other.
What is the license?
MIT on DeepSeek-V4.1-Flash-1017 as of 2026-10-19. Apache-2.0 on Reflection Beam, MiniCPM-V 4.7, and Hy-Memory as of 2026-10-19. Kimi K3 License (SPDX other) with a USD 20 million MaaS agreement trigger as of 2026-10-19. Muse Spark Open is the Muse Model License (SPDX other) with a USD 20 million MaaS notification threshold. OpenMDW-1.1 on Nemotron 3.5 Super VL and Bolt. Not legal advice.
Open WebUI vs ChatGPT — is the UI enough?
Open WebUI (156,173 stars, v0.12.3, custom branding-restricted license), LibreChat (MIT, 45,991 stars), and Jan (Apache-2.0, 45,014 stars) are self-hosted or desktop UIs. They are not ChatGPT. See Open WebUI vs ChatGPT. No writing-quality rank.
Is Muse Spark Open gated?
Yes. meta-models/Muse-Spark-Open-816B-A42B is gated: manual on Hugging Face (264 likes / 402 downloads in the 2026-10-16 API check). The NVFP4 sibling is also gated: manual. Accept the Muse Model License form on the card before download. Do not confuse it with Spark-X2.6-4B (XHToken, ungated Apache-2.0 ~4B).
What is Spark-X2.6-4B?
XHToken / SparkLLM Team’s ungated Apache-2.0 ~4B on-device agent/coding LLM (514 likes / 3,488 downloads, 2026-10-26). Not Meta Muse Spark Open. See Spark-X2.6-4B vs LFM2.5-24B-A2B. Not a ChatGPT ranking.
What is LFM3?
Liquid AI’s ~2B-class edge family (text 1.73B / 256K plus VL, Audio, Omni, d1) announced 27 October 2026 under LFM Open License v1.0. 160 likes on LFM3-1.7B as of 2026-10-28. Not LFM2.5-24B-A2B. See LFM3 vs LFM2.5-24B-A2B. Not a ChatGPT ranking.
What is LFM3-Omni-2B?
Liquid AI’s ungated omni checkpoint (2.17B, 32K, text/image/video/audio in, text+speech out) under LFM Open License v1.0. 227 likes as of 2026-10-31. Not LFM3-1.7B text and not LFM2.5-24B-A2B. Not a ChatGPT ranking.
What is Clover-35B-A3B-Preview?
DiffuSpace’s ungated Apache-2.0 diffusion-language MoE (35B / ~3B active, 128K) derived from Qwen3.6-35B-A3B. 176 likes as of 2026-10-31. See Clover-35B-A3B-Preview vs Flint. Not a ChatGPT ranking.
What is Mistral Large 4?
Mistral’s ungated Le Chonk checkpoint (mistralai/Mistral-Large-4-1T-A52B): ~1T total / 52B active including embeddings, text+image, 1M context, FP8 plus NVFP4. LICENSE is the Mistral Ecosystem Open-Weight License (modified MIT; Model-as-a-Service needs a separate commercial license). 1,301 likes as of 2026-10-30. See Mistral Large 4 vs Muse Spark Open. Not a ChatGPT ranking.
Sources & verification
- https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash-1017
- https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash
- https://api-docs.deepseek.com/news/news261017/
- https://huggingface.co/reflection/Beam-1.0-501B-A23B
- https://huggingface.co/moonshotai/Kimi-K3
- https://huggingface.co/tencent/Hy-Memory-30B-A3B
- https://www.deepseek.com/
- https://chat.deepseek.com/
- https://huggingface.co/openbmb/MiniCPM-V-4.7-35B-A3B
- https://github.com/OpenBMB/MiniCPM-V
- https://huggingface.co/meta-models/Muse-Spark-Open-816B-A42B
- https://research.meta.ai/blog/muse-spark-open
- https://dev.meta.ai/docs/muse-spark-open
- https://arena.ai/leaderboard/code/webdev?license=open-source
- https://huggingface.co/inclusionAI/Ling-3.1-flash
- https://huggingface.co/RecursiveSI/flint
- https://huggingface.co/InternScience/Sage-A1.5
- https://huggingface.co/HuggingFaceBio/Carbon-X
- https://huggingface.co/MiniMaxAI/MiniMax-M3.1-Flash
- https://huggingface.co/KRAFTON/Raon-1-mini-preview
- https://huggingface.co/zai-org/GLM-5.3-Flash
- https://huggingface.co/XiaomiMiMo/MiMo-V2.6-Flash-RL
- https://huggingface.co/Nanbeige/Nanbeige4.3-33B
- https://huggingface.co/Qwen/Qwen3.8-27B
- https://huggingface.co/XHToken/Spark-X2.6-4B
- https://github.com/XHToken/Spark-X2.6
- https://huggingface.co/LiquidAI/LFM3-1.7B
- https://www.liquid.ai/blog/lfm3
- https://huggingface.co/LiquidAI/LFM3-Omni-2B
- https://huggingface.co/Diffuspace/Clover-35B-A3B-Preview
- https://huggingface.co/mistralai/Mistral-Large-4-1T-A52B
- https://huggingface.co/mistralai/Mistral-Large-4-1T-A52B/raw/main/LICENSE
- https://mistral.ai/news/mistral-large-4-oss/
- https://huggingface.co/blog/mistral-large4
- https://huggingface.co/LiquidAI/LFM3-1.7B
- https://huggingface.co/microsoft/Mage-VL-Cowork
- https://huggingface.co/ibm-granite/granite-switch-4.1-8b
License notes are not legal advice. Read the original LICENSE. Trademark & disclaimer.