
MITmultimodalRuns locally552B backbone
DeepSeek-V4.1-Flash: Specs, License & How to Run
MIT multimodal MoE (552B backbone, 8B/16B active, 1M context); 1017 checkpoint opened 2026-10-17.
- License
- MIT
- Parameters
- 552B backbone (active 8B prefill / 16B decode)
- HF likes
- 1,970 (2026-10-21)
- First seen
- 2026-09-10
TL;DR. DeepSeek-V4.1-Flash is a multimodal model from DeepSeek-AI. Parameters: 552B backbone (active 8B prefill / 16B decode).License: MIT. It is listed under ChatGPT, Closed LLM APIs.
| Developer | DeepSeek-AI |
|---|---|
| Type | multimodal |
| Architecture | Causal Encoder-Decoder (CED) multimodal MoE; 40-layer Transformer (20-layer causal encoder + 20-layer decoder); CSA2; 1 shared expert and 384 routed experts, 6 routed experts activated per token (original Flash README) |
| Parameters | 552B backbone · active 8B prefill / 16B decode |
| Modalities | text, image |
| Context | 1M |
| License | MIT — MIT on the 1017 Hugging Face LICENSE file, card, and README (“This repository and the model weights are licensed under the MIT License”) as of 2026-10-21. Same MIT tag on the original Flash card. Not legal advice. |
| Hardware | Not yet verified — Family README documents a 552B backbone and 1M context. 1017 HF API usedStorage is 510,296,920,807 bytes (~475 GiB on disk); safetensors.parameters sum to 763,205,315,794 (UI “model size” line territory — we keep the README 552B backbone / Engram split and do not reconcile). Peak VRAM is not independently measured. README points at inference/ for weight conversion. (not independently tested) |
| Hugging Face likes | 1,970 (as of 2026-10-21) |
| Model card | https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash-1017 |
| First seen | 2026-09-10 |
DeepSeek-V4.1-Flash is a multimodal Mixture-of-Experts family from DeepSeek-AI. This page was first published from the original card on 2026-10-13. It was re-verified 2026-10-19 against the 1017 checkpoint, and re-checked 2026-10-21 against the same official card, LICENSE, news post, and DeepInfer.
Official hosts we opened on 2026-10-21: deepseek-ai/DeepSeek-V4.1-Flash-1017 (created 2026-10-17, not gated, MIT; 1,970 likes / 27,737 downloads), the LICENSE, DeepSeek’s 1017 news post, the original card deepseek-ai/DeepSeek-V4.1-Flash (created 2026-09-10, still online; 4,674 likes / 1,431,582 downloads), deepseek-ai/deepseek-recipe (1,598 stars, MIT), and deepseek-ai/DeepInfer (Apache-2.0, 13,104 stars). There is still no GitHub repository named deepseek-ai/DeepSeek-V4.1-Flash or …-1017 that we opened as a weights host.
This page is listed under ChatGPT alternatives and closed LLM APIs. Head-to-head with Z.ai’s MIT 320B/18B multimodal MoE: GLM-5.3-Flash vs DeepSeek-V4.1-Flash. Head-to-head with MiniMax’s October 2026 Community License MoE: MiniMax M3.1 Flash vs DeepSeek-V4.1-Flash. Versus Moonshot’s open 2.8T-class MoE: DeepSeek-V4.1-Flash vs Kimi K3. Versus Meta: Muse Spark Open vs DeepSeek-V4.1-Flash. Versus Ornith’s MIT 122B coding/agent MoE: Ornith-1.5-122B vs DeepSeek-V4.1-Flash. Serving: DeepInfer, vLLM, DeepInfer vs vLLM. Agent runtime: DeepSeek Harness.
1017 checkpoint update — what changed
Re-opened 2026-10-21. Only facts printed on the official 1017 model card, LICENSE, DeepSeek news post, or Hugging Face API. Adjectives such as “substantial” or “faster” stay vendor. We did not invent a latency number.
What the 1017 card states changed (copied labels):
- The README calls 1017 “a minor update to DeepSeek-V4.1-Flash.”
- It claims improvements across reasoning, coding, agentic tasks, and visual benchmarks.
- It claims the model reduces task execution time and output length, “enabling users to complete tasks faster and at lower cost” and “advancing the performance–cost Pareto frontier across multiple agent harnesses.” No numeric speed or token-length delta is printed next to that sentence.
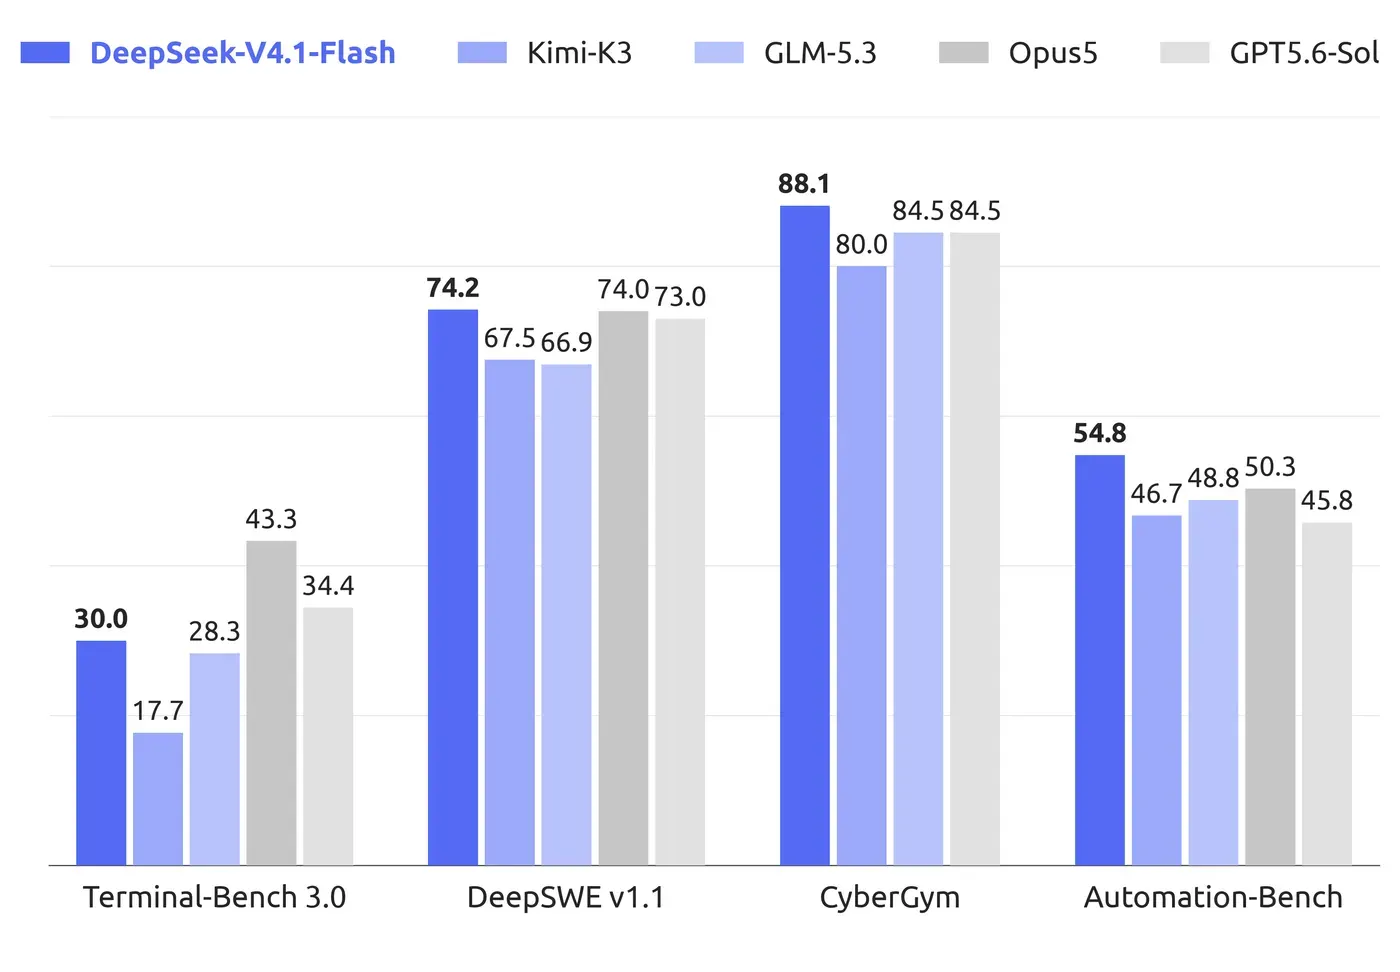
- A new self-reported instruct table compares 1017 with original Flash (and with K3 / GLM-5.3 / GPT-5.6 Sol / Opus 5 — those extra columns are DeepSeek’s table, not a forkalt ranking).
What the 17 Oct 2026 news post states (API docs, not the weight README):
- “Stronger benchmark performance, faster task completion, and shorter outputs than the previous version—a Pareto improvement in performance and cost.”
- “Now live on our website, app, and API.”
- Open-source hosts named: Hugging Face
deepseek-ai/DeepSeek-V4.1-Flash-1017and ModelScopedeepseek-ai/DeepSeek-V4.1-Flash-1017. - Search & Fetch API pricing on that post is API product news, not a statement about the MIT weight files.
What did not change (printed or unchanged on the 1017 card vs the original Flash card):
- MIT LICENSE;
cardData.license: mit; not gated; pipeline tagimage-text-to-text. - No Jinja chat template. Same recommended sampling: temperature 1.0, top_p 1.0, 1M context, max_tokens ≥ 256K.
- Architecture size is not restated. We keep the original README’s 552B backbone / 8B prefill / 16B decode / 1M context / 196B Engram quotes.
safetensorstotal remains 763,205,315,794. usedStorage is 510,296,920,807 bytes on 1017 vs 510,311,613,821 on the original card (HF API 2026-10-21). We do not invent a meaning for that 14.7 MB gap.
| Field | 1017 | Original Flash card | Source |
|---|---|---|---|
| Host | deepseek-ai/DeepSeek-V4.1-Flash-1017 |
deepseek-ai/DeepSeek-V4.1-Flash |
HF API |
| Created | 2026-10-17T02:40:38Z | 2026-09-10T02:17:58Z | HF createdAt |
| Last modified | 2026-10-17T05:46:55Z | 2026-10-16T09:27:28Z | HF API |
| Gated | false | false | HF API |
| Likes / downloads | 1,970 / 27,737 | 4,674 / 1,431,582 | HF API 2026-10-21 |
| License | mit | mit | HF cardData + LICENSE |
| Pipeline tag | image-text-to-text | image-text-to-text | HF API |
| usedStorage | 510,296,920,807 bytes | 510,311,613,821 bytes | HF API |
1017 README self-reported instruct table (full rows printed on the card we opened):
| Benchmark | 1017 | Original Flash (on 1017 card) |
|---|---|---|
| HLE w/o tools | 42.6 (44.0†) | 36.8 (39.1†) |
| Terminal-Bench 4.0 | 42.3 | 31.2 |
| DeepSWE v1.1 | 77.0 | 74.2 |
| ProgramBench | 29.1 | 20.3 |
| NL2Repo-Bench | 68.2 | 65.4 |
| Automation-Bench v1.0.6 | 60.5 | 54.8 |
| Agents’ Last Exam | 35.4 | 31.8 |
| Apex Bench v1.1 | 72.1 | 64.6 |
| Chartography (w/tools) | 83.0 | 78.9 |
| BabyVision (w/tools) | 92.5 | 89.6 |
| ZeroBench-main (w/tools) | 51.0 | 49.0 |
† denotes the text-only subset of HLE, per the 1017 README. Harness footnotes on that card: Claude Code for Terminal-Bench 4.0; Mini-SWE-V2 for DeepSWE v1.1. forkalt has not reproduced any row.
Arena.ai Code Arena WebDev (third-party, labeled)
The WebDev leaderboard with license=open-source, on the page we opened dated Oct 18, 2026 (900,155 votes, 58 open-source models), lists:
| Rank (open) | Overall | Model | Score | Votes | License (board) |
|---|---|---|---|---|---|
| 1 | 12 | DeepSeek-V4.1-Flash-20261017 (Max) | 1670 | 1,417 | MIT |
| 2 | 15 | Kimi K3 (Max) | 1655 | 19,426 | Kimi K3 license |
| 8 | 25 | DeepSeek-V4.1-Flash-20260910 (Max) | 1619 | 3,533 | MIT |
This is Arena.ai’s leaderboard, not a forkalt ranking. We do not treat “open-source #1” as a ChatGPT verdict or as an independent reproduction. The 1017 README extract we opened does not print that Arena rank; DeepSeek’s news post is the vendor announcement of the weights. See vs Kimi K3.
Architecture (original Flash README, still quoted)
Copied from the original card (checked first on 2026-10-13; architecture not contradicted by 1017): Causal Encoder-Decoder (CED), 40-layer Transformer (20-layer causal encoder + 20-layer decoder). CSA2 plus FP4 main KV caching is described as reducing global KV cache to 890 bytes per token. Vision encoder DeepSeek-ViT + two-layer MLP projector. Post-training: SFT → RL → on-policy distillation, with reasoning effort integer 1–100. Those sentences are upstream.
Hugging Face’s web UI has shown a “Model size 763B params” style line; 1017 safetensors.parameters sum to 763,205,315,794. We keep the README’s 552B backbone + 196B Engram quotes and do not invent a reconciliation.
How to run (from the 1017 README)
Recommended sampling copied from the 1017 card:
| Parameter | Value |
|---|---|
| temperature | 1.0 |
| top_p | 1.0 |
| context_window | 1M tokens |
| max_tokens | ≥ 256K |
No Jinja chat template. Prompt encoding: encoding/encoding.py on the card, production path deepseek-recipe (1,598 GitHub stars on 2026-10-21). Minimal inference: inference/ folder on the card.
The official serving framework published for this family is DeepInfer (Apache-2.0, 13,104 stars, 2026-10-21). Its README defaults to deepseek-ai/DeepSeek-V4.1-Flash-1017 and names NVIDIA SM100 / Huawei Ascend 950. Compare DeepInfer vs vLLM. Several other cards on this site still name vLLM (Apache-2.0, 94,459 stars, v0.32.0) or SGLang as a generic runtime; the 1017 Flash card itself points at inference/ and DeepSeek’s recipe, not a vLLM one-liner. forkalt has not executed those scripts.
Hosted chat.deepseek.com is a different artifact from downloading the MIT weights.
License
MIT, on the 1017 LICENSE file (copyright 2023 DeepSeek) and the README sentence “This repository and the model weights are licensed under the MIT License.” Same MIT tag on the original Flash card. Not legal advice.
What we did not invent
- Local VRAM, token throughput, and quantization recipes remain not independently measured.
- We do not invent a GitHub star count for a weights repo that 404s.
- We do not rank Flash against ChatGPT.
- Arena.ai ranks stay labeled third-party. DeepSeek table rows versus K3 / GLM-5.3 / GPT-5.6 Sol / Opus 5 stay self-reported.
Related: GLM-5.3-Flash — GLM-5.3-Flash vs DeepSeek-V4.1-Flash, MiniMax M3.1 Flash — MiniMax M3.1 Flash vs DeepSeek-V4.1-Flash, MiMo-V2.6-Flash, DeepSeek Harness, DeepInfer, vLLM, DeepInfer vs vLLM, Kimi K3, Reflection Beam, Muse Spark Open, Hy-Memory (uses DeepSeek V4.1 Flash as a named writer baseline in its own vendor table), Raon-1-mini. Self-hosted UIs: Open WebUI, LibreChat, Jan.
Benchmarks
Quoted from the cited source. forkalt has not independently reproduced these numbers.
| Name | Score | Source |
|---|---|---|
| Arena.ai Code Arena WebDev open-source rank (Flash-20261017 Max, 2026-10-18 snapshot) | 1670 (#1 open / #12 overall) | https://arena.ai/leaderboard/code/webdev?license=open-source |
| DeepSWE v1.1 (1017 card vs original Flash) | 77.0 (was 74.2) (self-reported) | https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash-1017 |
| Terminal-Bench 4.0 (1017 card vs original Flash) | 42.3 (was 31.2) (self-reported) | https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash-1017 |
Deploy options
Comparisons
FAQ
What is the 1017 checkpoint?
deepseek-ai/DeepSeek-V4.1-Flash-1017 is a minor update card created 2026-10-17T02:40:38Z (not gated; 1,970 likes / 27,737 downloads in the 2026-10-21 API check; MIT). DeepSeek’s API docs post “DeepSeek-V4.1-Flash-1017: Wish-Driven Programming Made Real” links that Hugging Face repo and ModelScope. The original deepseek-ai/DeepSeek-V4.1-Flash card remains online (created 2026-09-10; 4,674 likes / 1,431,582 downloads the same day).
How big is the model?
The original Flash README (still the architecture source we quote) says a multimodal MoE with 552B backbone parameters, activating 8B during prefill and 16B during decode, 1M-token context, plus Engram conditional memory (196B, sparsely accessed). The 1017 README does not reprint a different size. We do not invent a single “total params” figure beyond those quotes.
Is it
Arena.ai’s WebDev leaderboard with the open-source filter, on the page we opened dated 18 October 2026, lists DeepSeek-V4.1-Flash-20261017 (Max) at open-source rank 1 / overall rank 12, score 1670, MIT, 1,417 votes. That is a third-party leaderboard, not a forkalt ranking. The 1017 README’s own tables are vendor/self-reported. See vs Kimi K3.
Does it replace ChatGPT?
It is an open-weight multimodal chat/completion model in the same job family. We have no sourced side-by-side against ChatGPT.
Where is the GitHub repo for the weights?
GitHub still has no repository named deepseek-ai/DeepSeek-V4.1-Flash (or …-1017) that we opened as a weights host. Prompt encoding: github.com/deepseek-ai/deepseek-recipe (1,598 stars, MIT, in the 2026-10-21 GitHub check). Official inference framework: github.com/deepseek-ai/DeepInfer (Apache-2.0, 13,104 stars, same-day check).
Sources & verification
- https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash-1017
- https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash-1017/blob/main/LICENSE
- https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash
- https://api-docs.deepseek.com/news/news261017/
- https://github.com/deepseek-ai/deepseek-recipe
- https://github.com/deepseek-ai/DeepInfer
- https://github.com/vllm-project/vllm
- https://www.deepseek.com/
- https://arena.ai/leaderboard/code/webdev?license=open-source
License notes are not legal advice. Read the original LICENSE. Trademark & disclaimer.