
MITmultimodalRuns locally320B (card)
GLM-5.3-Flash: Specs, License & How to Run
MIT multimodal MoE (card 320B/18B, 1M context) from Z.ai’s GLM-5 series.
- License
- MIT
- Parameters
- 320B (card) (active 18B (card))
- HF likes
- 2,941 (2026-10-25)
- First seen
- 2026-08-25
TL;DR. GLM-5.3-Flash is a multimodal model from Z.ai. Parameters: 320B (card) (active 18B (card)).License: MIT. It is listed under ChatGPT, Closed LLM APIs.
| Developer | Z.ai |
|---|---|
| Type | multimodal |
| Architecture | Native multimodal MoE (HF model_type glm5_next; architecture Glm5NextForConditionalGeneration). Card: hybrid sparse + linear attention and Manifold-Constrained Hyper-Connections (mHC). text_config: 45 layers, hidden 4096, 288 routed experts, 8 active, 1 shared, max_position_embeddings 1,048,576. Vision: 24-layer glm5_next_vision. safetensors.parameters sum to 321,323,031,390. |
| Parameters | 320B (card) · active 18B (card) |
| Modalities | text, image, video |
| Languages | en, zh |
| Context | 1,048,576 tokens |
| License | MIT — LICENSE on the Hugging Face card is the MIT License, copyright 2026 Z.AI Co., Ltd. cardData.license is mit. The companion GitHub tree zai-org/GLM-5 is Apache-2.0 (code/docs, not a substitute for the weight LICENSE). Not legal advice. |
| Hardware | Not yet verified — Card usedStorage is 656,694,929,761 bytes (~612 GiB). Peak VRAM is not independently measured. README points at SGLang, vLLM, TokenSpeed, Transformers, KTransformers, and Unsloth. (not independently tested) |
| Hugging Face likes | 2,941 (as of 2026-10-25) |
| Model card | https://huggingface.co/zai-org/GLM-5.3-Flash |
| First seen | 2026-08-25 |
GLM-5.3-Flash is a natively multimodal Mixture-of-Experts model from Z.ai. Official hosts we opened on 2026-10-25: the ungated card zai-org/GLM-5.3-Flash (created 2026-08-25T06:43:14Z; last modified 2026-10-15T06:32:52Z; 2,941 likes / 6,377,661 downloads), the MIT LICENSE, the blog GLM-5.3-Flash, and the companion tree zai-org/GLM-5 (7,383 stars, 998 forks, Apache-2.0, last push 2026-10-15T01:36:08Z).
This page hangs off ChatGPT alternatives and closed LLM APIs. That mapping is editorial. We have no sourced quality comparison against ChatGPT. Head-to-head facts versus the MIT 1017 checkpoint already on this site: GLM-5.3-Flash vs DeepSeek-V4.1-Flash.
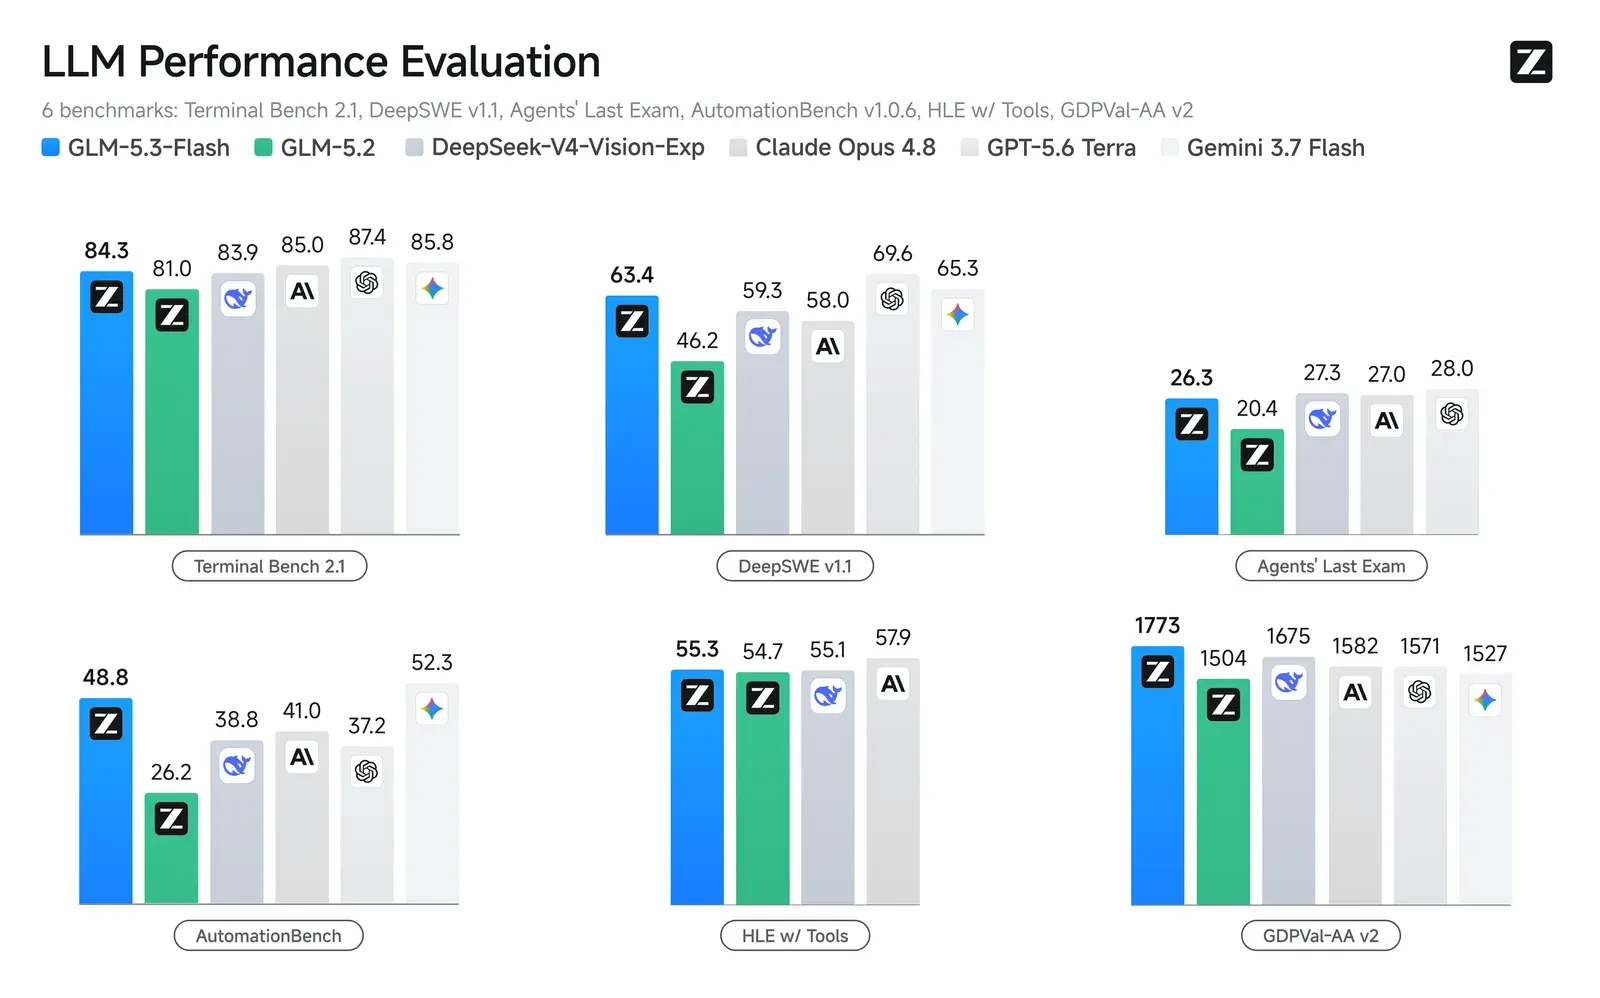
The card calls it the first natively multimodal model in the GLM-5 series. Inputs include text, image, and video; Hugging Face pipeline_tag is image-text-to-text. Vendor sentences about beating GLM-5.2 or approaching Claude Opus 4.8 stay vendor.
What we verified (2026-10-25)
| Field | Value | Source |
|---|---|---|
| Host | huggingface.co/zai-org/GLM-5.3-Flash (not gated) | HF API |
| Created / last modified | 2026-08-25T06:43:14Z / 2026-10-15T06:32:52Z | same |
| Likes / downloads | 2,941 / 6,377,661 | same |
| License tag + file | mit · MIT License (© 2026 Z.AI Co., Ltd) | HF cardData + LICENSE |
| Pipeline tag | image-text-to-text | HF API |
| Architecture | glm5_next (Glm5NextForConditionalGeneration) | card + HF config |
| Params (card) | 320B total / 18B activated | card |
| safetensors.parameters | 321,323,031,390 | HF API |
| usedStorage | 656,694,929,761 bytes (~612 GiB) | same |
| Context | 1,048,576 tokens (text_config.max_position_embeddings) |
HF config |
| Experts (config) | 288 routed, 8 active, 1 shared; 45 text layers | same |
| Companion GitHub | zai-org/GLM-5, 7,383 stars, Apache-2.0 | GitHub API |
Hugging Face’s UI can show a ~321B “model size” line from the safetensors sum. We keep the README’s 320B / 18B quote and do not invent a reconciliation — same pattern as DeepSeek-V4.1-Flash and MiniMax M3.1 Flash.
How to run (from the card, not tested)
Recommended serving frameworks copied from the README: SGLang, vLLM, TokenSpeed, Transformers, KTransformers, Unsloth.
README notes we copied:
reasoning_effortaccepts low, high, and max (default max if omitted). The card says to keep max for benchmark reproduction.- In the chat template,
clear_thinkingdefaults to false; the card says to passclear_thinking=truefor chat.
Hosted docs.z.ai is an API SKU. forkalt has not served the shards.
License
LICENSE is the MIT License, copyright 2026 Z.AI Co., Ltd. The README YAML and cardData.license also say mit. The GitHub tree zai-org/GLM-5 is Apache-2.0 and is not a substitute for the weight LICENSE. Not legal advice.
What we did not invent
- VRAM, tokens/s, and “one-tenth the price” stay vendor.
- The card’s
bench_53.pngfigure is identification, not a forkalt table. We do not OCR scores out of that PNG. - We do not rank GLM-5.3-Flash against ChatGPT or DeepSeek-V4.1-Flash.
Related: GLM-5.3-Flash vs DeepSeek-V4.1-Flash, DeepSeek-V4.1-Flash, MiniMax M3.1 Flash, MiMo-V2.6-Flash, Kimi K3, vLLM, DeepInfer vs vLLM. Self-hosted UIs: Open WebUI, LibreChat, Jan. Pixel-editor traffic on this site still lands on PhotoCraft vs GIMP — a different job.
Deploy options
- local: Hugging Face weights
- local: vLLM recipe (card)
- hosted: Z.ai API (separate SKU)
Comparisons
FAQ
Are the GLM-5.3-Flash weights actually public?
Yes on the host we opened. zai-org/GLM-5.3-Flash is ungated (created 2026-08-25T06:43:14Z; last modified 2026-10-15T06:32:52Z; 2,941 likes / 6,377,661 downloads in the 2026-10-25 API check). MIT LICENSE is in the same repo. Hosted Z.ai API SKUs are a different artifact.
Is this MIT?
Yes on the file we opened. The Hugging Face LICENSE is MIT (copyright 2026 Z.AI Co., Ltd). cardData.license is mit. zai-org/GLM-5 on GitHub is Apache-2.0 for the companion code tree. Not legal advice.
Does it replace ChatGPT or beat DeepSeek-V4.1-Flash-1017?
No sourced bake-off on this site. Vendor adjectives such as “outperforms GLM-5.2” or “approaching Claude Opus 4.8” stay vendor. Head-to-head facts we can copy: GLM-5.3-Flash vs DeepSeek-V4.1-Flash.
How big is it?
Card: 320B total / 18B active, 1M context. Hugging Face safetensors.parameters sum to 321,323,031,390. usedStorage 656,694,929,761 bytes. We keep the README 320B/18B quote and do not invent a reconciliation.
Sources & verification
- https://huggingface.co/zai-org/GLM-5.3-Flash
- https://huggingface.co/zai-org/GLM-5.3-Flash/blob/main/LICENSE
- https://z.ai/blog/glm-5.3-flash
- https://github.com/zai-org/GLM-5
- https://github.com/zai-org/GLM-5/blob/main/resources/bench_53.png
- https://github.com/vllm-project/vllm
License notes are not legal advice. Read the original LICENSE. Trademark & disclaimer.