
MITllmRuns locally122B (card)
Ornith-1.5-122B: Specs, License & How to Run
MIT 122B MoE coding/agent model with 262k context and OpenAI-style tool calling.
- License
- MIT
- Parameters
- 122B (card)
- HF likes
- 129 (2026-10-22)
- First seen
- 2026-10-16
TL;DR. Ornith-1.5-122B is a llm model from Ornith. Parameters: 122B (card).License: MIT. It is listed under ChatGPT, Closed LLM APIs, Claude Code.
| Developer | Ornith |
|---|---|
| Type | llm |
| Architecture | Mixture-of-Experts labeled 122B on the card. Hugging Face tags qwen3_5_moe and pipeline_tag text-generation. The card says Ornith-1.0 was developed on top of Qwen3.5 and Gemma4. |
| Parameters | 122B (card) |
| Modalities | text |
| Context | 262,144 tokens native (card); YaRN factor 4.0 ~1M (vendor) |
| License | MIT — Hugging Face cardData.license is mit and the YAML license_link points at blob/main/LICENSE (opened 2026-10-22). A resolve of that LICENSE path 404’d in this check; we follow the published card tag. Sibling FP8 and GGUF cards also tag mit. Not legal advice. |
| Hardware | 80 GB (vendor card) — The card says the 122B MoE “serves on a single 80GB GPU.” Hugging Face API usedStorage on the BF16 card is 250,188,099,758 bytes (~233 GiB); safetensors parameters sum to 125,086,497,008. The FP8 sibling usedStorage is 132,964,475,222 bytes. Peak VRAM is not independently measured. (not independently tested) |
| Hugging Face likes | 129 (as of 2026-10-22) |
| Model card | https://huggingface.co/ornith-ai/Ornith-1.5-122B |
| First seen | 2026-10-16 |
Ornith-1.5-122B is a Mixture-of-Experts coding and agent model from Ornith. Official hosts we opened on 2026-10-22: the ungated card ornith-ai/Ornith-1.5-122B (created 2026-10-16T07:14:27Z; 129 likes / 742 downloads), siblings Ornith-1.5-122B-FP8 (11 likes / 142 downloads) and Ornith-1.5-122B-GGUF (37 likes / 7,699 downloads), and the blog Ornith-1.5: From Self-Scaffolding to Self-Improvement. github.com/ornith-ai/Ornith-1.5-122B 404’d.
This page hangs off ChatGPT alternatives, closed LLM APIs, and Claude Code alternatives. That mapping is editorial. We have no sourced quality comparison against ChatGPT, Claude Code, or DeepSeek-V4.1-Flash. Head-to-head facts: Ornith-1.5-122B vs DeepSeek-V4.1-Flash, Flint vs Ornith-1.5-122B, Sage-A1.5 vs Ornith-1.5-122B.
The card calls it “the most capable and efficient member of the Ornith-1.5 family — a 122B MOE model designed for efficient single-GPU deployment,” with a quantized Ornith-1.5-122B-Mobile variant named for edge devices. Those adjectives stay vendor. Hugging Face pipeline_tag is text-generation; tags also include qwen3_5_moe.
What we verified (2026-10-22)
| Field | Value | Source |
|---|---|---|
| Host (BF16) | huggingface.co/ornith-ai/Ornith-1.5-122B (not gated) | HF API |
| Created / last modified | 2026-10-16T07:14:27Z / 2026-10-21T08:29:30Z | same |
| Likes / downloads | 129 / 742 | same |
| License tag | mit | HF cardData |
| LICENSE file fetch | resolve/main/LICENSE 404 | this check |
| Pipeline tag | text-generation | HF API |
| Architecture tag | qwen3_5_moe | HF tags |
| safetensors.parameters | 125,086,497,008 (~125.1B) | HF API |
| usedStorage (BF16) | 250,188,099,758 bytes (~233 GiB) | same |
| FP8 sibling | created 2026-10-20; 11 likes; usedStorage 132,964,475,222 | HF API |
| GGUF sibling | created 2026-10-20; 37 likes / 7,699 downloads | HF API |
| Native context | 262,144 tokens | card |
| Serving named | Transformers ≥ 5.8.1; vLLM ≥ 0.19.1; SGLang ≥ 0.5.9 | card |
| GitHub weights repo | 404 | GitHub API |
The card name is 122B. Hugging Face’s parameter sum is ~125.1B. We keep both quotes and do not invent a reconciliation.
How to run (from the card, not tested)
The card says Ornith-1.5-122B is a reasoning model: the assistant turn opens with a think block, and the recipes enable a reasoning parser (reasoning_content) plus a tool-call parser for <tool_call> → OpenAI-style tool_calls.
Recommended sampling (copied):
| Task | temperature | top_p | top_k | presence_penalty |
|---|---|---|---|---|
| General | 1.0 | 0.95 | 20 | 1.5 |
| Precise coding | 0.6 | 0.95 | 20 | 0.0 |
Both rows also list min_p=0.0 and repetition_penalty=1.0.
vLLM (Apache-2.0) recipe from the card:
vllm serve ornith-ai/Ornith-1.5-122B \
  --served-model-name Ornith-1.5-122B \
  --host 0.0.0.0 --port 8000 \
  --max-model-len 262144 \
  --gpu-memory-utilization 0.90 \
  --enable-prefix-caching \
  --enable-auto-tool-choice \
  --tool-call-parser qwen3_xml \
  --reasoning-parser qwen3 \
  --trust-remote-code
--trust-remote-code executes repository code. Read the repo first or pin a revision. forkalt has not run this.
SGLang recipe from the card (--tool-call-parser qwen3_coder, --reasoning-parser qwen3, --context-length 262144). This site does not yet have a dedicated SGLang tool page. DeepInfer is DeepSeek’s engine and, in the 2026-10-21 README check, names DeepSeek-V4.1-Flash only — not Ornith. Compare DeepInfer vs vLLM.
Other routes named on the card: ollama run ornith-1.5:122b; llama-server against ornith-ai/Ornith-1.5-122B-GGUF; OpenAI-compatible clients (Hermes, OpenClaw, OpenCode) pointed at http://localhost:8000/v1. Those are copied labels.
For windows beyond 262,144 tokens the card suggests YaRN (factor 4.0 ≈ 1M tokens) and warns that open-source runtimes apply the scale statically, which can hurt ordinary-length quality. Enable it only when the workload needs it.
License
Card tag MIT. Same tag on the FP8 and GGUF siblings. The published license_link is the card’s LICENSE blob; a raw fetch of that path 404’d on 2026-10-22. Not legal advice.
What we did not invent
- VRAM, tokens/s, and “efficient / SOTA” stay vendor.
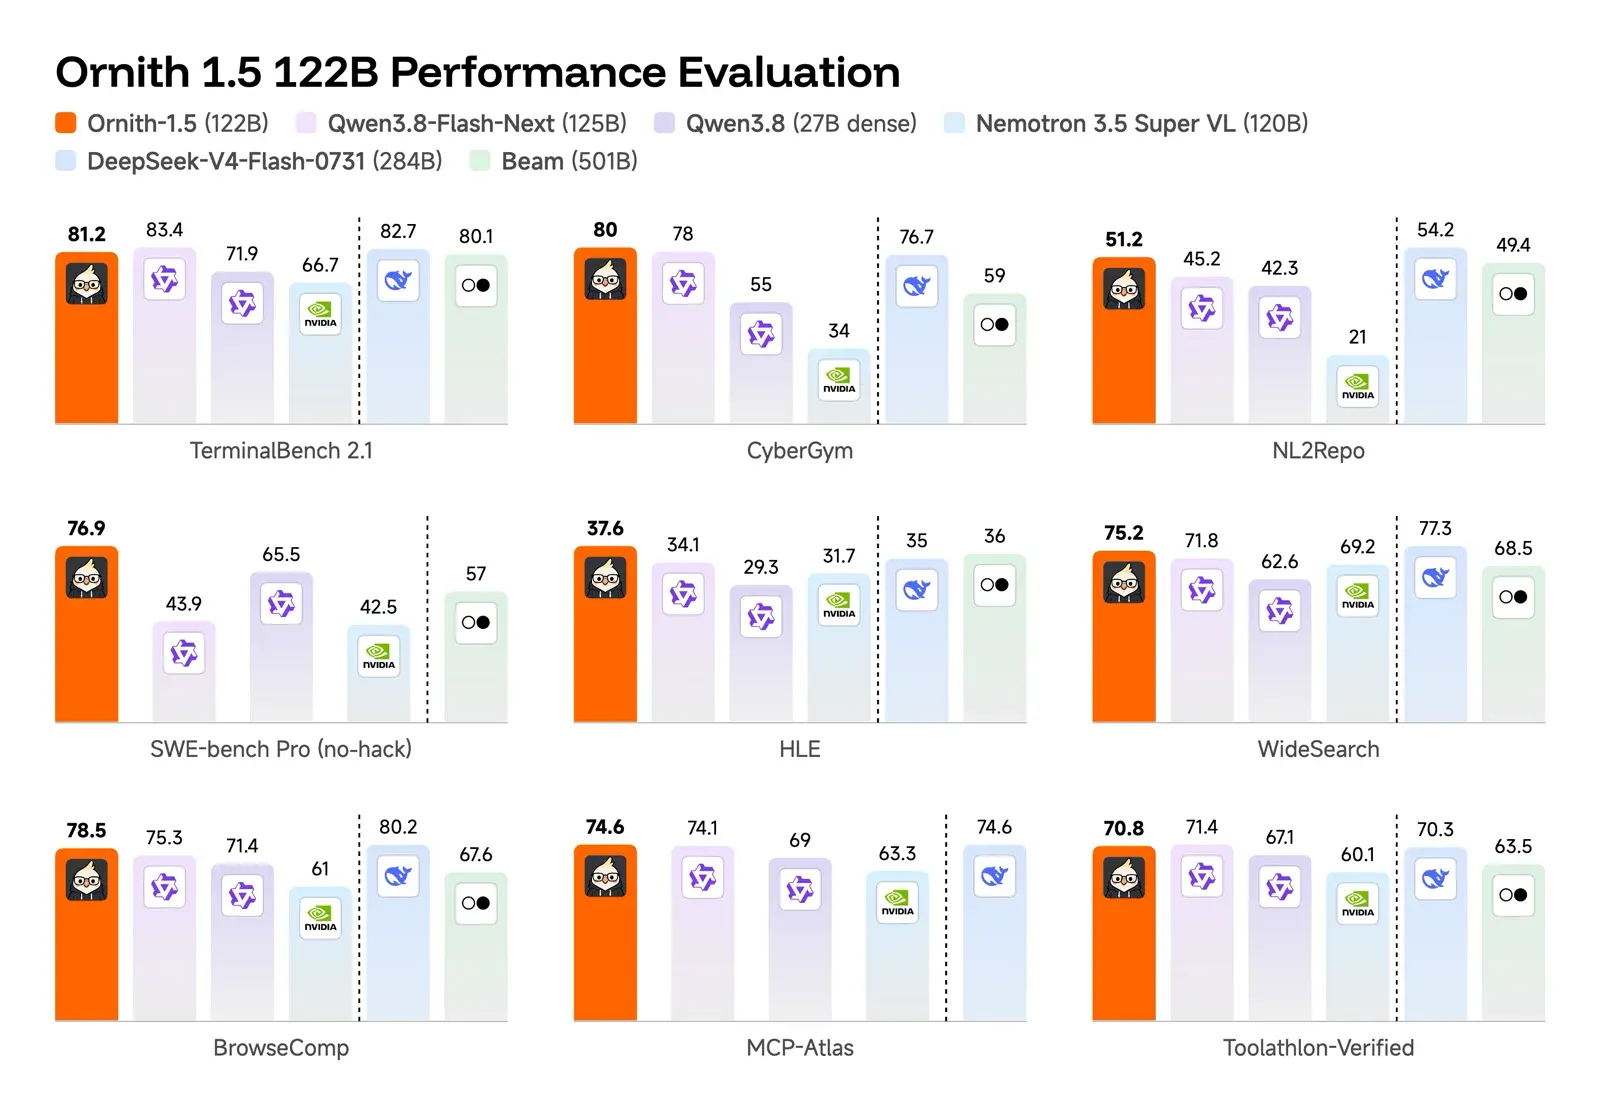
- Card table rows (SWE-bench, Terminal-Bench 2.1, CyberGym, HLE, WideSearch, …) stay self-reported.
- We do not rank Ornith against ChatGPT, Claude Code, or DeepSeek.
Pixel editors are a different job: PhotoCraft vs GIMP and the docs-based PhotoCraft install outline. Related models: Flint, Sage-A1.5, DeepSeek-V4.1-Flash, Reflection Beam, Ling-3.1-flash, Kimi K3. Serving: vLLM. UIs: Open WebUI, LibreChat, Jan.
Benchmarks
Quoted from the cited source. forkalt has not independently reproduced these numbers.
| Name | Score | Source |
|---|---|---|
| SWE-bench Verified (non-hack, card table) | 84.5 (self-reported) | https://huggingface.co/ornith-ai/Ornith-1.5-122B |
| SWE-bench Pro (no-hack, card table) | 76.9 (self-reported) | https://huggingface.co/ornith-ai/Ornith-1.5-122B |
| Terminal-Bench 2.1 (card table) | 81.2 (self-reported) | https://huggingface.co/ornith-ai/Ornith-1.5-122B |
| CyberGym (card table) | 80.0 (self-reported) | https://huggingface.co/ornith-ai/Ornith-1.5-122B |
Deploy options
- local: Hugging Face weights (BF16)
- local: Hugging Face weights (FP8)
- local: Hugging Face GGUF
- local: vLLM serve recipe (card)
- local: SGLang launch_server recipe (card)
Comparisons
FAQ
Is Ornith-1.5-122B open weight and MIT?
The ungated card ornith-ai/Ornith-1.5-122B (created 2026-10-16T07:14:27Z; 129 likes / 742 downloads in the 2026-10-22 API check) tags license mit. Sibling cards Ornith-1.5-122B-FP8 (11 likes) and Ornith-1.5-122B-GGUF (37 likes / 7,699 downloads) also tag mit. The YAML license_link 404’d when fetched as a raw file in this check. Not legal advice.
Does it really run on one 80 GB GPU?
That sentence is on the official card. We have not measured VRAM. BF16 usedStorage is ~233 GiB; the FP8 sibling is ~124 GiB on disk. Treat “single 80GB GPU” as vendor until a named-GPU run exists.
How do I serve it?
The card’s recipes use vLLM ≥ 0.19.1 or SGLang ≥ 0.5.9, with a 262,144 context, a Qwen3 reasoning parser, and a Qwen3 tool-call parser. See this site’s vLLM page. DeepInfer’s README (2026-10-21 check) lists DeepSeek-V4.1-Flash only — not Ornith. forkalt has not run the commands.
Does it beat DeepSeek-V4.1-Flash or ChatGPT?
No sourced bake-off on this site. Card benchmark rows are self-reported. See Ornith-1.5-122B vs DeepSeek-V4.1-Flash. We do not rank writing or coding quality against ChatGPT.
Is there a GitHub weights repo?
github.com/ornith-ai/Ornith-1.5-122B 404’d on 2026-10-22. Official hosts we opened are the Hugging Face cards and the Ornith-1.5 blog.
Sources & verification
- https://huggingface.co/ornith-ai/Ornith-1.5-122B
- https://huggingface.co/ornith-ai/Ornith-1.5-122B-FP8
- https://huggingface.co/ornith-ai/Ornith-1.5-122B-GGUF
- https://ornith.ai/ornith_1_5.html
- https://github.com/vllm-project/vllm
- https://github.com/sgl-project/sglang
- https://github.com/deepseek-ai/DeepInfer
- https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash-1017
License notes are not legal advice. Read the original LICENSE. Trademark & disclaimer.