
Ornith-1.5-122B vs DeepSeek-V4.1-Flash
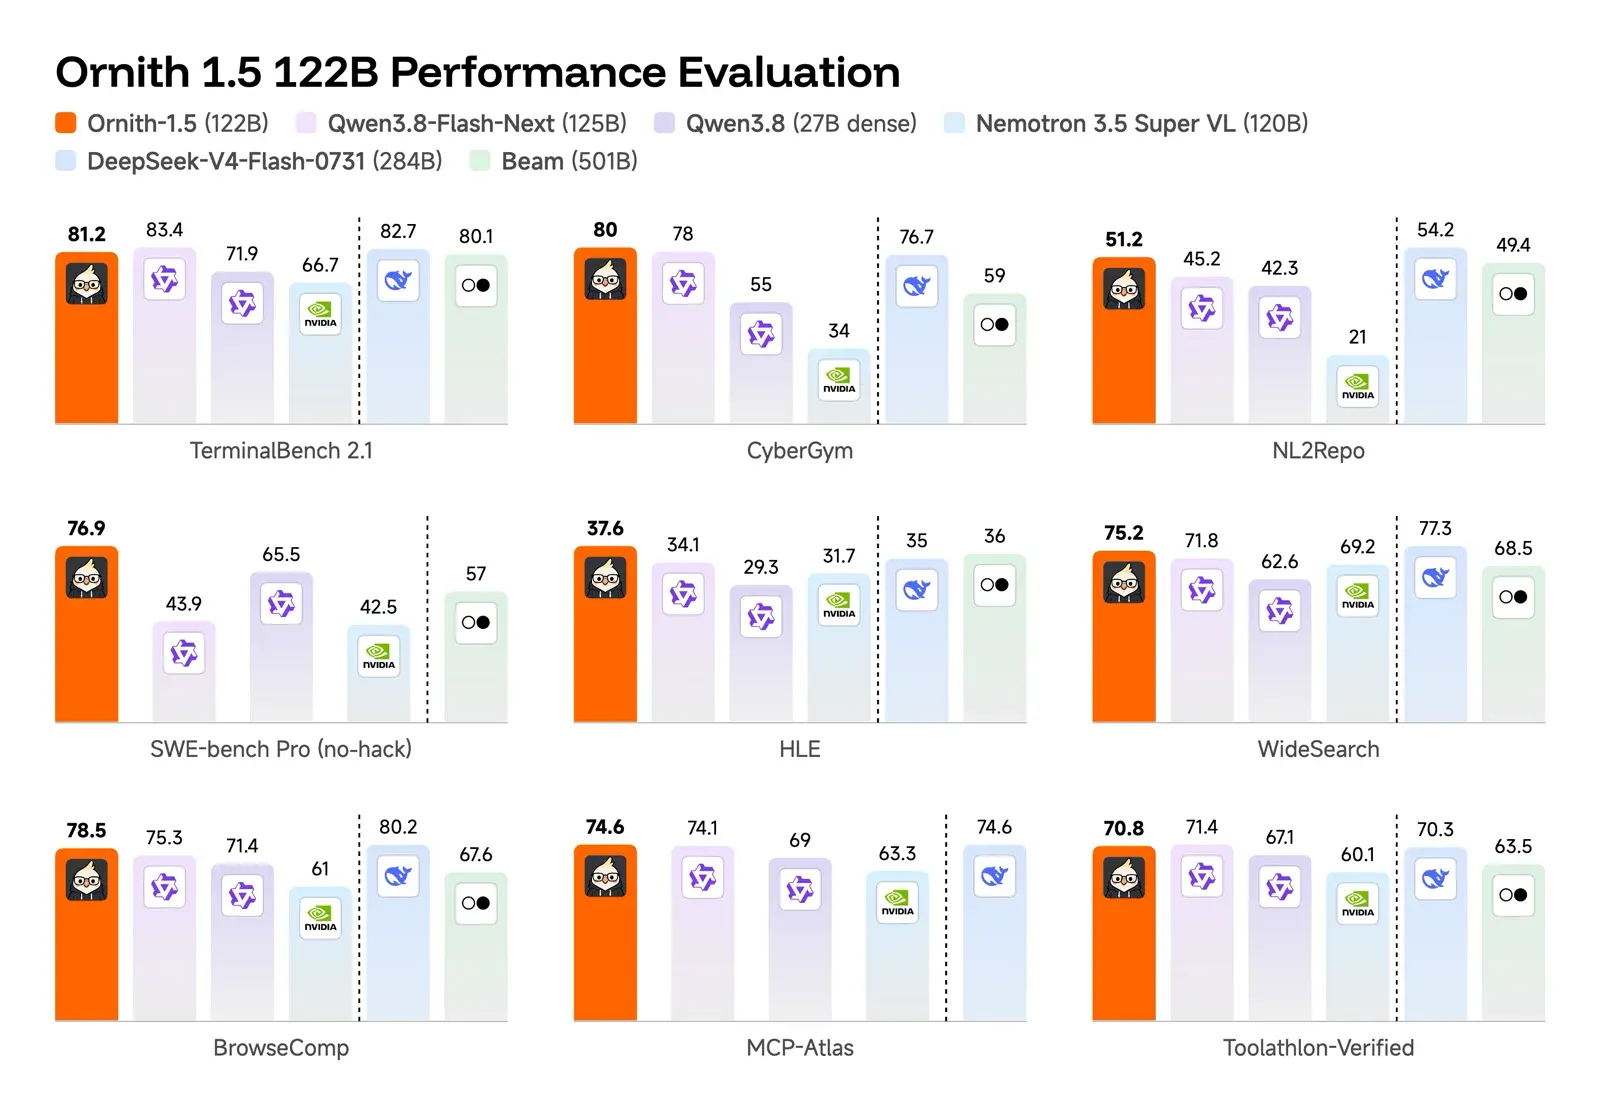
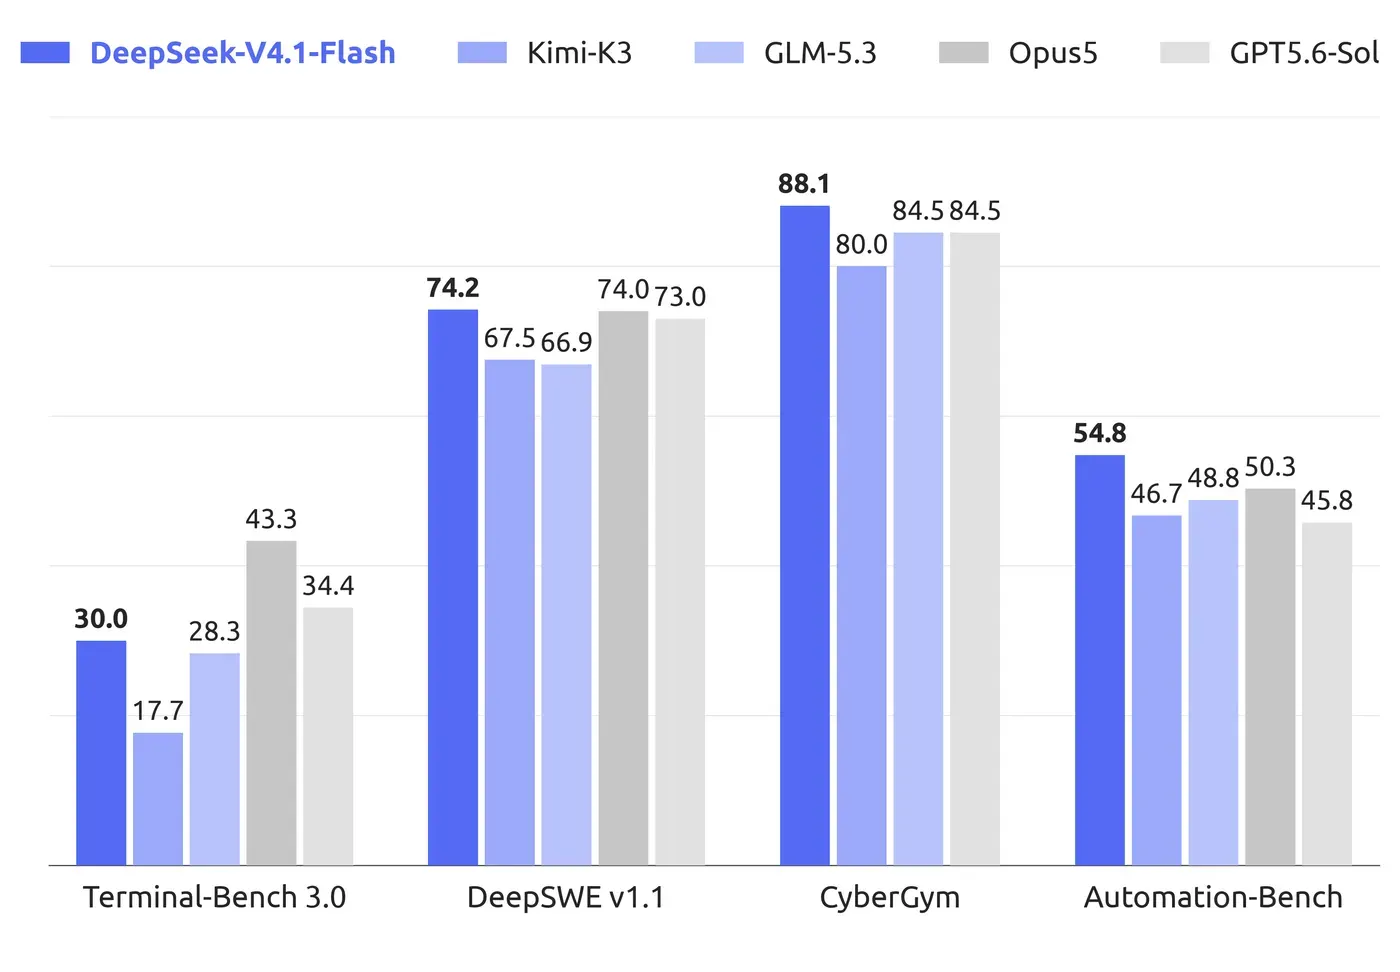
Compare Ornith-1.5-122B and DeepSeek-V4.1-Flash.
| Dimension | Ornith-1.5-122B | DeepSeek-V4.1-Flash | Source |
|---|---|---|---|
| License | MIT (HF card tag; LICENSE blob 404 on raw fetch) | MIT (1017 LICENSE file + README sentence) | Hugging Face cards (2026-10-22 / 2026-10-21) |
| Gating | No | No | Hugging Face API |
| Developer | Ornith | DeepSeek-AI | Official cards |
| Parameters | 122B MoE on the card; HF safetensors ~125.1B | 552B backbone; 8B prefill / 16B decode; 196B Engram (family README) | Official cards |
| Active parameters | Not stated on the card | 8B prefill / 16B decode | Official cards |
| Modalities | text-generation (HF pipeline); card focuses on coding/agents | Images + text in, text out | Official cards |
| Context length | 262,144 native; YaRN factor 4.0 ~1M (vendor) | 1M tokens | Official cards |
| Serving named | vLLM ≥ 0.19.1; SGLang ≥ 0.5.9; Transformers ≥ 5.8.1 | DeepInfer official; card inference/ folder; DeepSeek recipe | Official cards / READMEs |
| Hardware (vendor) | Single 80 GB GPU (card). BF16 usedStorage ~233 GiB. Untested here. | Datacenter-class 552B-backbone MoE. Peak VRAM unmeasured here. | Official cards; HF usedStorage |
| Hugging Face likes | 129 on the BF16 card (2026-10-22) | 1,970 on -1017; 4,674 on the original Flash card (2026-10-21) | Hugging Face API |
| Quality vs ChatGPT | Not independently tested | Not independently tested | n/a |
When to choose which
- Published single-80GB-GPU serve claim (vendor): Ornith-1.5-122B — Card sentence, not a forkalt VRAM measurement. BF16 usedStorage is ~233 GiB.
- Official DeepSeek inference stack: DeepSeek-V4.1-Flash — DeepInfer README (2026-10-21) lists Flash only. Ornith’s card points at vLLM/SGLang.
- Native 1M context without YaRN: DeepSeek-V4.1-Flash — Flash README 1M. Ornith native 262k; ~1M is a YaRN override.
- Multimodal (image + text in): DeepSeek-V4.1-Flash — Flash is image-text-to-text. Ornith’s pipeline_tag is text-generation.
- MIT coding/agent weights with a Qwen3 tool-call parser recipe: Ornith-1.5-122B — Card publishes vLLM/SGLang parser flags. Not a quality ranking.
Read the entity pages: Ornith-1.5-122B and DeepSeek-V4.1-Flash (1017 checkpoint). Both are listed on ChatGPT alternatives and closed LLM APIs. Ornith also hangs off Claude Code alternatives.
Why this comparison exists
Both families published MIT, ungated, coding-and-agent-oriented weights in 2026. Searchers who already know Flash need a same-site fact sheet for the newer 122B Ornith card (created 2026-10-16) versus the 1017 Flash checkpoint (created 2026-10-17). This is identification, not a bake-off.
Sourced snapshot (2026-10-22 / Flash 2026-10-21)
| Field | Ornith-1.5-122B | DeepSeek-V4.1-Flash-1017 |
|---|---|---|
| Host | huggingface.co/ornith-ai/Ornith-1.5-122B (not gated) | huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash-1017 (not gated) |
| HF likes / downloads | 129 / 742 (2026-10-22) | 1,970 / 27,737 (2026-10-21) |
| License | MIT (card tag) | MIT (LICENSE file) |
| Size | 122B MoE (card); ~125.1B safetensors | 552B backbone; 8B/16B active |
| Job | text-generation; coding/agents | Images + text in, text out |
| Context | 262,144 native | 1M |
| Official serve path | vLLM / SGLang recipes | DeepInfer + inference/ |
| Single-GPU claim | 80 GB (vendor) | Not claimed as a laptop/single-80GB SKU |
| Quality vs ChatGPT | Not independently tested | Not independently tested |
License
Both cards tag MIT. Flash-1017 has a fetchable LICENSE file (copyright 2023 DeepSeek). Ornith’s YAML license_link 404’d as a raw file on 2026-10-22; we still record the published mit tag. Not legal advice.
How to choose
- Need the 122B card and a vLLM / SGLang one-liner with Qwen3 parsers: Ornith-1.5-122B. Engine page: vLLM.
- Need DeepSeek’s 1017 multimodal checkpoint and DeepInfer: DeepSeek-V4.1-Flash — DeepInfer vs vLLM.
- Need Apache-2.0 US text MoE instead: Reflection Beam.
- Need MIT 560B/25B hybrid MoE: Ling-3.1-flash.
Pixel editors are a different job: PhotoCraft vs GIMP and How to install PhotoCraft. See also AI Chat & Agents.
FAQ
Which model is smaller / easier to host?
Ornith’s card says a 122B MoE on one 80 GB GPU. Flash is a 552B-backbone multimodal MoE. We have not measured either VRAM. Ornith BF16 usedStorage is still ~233 GiB; the 80 GB line is vendor.
Can I serve both with vLLM?
Ornith’s card publishes a vLLM ≥ 0.19.1 recipe. Flash’s 1017 card points at inference/ and DeepSeek’s recipe; this site’s Flash page also names DeepInfer as the official engine. See vLLM and DeepInfer vs vLLM. Untested here.
Which is better at SWE-bench or Terminal-Bench?
Both cards print self-reported tables. The harnesses, dates, and opponent columns differ. We do not merge them into a ranking.
Does either replace ChatGPT or Claude Code?
No sourced bake-off on this site. Both hang off those hubs as identification rows.
Sources & verification
- https://huggingface.co/ornith-ai/Ornith-1.5-122B
- https://huggingface.co/ornith-ai/Ornith-1.5-122B-FP8
- https://huggingface.co/ornith-ai/Ornith-1.5-122B-GGUF
- https://ornith.ai/ornith_1_5.html
- https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash-1017
- https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash
- https://github.com/deepseek-ai/DeepInfer
- https://github.com/vllm-project/vllm
License notes are not legal advice. Read the original LICENSE. Trademark & disclaimer.