
Apache-2.0freeRuns locallyDev & Coding
DeepInfer: DeepSeek Official Inference
Apache-2.0 official inference framework for DeepSeek models, released as offline serving.
- License
- Apache-2.0
- Stars
- 13,104 (2026-10-21)
- Platforms
- Linux, NVIDIA, Ascend, Python
- First seen
- 2026-10-16
TL;DR. DeepInfer is Apache-2.0 official inference framework for DeepSeek models, released as offline serving. License: Apache-2.0 (verified). Platforms: Linux, NVIDIA, Ascend, Python. Price: free. Runs locally: yes. It is an alternative to Closed LLM APIs, ChatGPT.
| Name | DeepInfer |
|---|---|
| Language | Python |
| License | Apache-2.0 |
| Pricing | free |
| Platforms | Linux, NVIDIA, Ascend, Python |
| Runs locally | Yes |
| Stats | 13,104 stars · 1,202 forks (as of 2026-10-21) |
| First seen | 2026-10-16 |
| Repository | https://github.com/deepseek-ai/DeepInfer |
DeepInfer is DeepSeek-AI’s published inference framework. Official hosts we opened on 2026-10-21: deepseek-ai/DeepInfer and the LICENSE. GitHub API that day: 13,104 stars, 1,202 forks, created 2026-10-16T07:47:23Z, last push 2026-10-20T11:03:36Z, language Python. Releases and tags lists were empty. GitHub license field: Apache-2.0.
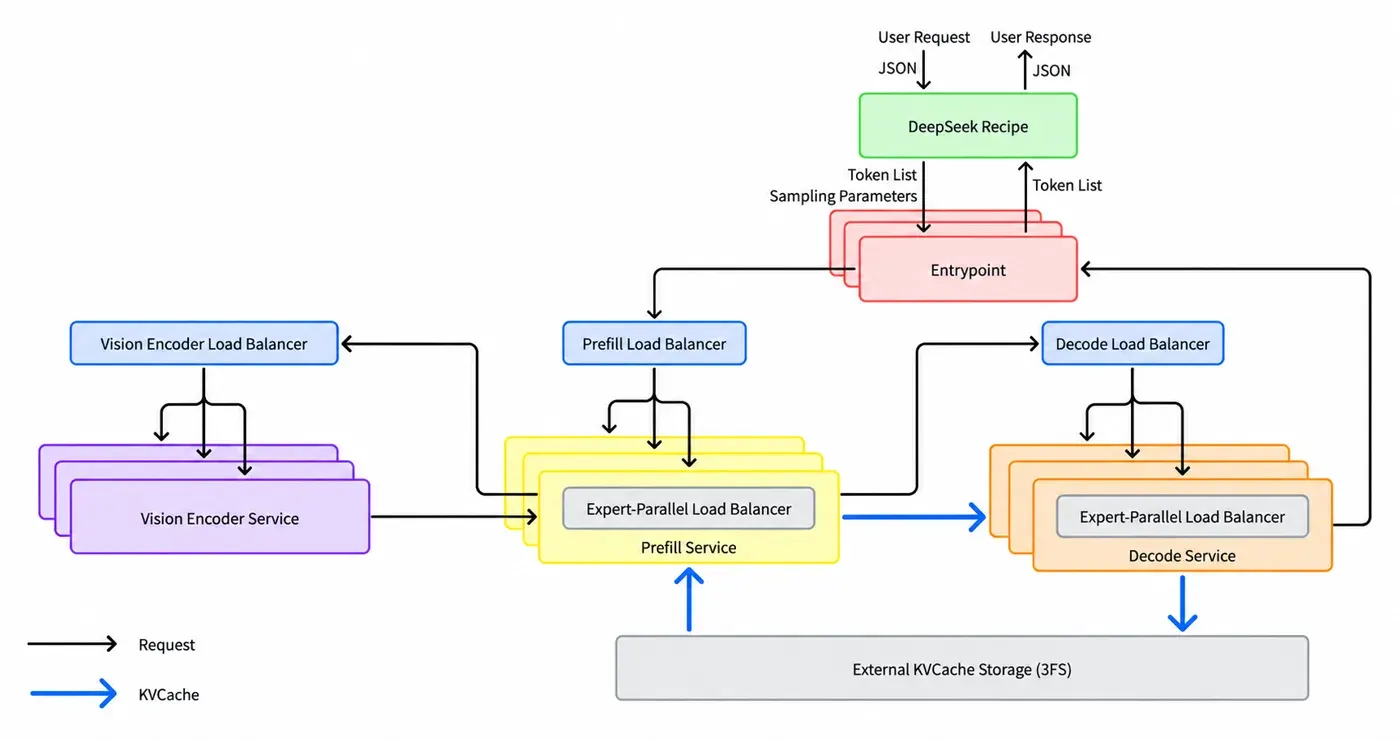
The README description: “High-performance, large-scale inference framework for DeepSeek models.” It says this open-source release provides offline inference with core serving features, and that a KV cache system, VE/Prefill/Decode disaggregation, and load balancing across data-parallel replicas are required for a complete inference service and not included in this release.
It hangs off closed LLM APIs and ChatGPT alternatives as a serving stack, not as a chat UI. Head-to-head: DeepInfer vs vLLM. The default checkpoint named on the README is DeepSeek-V4.1-Flash-1017. Self-hosted chat shells that can sit in front of an OpenAI-compatible server: Open WebUI, LibreChat, Jan.
Key facts (2026-10-21)
| Field | Value | Source |
|---|---|---|
| Stars / forks | 13,104 / 1,202 | GitHub API |
| Created | 2026-10-16T07:47:23Z | same |
| Last push | 2026-10-20T11:03:36Z | same |
| License | Apache-2.0 | LICENSE |
| Language | Python | GitHub |
| Latest release | none tagged | GitHub Releases / tags empty |
| Supported model named | DeepSeek-V4.1-Flash | README |
| Default checkpoint | deepseek-ai/DeepSeek-V4.1-Flash-1017 |
README |
| Hardware named | NVIDIA SM100 GPUs; Huawei Ascend 950 NPUs | README |
| Prerequisites named | Linux; GCC ≥ 13.0; Python 3.12; CUDA 13 (NVIDIA); CANN 9.2 (Ascend) | README |
README feature labels (copied, not measured): optimized kernels (FlashMLA, DeepGEMM, DeepEP, TileKernels, DeepSelect, TileLang); Attention DP / balanced CP; MoE EP + EPLB; DSpark and confidence-scheduled verification; SWA bounded replay; asynchronous scheduling; batch-invariant inference; deterministic sampling; structured outputs.
How to run (from the README, not tested)
Build from source after creating an empty Python 3.12 environment. The README’s NVIDIA path is export DEEPINFER_ACCELERATOR=nvidia then ./build.sh (use ascend on Ascend). Offline example: python examples/offline_inference.py. First run downloads the 1017 checkpoint into the Hugging Face cache unless DEEPINFER_HF_MODEL_DIR points at a local copy. forkalt has not built or served it.
Acknowledgments (upstream)
The README says DeepInfer was originally built primarily on vLLM, with additional inspiration from SGLang (37,519 stars, Apache-2.0, latest release v0.5.22 in the 2026-10-21 GitHub check) and TensorRT-LLM. Those are upstream credit lines, not a forkalt ranking.
What we did not invent
- Prefill/decode Pareto plots on 4 / 64 SM100 GPUs stay vendor. We did not rerun
examples/sweep/run_sweep.sh. - No tagged version to quote as “current release.”
- We do not claim DeepInfer is faster than vLLM or SGLang.
Related: vLLM, DeepInfer vs vLLM, DeepSeek-V4.1-Flash, Ling-3.1-flash (official SGLang / vLLM recipes), Hy-Memory (card names vLLM 0.31.0), Dev & Coding.
Comparisons
FAQ
Is DeepInfer open source?
Yes. LICENSE is Apache-2.0 (checked 2026-10-21). GitHub reports Apache-2.0. The README also says Apache License 2.0. Not legal advice.
Does it replace vLLM?
No bake-off. The README says DeepInfer was originally built primarily on vLLM, with additional inspiration from SGLang and TensorRT-LLM. This check lists DeepSeek-V4.1-Flash as the supported model. See DeepInfer vs vLLM.
Can I serve any Hugging Face model with it?
The README’s supported-models list on 2026-10-21 is DeepSeek-V4.1-Flash. The default checkpoint is deepseek-ai/DeepSeek-V4.1-Flash-1017. We did not find a general model zoo claim on that page.
Sources & verification
- https://github.com/deepseek-ai/DeepInfer
- https://github.com/deepseek-ai/DeepInfer/blob/main/LICENSE
- https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash-1017
- https://github.com/vllm-project/vllm
License notes are not legal advice. Read the original LICENSE. Trademark & disclaimer.