
DeepInfer vs vLLM: Which Should You Use?
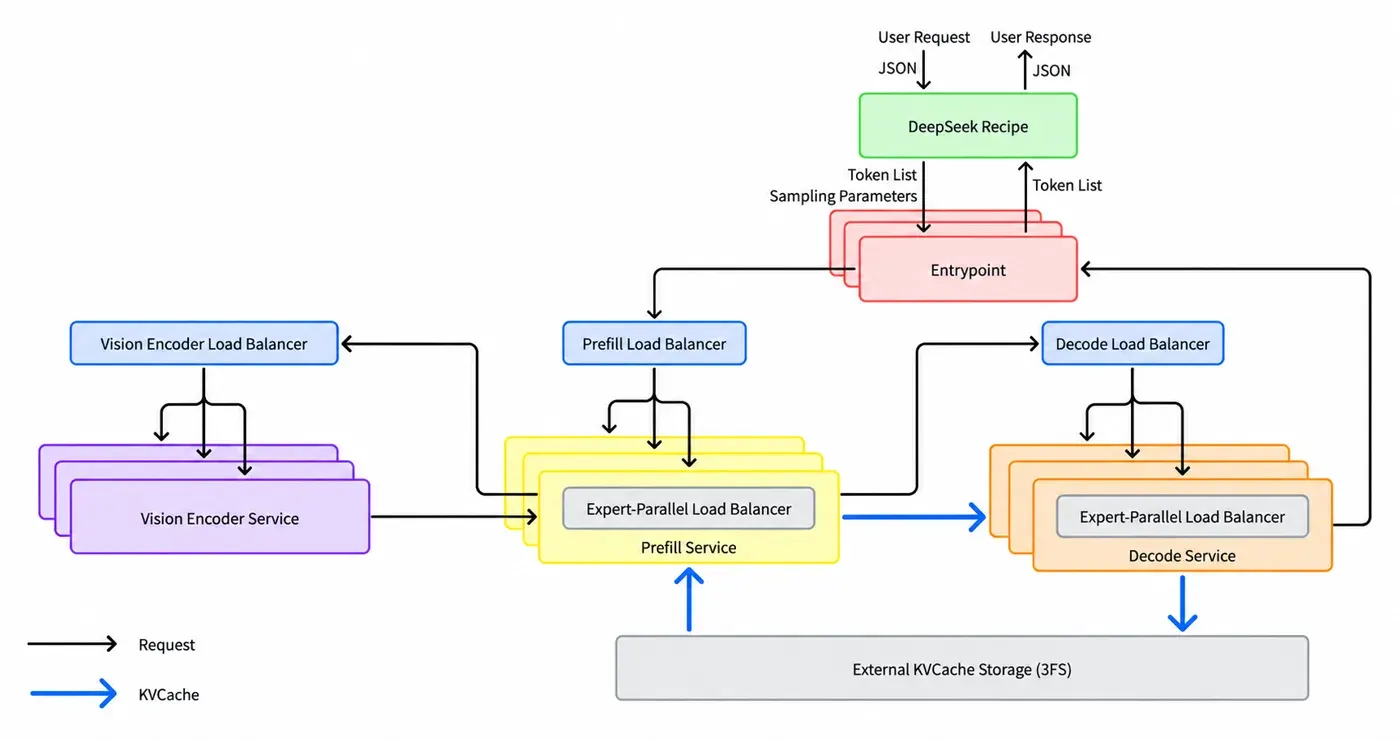
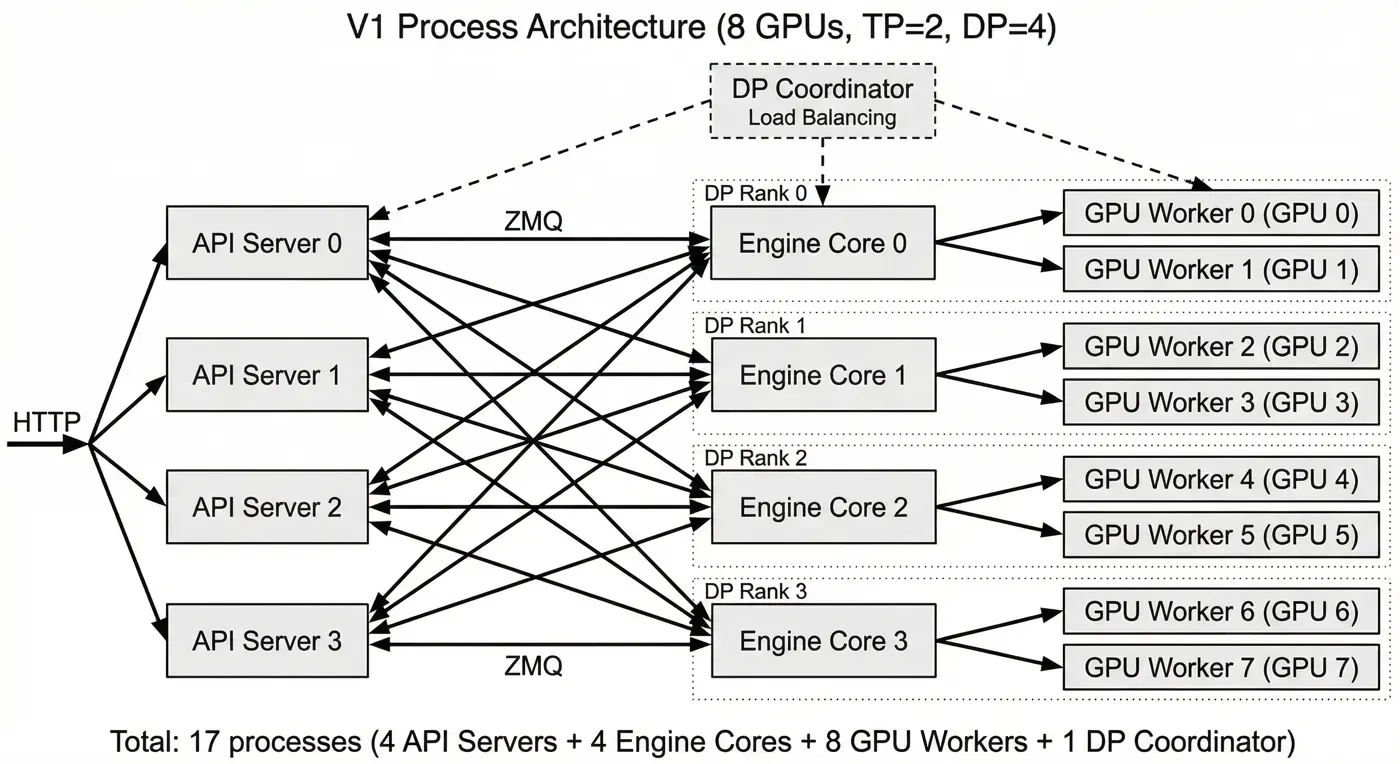
| Dimension | DeepInfer | vLLM | Source |
|---|---|---|---|
| License | Apache-2.0 (LICENSE, 2026-10-21) | Apache-2.0 (LICENSE, 2026-10-21) | Official LICENSE files |
| Scope named on README | DeepSeek-V4.1-Flash (default 1017 checkpoint) | 200+ Hugging Face architectures (README) | Project READMEs |
| Current release (this check) | no GitHub tag or release | v0.32.0 (2026-10-18) | GitHub Releases / tags |
| Community snapshot (2026-10-21) | 13,104 stars / 1,202 forks; created 2026-10-16; last push 2026-10-20 | 94,459 stars / 23,675 forks; created 2023-02-09; last push 2026-10-21 | GitHub API |
| Hardware named | NVIDIA SM100; Huawei Ascend 950 | NVIDIA, AMD, Intel GPUs, CPUs, plus named plugins | READMEs |
| What this OSS drop includes | offline inference; KV cache / PD disaggregation / DP load-balancing called out as not included | library + OpenAI-compatible API server (README) | READMEs |
| Relationship | README: originally built primarily on vLLM; also names SGLang and TensorRT-LLM | Independent project; DeepInfer credits it | DeepInfer README acknowledgments |
| Throughput vs each other | Not independently tested | Not independently tested | n/a |
When to choose which
- Serve DeepSeek-V4.1-Flash-1017 with the vendor engine: DeepInfer — Copied from the DeepInfer README default checkpoint. We did not build it.
- Serve many HF architectures behind OpenAI-compatible HTTP: vLLM — Copied README scope. We did not run vllm serve.
- Self-hosted chat UI in front of a server: Open WebUI — Different layer. See Open WebUI vs ChatGPT.
Read the entity pages for the sourced tables: DeepInfer and vLLM. Both hang off closed LLM APIs and ChatGPT alternatives. The DeepSeek weights page is DeepSeek-V4.1-Flash. Self-hosted UIs: Open WebUI, LibreChat, Jan — Open WebUI vs ChatGPT. Model cards that already name vLLM or SGLang: Ling-3.1-flash, Hy-Memory, Hy-SimulMT, Muse Spark Open, Nemotron 3.5 Super VL.
Key differences
DeepInfer is a DeepSeek-published Apache-2.0 engine (created 2026-10-16; no tag in this check). vLLM is a general Apache-2.0 server (v0.32.0). DeepInfer’s README credits vLLM as the primary original base and names SGLang and TensorRT-LLM as additional inspiration. Star counts are not quality. Pareto charts on the DeepInfer README stay vendor.
See also Dev & Coding.
FAQ
Is DeepInfer faster than vLLM?
We have no sourced bake-off. DeepInfer’s Pareto plots are vendor measurements on SM100.
Can I use both?
They are separate codebases. DeepInfer’s README says it was originally built primarily on vLLM; that is history, not a dual-install guide.
Where does SGLang fit?
Several model cards here name SGLang as a day-one runtime. GitHub sgl-project/sglang was Apache-2.0, 37,519 stars, v0.5.22 on 2026-10-21. This site has no dedicated SGLang tool page yet.
Sources & verification
- https://github.com/deepseek-ai/DeepInfer
- https://github.com/vllm-project/vllm
- https://github.com/sgl-project/sglang
- https://huggingface.co/deepseek-ai/DeepSeek-V4.1-Flash-1017
License notes are not legal advice. Read the original LICENSE. Trademark & disclaimer.