
Apache-2.0audioRuns locally30B
Hy-SimulMT: Specs, License & How to Run
Tencent Hunyuan open-source simultaneous speech MT (30B-A3B). Bidirectional Chinese–English.
- License
- Apache-2.0
- Parameters
- 30B (active 3B)
- HF likes
- 18 (2026-10-27)
- First seen
- 2026-10-22
TL;DR. Hy-SimulMT is a audio model from Tencent Hunyuan. Parameters: 30B (active 3B).License: Apache-2.0. It is listed under DeepL, Otter.ai.
| Developer | Tencent Hunyuan |
|---|---|
| Type | audio |
| Architecture | HYV3SpeechForCausalLM (config model_type hy_v3, num_experts 128, num_experts_per_tok 8). Card name 30B-A3B. Simultaneous speech-to-speech translation; speech output and voice cloning need a configured TTS service. |
| Parameters | 30B · active 3B |
| Modalities | audio, speech, text |
| Languages | zh, en |
| License | Apache-2.0 — Apache-2.0 on the Hugging Face card (license apache-2.0) and on LICENSE-Hy-SimulMT.txt (“Hy-SimulMT is licensed under Apache-2.0”) as of 2026-10-27. GitHub’s license API field is the opaque label “other”; we copy the LICENSE file. Not legal advice. |
| Hardware | Not yet verified — Card deploy path uses vLLM >=0.31 with HYV3ForCausalLM support, then SimulInfer. HF API safetensors.parameters total 30,394,794,496 (~30.39B); usedStorage 60,846,699,775 bytes (~56.7 GiB on disk). Peak VRAM is not independently measured. GGUF card reports context_length 262144. (not independently tested) |
| Hugging Face likes | 18 (as of 2026-10-27) |
| Model card | https://huggingface.co/tencent/Hy-SimulMT-30B-A3B |
| First seen | 2026-10-22 |
Hy-SimulMT is Tencent Hunyuan’s open simultaneous machine-translation stack: a 30B-A3B speech model plus SimulInfer (serve) and SimulTrain (continue-train). Official hosts we opened on 2026-10-27: tencent/Hy-SimulMT-30B-A3B, five siblings (FP8, GGUF, Interleave, Interleave-FP8, Interleave-GGUF), github.com/Tencent-Hunyuan/Hy-SimulMT (45 stars), and LICENSE-Hy-SimulMT.txt. Card news line: 2026.10.26 release. This is Tencent Hunyuan’s own checkpoint, not a community fine-tune.
This page hangs off DeepL alternatives (self-hosted translation search) and Otter.ai alternatives (live-speech search). Those mappings are editorial. DeepL is hosted text MT. Otter is a meeting-notes product. Hy-SimulMT is streaming speech-to-speech translation. We do not rank quality against DeepL, Otter, Interprefy, KUDO, or Google Live Translate.
Same Hunyuan line as Hy-Memory (30B-A3B memory writer). Different job. Do not treat them as overlapping products. Same-site speech peers: Hibiki-Zero (Kyutai 3B streaming S2ST, fr/es/pt/de→en) — Hibiki-Zero vs Hy-SimulMT — and Granite Speech 5.0 — Hy-SimulMT vs Granite Speech 5.0.
What the card says it does
Copied labels from the README we opened: real-time simultaneous translation; bidirectional Chinese–English speech-to-speech; continuous incoming audio; translated text and speech; optional real-time voice cloning that “preserves the speaker’s vocal characteristics.” Speech output and voice cloning require a configured TTS service. Meetings, speeches, and interviews are named as target settings. Those sentences are upstream.
Hugging Face cardData.language lists 38 tags (zh, en, plus fr, pt, es, ja, and others). The prose we opened claims only Chinese–English bidirectional simultaneous translation. We do not invent live coverage for the extra tags.
Family split (do not mix the ids)
| Card | Job (card table) | Likes (2026-10-27) | API notes |
|---|---|---|---|
| tencent/Hy-SimulMT-30B-A3B | Translation-only output | 18 | BF16; usedStorage ~56.7 GiB; not gated |
| tencent/Hy-SimulMT-30B-A3B-FP8 | Translation-only, FP8 | 3 | quant_method: fp8; usedStorage ~29.9 GiB |
| tencent/Hy-SimulMT-30B-A3B-GGUF | Translation-only, GGUF | 4 | Q4_K_M + Q8_0 siblings; context_length 262144 |
| tencent/Hy-SimulMT-30B-A3B-Interleave | Source text + translation | 5 | Same ~30.39B safetensors total |
| tencent/Hy-SimulMT-30B-A3B-Interleave-FP8 | Interleave, FP8 | 3 | quant_method: fp8 |
| tencent/Hy-SimulMT-30B-A3B-Interleave-GGUF | Interleave, GGUF | 6 | Q4_K_M + Q8_0 filenames |
All six cards were ungated in the 2026-10-27 API check. Downloads on the lead card were 0.
What we verified (2026-10-27)
| Field | Value | Source |
|---|---|---|
| HF likes / downloads | 18 / 0 | HF API tencent/Hy-SimulMT-30B-A3B |
| Card created / last modified | 2026-10-22T07:29:17Z / 2026-10-26T09:13:16Z | same |
| Gated | false | HF API |
| License (card) | apache-2.0 | HF cardData |
| LICENSE file | Apache-2.0 (Tencent preamble + Apache 2.0 terms) | GitHub LICENSE-Hy-SimulMT.txt; HF LICENSE.txt |
| GitHub license API | other | GitHub API (we still copy the file) |
| Pipeline tag | translation | HF API |
| Config | HYV3SpeechForCausalLM, hy_v3, 128 experts, 8 per token |
HF config |
| safetensors total | 30,394,794,496 (~30.39B) | HF API |
| usedStorage | 60,846,699,775 bytes (~56.7 GiB) | HF API |
| GitHub stars / forks | 45 / 5 | GitHub API |
| GitHub created / last push | 2026-10-22T07:24:21Z / 2026-10-26T08:56:14Z | same |
| Language | Python | GitHub API |
| Repo layout | SimulInfer/, SimulTrain/ |
GitHub contents |
| Official product page | error (IOXU3M) | hy.tencent.com detail URL from the card bibtex |
How to run (from official README, not yet tested)
Clone Tencent-Hunyuan/Hy-SimulMT, enter SimulInfer/, then the card’s one-command path:
bash deploy.sh --install-server --model tencent/Hy-SimulMT-30B-A3B-InterleaveCard: Linux, Python 3.12+, NVIDIA GPU, CUDA driver, vLLM >=0.31 with HYV3ForCausalLM support, plus simulst. Wait for Ready: http://127.0.0.1:8080/. Defaults named on the card: web/API port 8080, local model port 8800. Remote microphone access needs HTTPS. TTS is optional in deploy.toml. forkalt has not run that script.
GGUF / llama.cpp: the card says Hy-SimulMT support has not yet been merged into official llama.cpp and recommends waiting. A serve_llamacpp.py bridge is documented for an already-loaded GGUF server (MODEL_TYPE=target_only or source_target). Untested here.
The card also names a Hy Translate Android/iOS app. We did not install it.
License
Apache-2.0 on the HF card and on LICENSE-Hy-SimulMT.txt (“Hy-SimulMT is licensed under Apache-2.0”). GitHub’s license API key is other because of the Tencent preamble; we still record SPDX Apache-2.0 from the file. Not legal advice.
What we did not verify
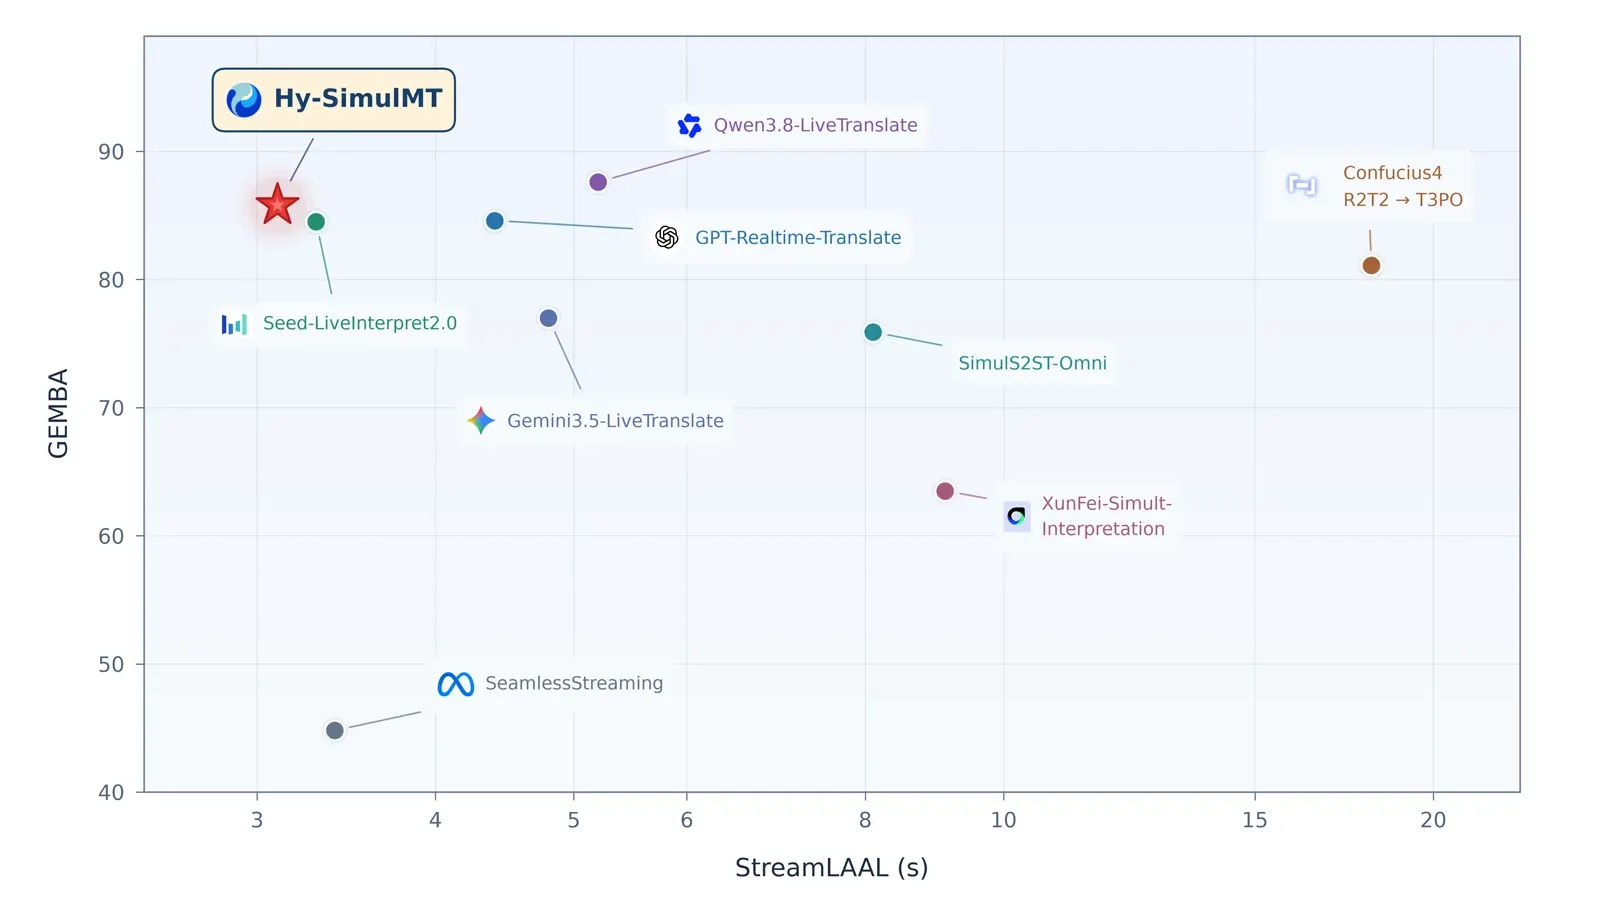
Vendor RealSI / FLEURS / CoVoST2 / ACL6060 / GEMBA / StreamLAAL rows stay self-reported. The card’s small-scale human-interpreter comparison is self-reported and limited to those samples. Peak VRAM, live latency on our hardware, voice-clone quality, and the extra HF language tags as live simultaneous pairs are not filled in with guesses. The Hunyuan product URL in the card bibtex returned an application error on 2026-10-27.
Related: Hibiki-Zero — Hibiki-Zero vs Hy-SimulMT, Granite Speech 5.0 — Hy-SimulMT vs Granite Speech 5.0, Nemotron 3.5 Transcribe (file ASR, not streaming S2ST) — Nemotron 3.5 Transcribe vs Granite Speech 5.0, Hy-Memory (Hunyuan 30B-A3B writer, not MT), LibreTranslate (text MT API), whisper.cpp, vLLM (named on the deploy path), DeepL alternatives, Otter.ai alternatives.
Benchmarks
Quoted from the cited source. forkalt has not independently reproduced these numbers.
| Name | Score | Source |
|---|---|---|
| RealSI StreamLAAL (vendor) | ~3 seconds (self-reported) | https://huggingface.co/tencent/Hy-SimulMT-30B-A3B |
| FLEURS (vendor table) | 90.3 (self-reported) | https://huggingface.co/tencent/Hy-SimulMT-30B-A3B |
| RealSI-Sentence (vendor table) | 84.7 (self-reported) | https://huggingface.co/tencent/Hy-SimulMT-30B-A3B |
Deploy options
Comparisons
FAQ
Is Hy-SimulMT an official Tencent Hunyuan model or a random fine-tune?
Official Tencent Hunyuan weights. The ungated card is huggingface.co/tencent/Hy-SimulMT-30B-A3B (created 2026-10-22T07:29:17Z; card news line 2026.10.26). The code host is github.com/Tencent-Hunyuan/Hy-SimulMT. It is not a third-party fine-tune of some other checkpoint. Same Hunyuan org as Hy-Memory; different job (simultaneous MT, not a memory writer).
Are the weights and inference code open?
Yes. The 30B-A3B card is ungated (18 likes / 0 downloads in the 2026-10-27 API check; card license apache-2.0). GitHub Tencent-Hunyuan/Hy-SimulMT has 45 stars / 5 forks (created 2026-10-22; last push 2026-10-26). LICENSE-Hy-SimulMT.txt says “Hy-SimulMT is licensed under Apache-2.0.” GitHub’s license API field is “other” because of the Tencent preamble; we still copy Apache-2.0 from the file.
Does it replace DeepL, Otter, or a paid interpreter booth?
No. DeepL is hosted text MT. Otter is a meeting-notes product. Hy-SimulMT is a local simultaneous speech-to-speech checkpoint plus SimulInfer. Card prose is bidirectional Chinese–English live translation. We have no sourced bake-off against DeepL, Otter, Interprefy, KUDO, or human interpreters. Hub mappings are editorial.
What is the Interleave sibling?
The family table on the card: 30B-A3B is “translation-only output.” 30B-A3B-Interleave is “source text and translation output.” Each has FP8 and GGUF siblings we opened (Q4_K_M and Q8_0 filenames). SimulInfer’s deploy example uses the Interleave id. Do not mix the ids.
Sources & verification
- https://huggingface.co/tencent/Hy-SimulMT-30B-A3B
- https://huggingface.co/tencent/Hy-SimulMT-30B-A3B-FP8
- https://huggingface.co/tencent/Hy-SimulMT-30B-A3B-GGUF
- https://huggingface.co/tencent/Hy-SimulMT-30B-A3B-Interleave
- https://huggingface.co/tencent/Hy-SimulMT-30B-A3B-Interleave-FP8
- https://huggingface.co/tencent/Hy-SimulMT-30B-A3B-Interleave-GGUF
- https://github.com/Tencent-Hunyuan/Hy-SimulMT
- https://github.com/Tencent-Hunyuan/Hy-SimulMT/blob/main/LICENSE-Hy-SimulMT.txt
License notes are not legal advice. Read the original LICENSE. Trademark & disclaimer.