
Hy-SimulMT vs Granite Speech 5.0
Compare Hy-SimulMT and Granite Speech 5.0.
| Dimension | Hy-SimulMT | Granite Speech 5.0 | Source |
|---|---|---|---|
| License | Apache-2.0 (card tag + LICENSE-Hy-SimulMT.txt) | Apache-2.0 (card tag; 5.0-2B siblings list had no LICENSE blob) | Hugging Face / GitHub (2026-10-27 / 2026-10-24) |
| Gating | No | No | Hugging Face API |
| Developer | Tencent Hunyuan | IBM | Official cards |
| Parameters | 30B-A3B; HF safetensors 30,394,794,496 | 2.3B on the 5.0-2B card; safetensors 2,313,207,132 | Official cards / HF API |
| Architecture | HYV3SpeechForCausalLM (128 experts, 8 per token) | granite_speech aligned from granite-4.0-1b-base | Official configs / cards |
| Job | Streaming simultaneous speech-to-speech (zh↔en prose) | File ASR + bidirectional AST; Plus sibling does speaker tags | Official cards |
| Serving named | SimulInfer + vLLM >=0.31; llama.cpp not yet merged | Transformers, vLLM, llama.cpp, mlx-audio (family blog) | Official cards / IBM blog |
| Hugging Face likes | 18 (lead card, 2026-10-27) | 48 (5.0-2B, 2026-10-24) | Hugging Face API |
| Quality vs DeepL / Otter | Not independently tested | Not independently tested | n/a |
When to choose which
- Live Chinese–English simultaneous interpretation: Hy-SimulMT — Card prose is streaming S2ST. Not a quality rank.
- File transcription or speech translation: Granite Speech 5.0 — 5.0-2B is ASR/AST on an audio file. Hy-SimulMT is a live stream stack.
- Speaker tags on a recording: Granite Speech 5.0 — Tags live on granite-speech-4.1-2b-plus, not on Hy-SimulMT.
- Compact ~2B checkpoint: Granite Speech 5.0 — Hy-SimulMT is 30B-A3B (~56.7 GiB BF16). Size is not a quality claim.
Read the entity pages: Hy-SimulMT and Granite Speech 5.0. Hy-SimulMT hangs off DeepL alternatives and Otter.ai alternatives. Granite hangs off Otter and Descript alternatives.
Why this comparison exists
Searchers who want open speech translation now have Hunyuan’s 30B-A3B simultaneous stack next to IBM’s 2.3B ASR/AST family. This is identification, not a bake-off. Paid interpreter booths (Interprefy, KUDO) are not pages here.
Sourced snapshot (2026-10-27)
| Field | Hy-SimulMT-30B-A3B | Granite Speech 5.0-2B |
|---|---|---|
| Host | huggingface.co/tencent/Hy-SimulMT-30B-A3B (not gated) | huggingface.co/ibm-granite/granite-speech-5.0-2b (not gated) |
| HF likes | 18 (2026-10-27) | 48 (2026-10-24) |
| License | Apache-2.0 (LICENSE file + card tag) | Apache-2.0 (card tag) |
| Size | ~30.39B safetensors; 30B-A3B name | ~2.31B safetensors |
| Job | Streaming simultaneous S2ST (zh↔en prose) | File ASR + bidirectional AST |
| Serve path | SimulInfer + vLLM >=0.31 | Transformers / vLLM (card); llama.cpp named on the family blog |
| Quality vs DeepL / Otter | Not independently tested | Not independently tested |
License
Both cards tag apache-2.0. Hy-SimulMT’s GitHub file says “Hy-SimulMT is licensed under Apache-2.0.” Granite 5.0-2B had no LICENSE blob in the siblings list we opened on 2026-10-24. Not legal advice.
How to choose
- Need live Chinese–English simultaneous speech-to-speech: Hy-SimulMT.
- Need live French / Spanish / Portuguese / German → English S2ST: Hibiki-Zero — Hibiki-Zero vs Hy-SimulMT.
- Need file ASR/AST or speaker tags on the Plus sibling: Granite Speech 5.0.
- Need NVIDIA 30B-class offline ASR (OpenMDW-1.1): Nemotron 3.5 Transcribe — Nemotron 3.5 Transcribe vs Granite Speech 5.0.
- Need text MT (not speech): LibreTranslate on DeepL alternatives.
- Need local Whisper STT: whisper.cpp.
- Need Hunyuan’s memory writer, not MT: Hy-Memory.
See also Video & Audio.
FAQ
Which is better at translation quality?
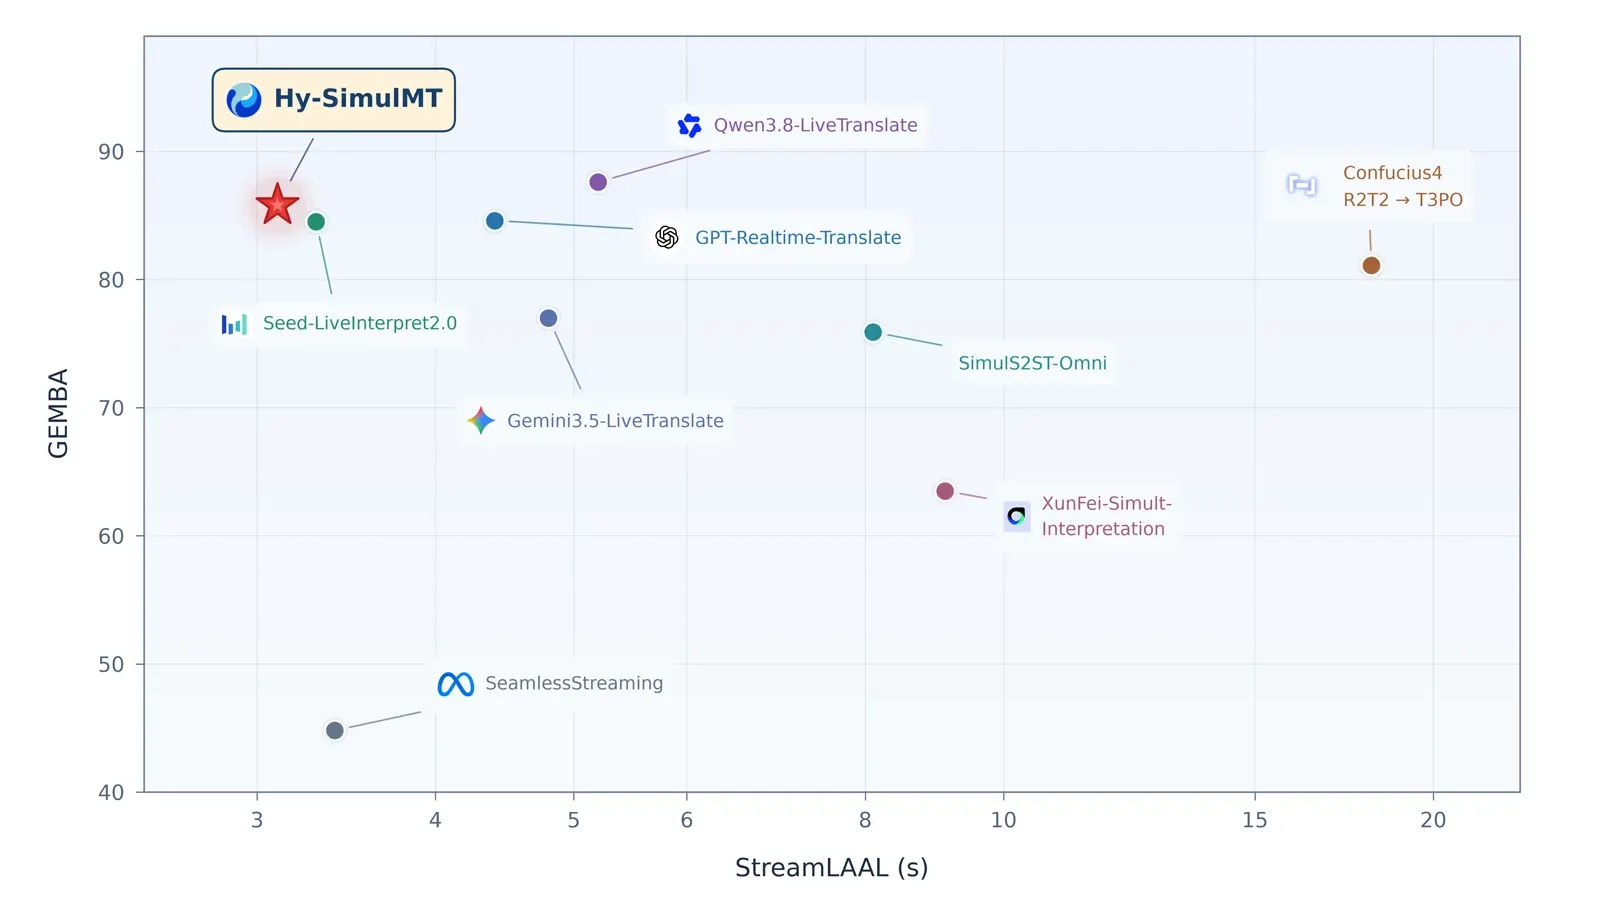
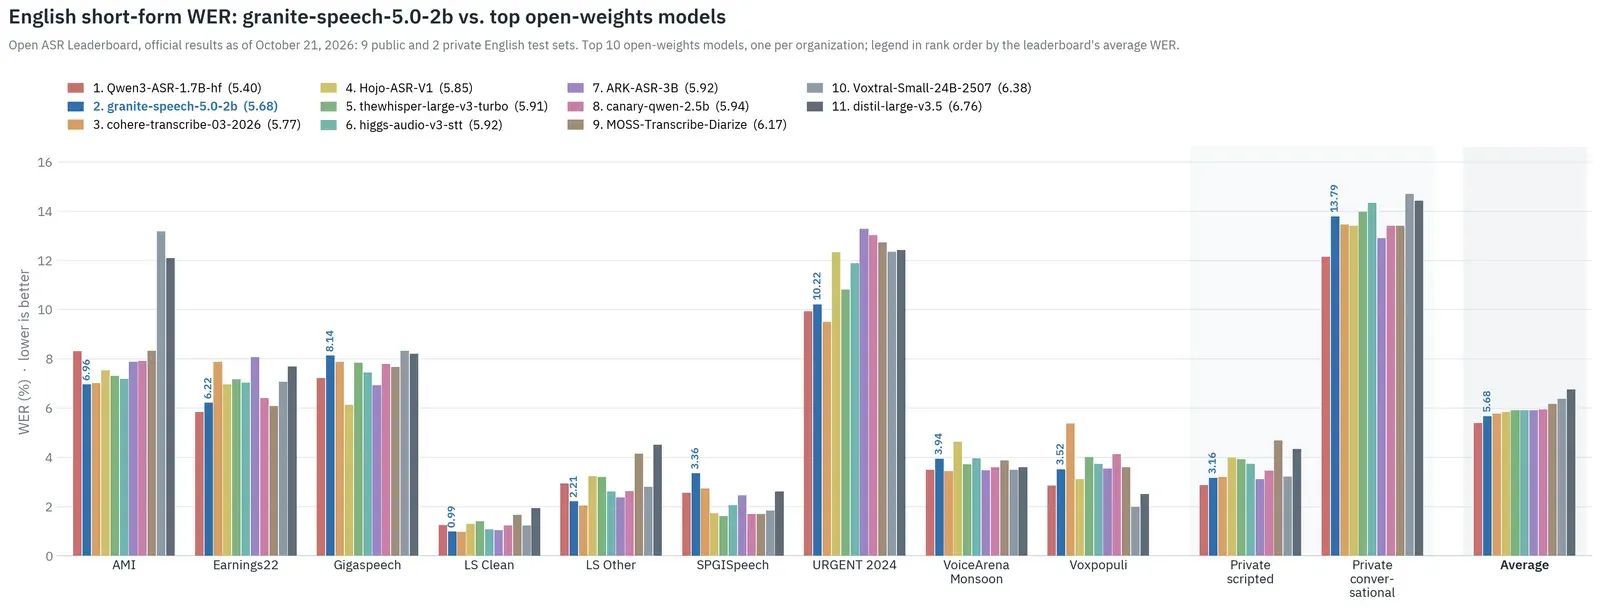
We have no sourced bake-off. Hy-SimulMT’s FLEURS / RealSI / GEMBA rows and Granite’s Cap-F1 / WER rows stay vendor. Do not merge those tables.
Can I use Hy-SimulMT as an Otter clone?
No. Neither page is a meeting-notes product. Hy-SimulMT streams translation. Granite transcribes or translates a clip. See Otter.ai alternatives.
Are they the same Hunyuan stack?
No. Hy-SimulMT is Tencent Hunyuan. Granite Speech 5.0 is IBM. Hy-Memory is a different Hunyuan 30B-A3B writer, not a third speech model.
Why this pairing?
Both are published speech-translation pages on this site. The split is live simultaneous S2ST versus file ASR/AST. Interprefy and KUDO are not site entities, so they are not a vs pair.
Sources & verification
- https://huggingface.co/tencent/Hy-SimulMT-30B-A3B
- https://github.com/Tencent-Hunyuan/Hy-SimulMT
- https://huggingface.co/ibm-granite/granite-speech-5.0-2b
- https://huggingface.co/blog/ibm-granite/granite-speech-5
License notes are not legal advice. Read the original LICENSE. Trademark & disclaimer.