
Open-Source Otter.ai Alternative (2026, Free)
 Identifying Otter.ai · Mark source
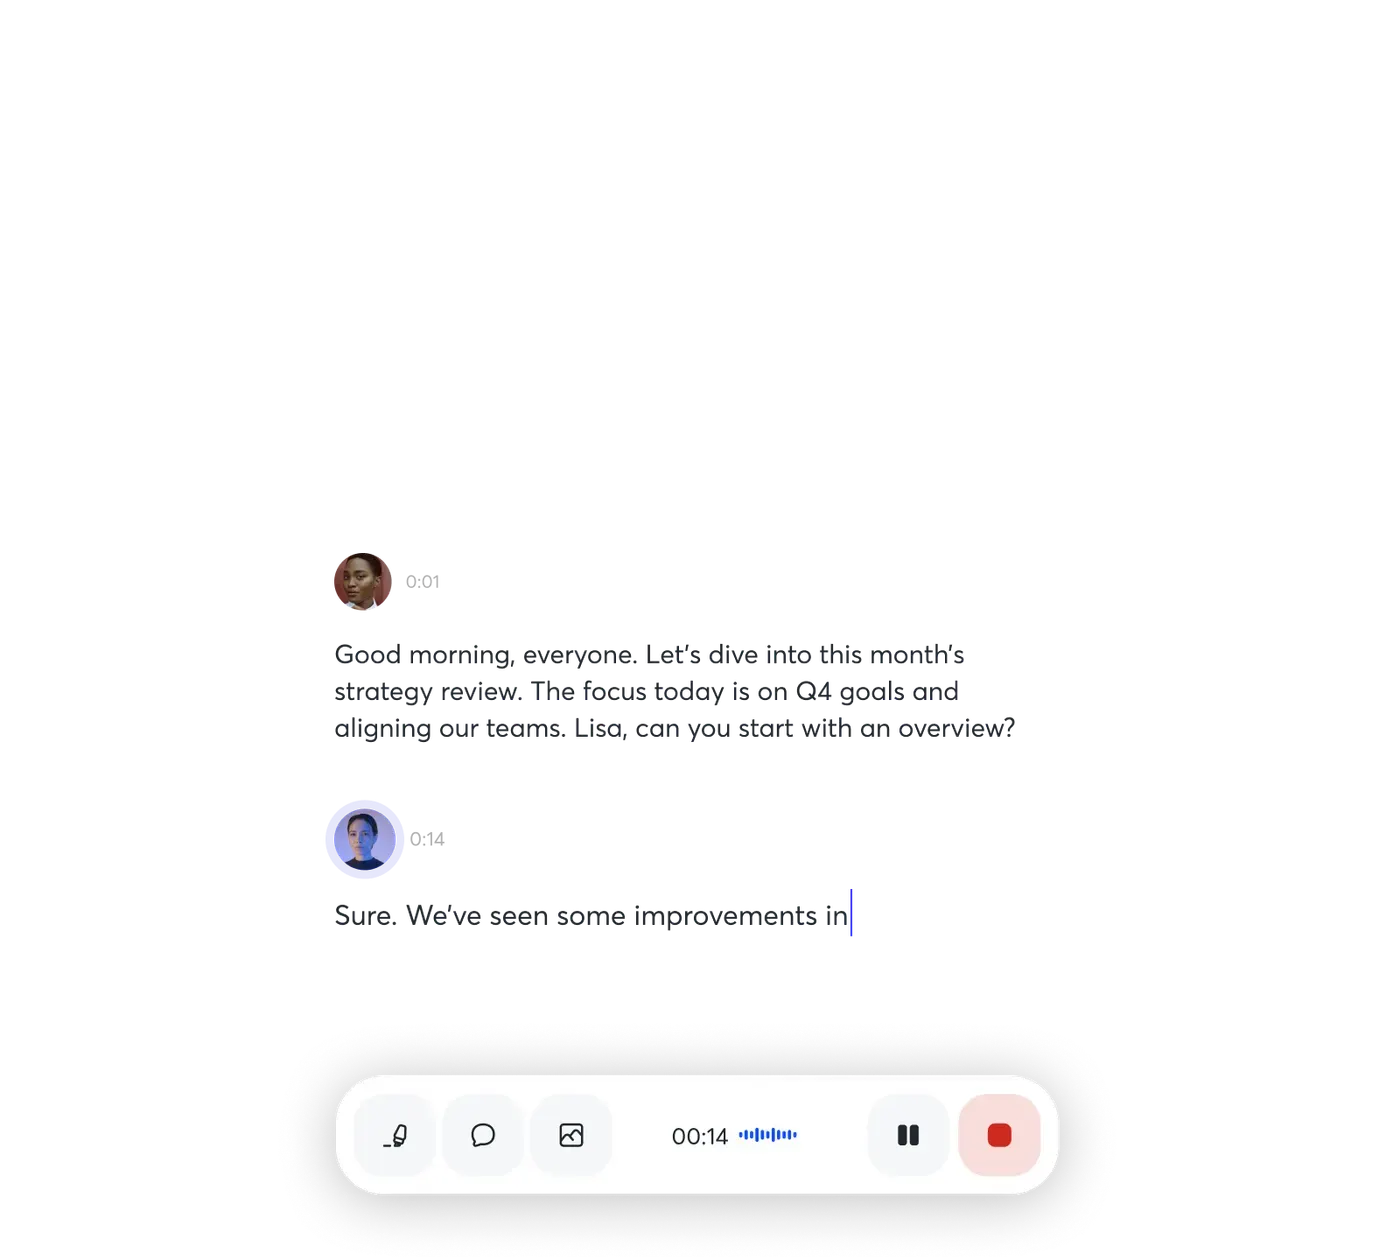
This hub lists open, local speech tools that people compare with commercial meeting-note products. Otter.ai is named only to identify that product class. Sourced options are speaker diarization (pyannote community-1), NVIDIA Nemotron 3.5 Transcribe (offline 30B-A4B ASR/AST), IBM Granite Speech 5.0 (ASR/AST plus a speaker-attribution sibling), Tencent Hunyuan Hy-SimulMT (simultaneous Chinese–English speech MT), and Kyutai Hibiki-Zero (streaming fr/es/pt/de→en). We do not rank transcript quality against Otter.
- pyannote speaker-diarization-community-1 — Open-source local speaker diarization pipeline on Hugging Face (CC-BY-4.0), gated card.
- Nemotron 3.5 Transcribe — NVIDIA offline speech MoE (30B-A4B; 34B / 4.3B active). OpenMDW-1.1. Not Bolt or Super VL.
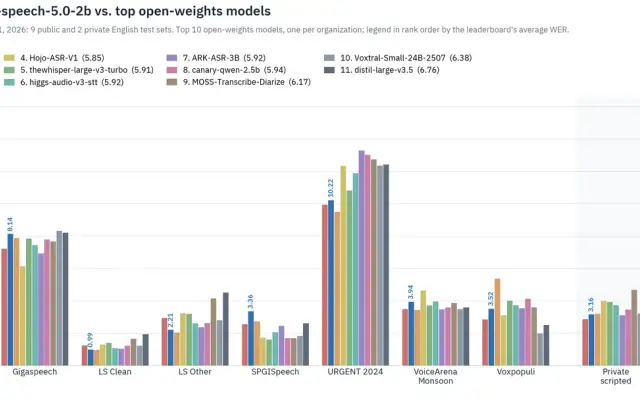
- Granite Speech 5.0 — Apache-2.0 IBM speech family — 5.0-2B ASR/AST plus 4.1-2B Plus speaker attribution.
How we pick
- Official Hugging Face API or GitHub README we could open.
- License string copied from the host (card vs toolkit may differ).
- No unsourced claims that an open pipeline replaces Otter’s meeting product.
Comparison
| Name | License | Developer | Type / modalities |
|---|---|---|---|
| pyannote speaker-diarization-community-1 | CC-BY-4.0 | pyannote | audio, speech |
| Nemotron 3.5 Transcribe | other | NVIDIA Corporation | audio, speech, text |
| Granite Speech 5.0 | Apache-2.0 | IBM | audio, speech, text |
| Hy-SimulMT | Apache-2.0 | Tencent Hunyuan | audio, speech, text |
| Hibiki-Zero | CC-BY-NC-SA-4.0 | Kyutai | audio, speech, text |
Listed models: pyannote speaker-diarization-community-1, Nemotron 3.5 Transcribe (NVIDIA 30B-A4B offline ASR/AST, OpenMDW-1.1; not Bolt/Super VL; compare vs Granite Speech 5.0), Granite Speech 5.0 (5.0-2B ASR/AST; speaker tags live on the 4.1-2B Plus sibling), Hy-SimulMT (Tencent Hunyuan 30B-A3B simultaneous Chinese–English speech MT; compare vs Granite Speech 5.0), and Hibiki-Zero (Kyutai 3B streaming S2ST, fr/es/pt/de→en; compare vs Hy-SimulMT). Related local STT engine: whisper.cpp on Descript alternatives. Related TTS (not meeting notes) is on ElevenLabs alternatives. Related video generation is on Runway alternatives. Chat models are on ChatGPT alternatives. Text MT: DeepL alternatives.
Sourced snapshot (2026-10-13)
| Field | community-1 |
|---|---|
| Hosts | huggingface.co/pyannote/speaker-diarization-community-1 (gated); github.com/pyannote/pyannote-audio |
| HF likes / downloads | 2,840 / 5,444,861 |
| GitHub stars / forks | 10,638 / 1,117 |
| Card license | CC-BY-4.0 |
| Toolkit license | MIT |
| Output | speaker turns (start, stop, speaker_id) |
| Quality vs Otter | Not independently tested; Otter is not in the DER table |
Why a diarization pipeline is on an Otter hub
Otter.ai sells a meeting agent: live notes, summaries, and related workspace features. Searchers still type “open source Otter alternative” when they want speaker-aware local audio. The open artifact we could fully source on 2026-10-13 without a gated README login is community-1: 2,840 likes, about 5.44 million HF downloads, CC-BY-4.0 on the card, created 2025-04-15. The installable toolkit is pyannote.audio (10,638 GitHub stars, MIT).
That is an honest, narrow substitute: who spoke when, on your machine, after you accept the gated card. It is not a drop-in Otter workspace.
What you actually run
ffmpeg, pip install pyannote.audio (or uv), a Hugging Face token, then Pipeline.from_pretrained("pyannote/speaker-diarization-community-1", token=...). The README prints start=… stop=… speaker_… lines. GPU is optional in the sense that .to(cuda) is shown when available. An H100 speed row in that README (31 seconds of compute per hour of AMI IHM audio) is upstream, not our stopwatch.
License split
Do not mix the two SPDX strings. The pipeline card is CC-BY-4.0. The toolkit repository is MIT. If you redistribute weights, start from the card. If you vendor the Python package, start from GitHub. Not legal advice.
What we left out
Whisper, faster-whisper, and other ASR stacks are the usual next hop if you need words rather than speaker ids. They are queued. precision-2 is a paid/hosted pyannoteAI line in the same README; it is mentioned so you do not confuse it with community-1, not as a listed open option.
How to choose
- Need local speaker turns and can accept a gated HF card: community-1.
- Need NVIDIA offline 30B-class ASR/AST (OpenMDW-1.1; not Bolt/Super VL): Nemotron 3.5 Transcribe — Nemotron 3.5 Transcribe vs Granite Speech 5.0.
- Need Apache-2.0 ASR/AST, or speaker tags on the Plus sibling: Granite Speech 5.0.
- Need live Chinese–English simultaneous speech-to-speech (not meeting notes): Hy-SimulMT — Hy-SimulMT vs Granite Speech 5.0.
- Need live French / Spanish / Portuguese / German → English speech-to-speech: Hibiki-Zero — Hibiki-Zero vs Hy-SimulMT. Weights are CC-BY-NC-SA-4.0.
- Need a Whisper-family local engine (no meeting UI): whisper.cpp.
- Need a chat LLM, not meeting audio: DeepSeek-V4.1-Flash or MiniMax M3.1 Flash via ChatGPT alternatives.
- Need video generation, not notes: LTX-2.5.
What “open” does not mean
community-1 is gated. You accept Hugging Face user conditions and pass a token. The toolkit README is public; the card README is not (HTTP 401 without access). CC-BY-4.0 on the card is not the same string as MIT on pyannote.audio. precision-2 is a server-side premium pipeline in the same README — useful so you do not paste the wrong from_pretrained id, not as a listed free local option.
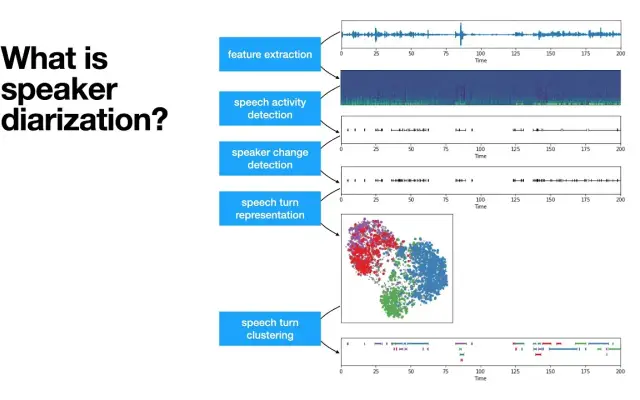
Otter’s marketing screenshot on this hub identifies the commercial search (live transcription UI). pyannote’s official talk thumbnail on the model page identifies the toolkit. Neither image is a quality proof.
If you need words on a timeline, you still need ASR. This hub does not invent a Whisper row. If you need a chat bot that “was in the meeting,” you are in ChatGPT alternatives territory, not diarization. If you need to generate a video of a meeting that never happened, that is Runway alternatives — a different job.
Telemetry in pyannote.audio can be disabled with PYANNOTE_METRICS_ENABLED=0, per the README. That is optional library behavior, not an Otter privacy comparison.
Listed options
pyannote speaker-diarization-community-1
Open-source local speaker diarization pipeline on Hugging Face (CC-BY-4.0), gated card.
Nemotron 3.5 Transcribe
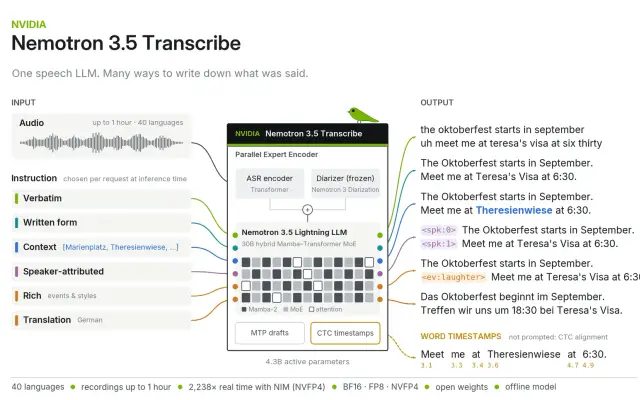
NVIDIA offline speech MoE (30B-A4B; 34B / 4.3B active). OpenMDW-1.1. Not Bolt or Super VL.
Granite Speech 5.0
Apache-2.0 IBM speech family — 5.0-2B ASR/AST plus 4.1-2B Plus speaker attribution.
Hy-SimulMT
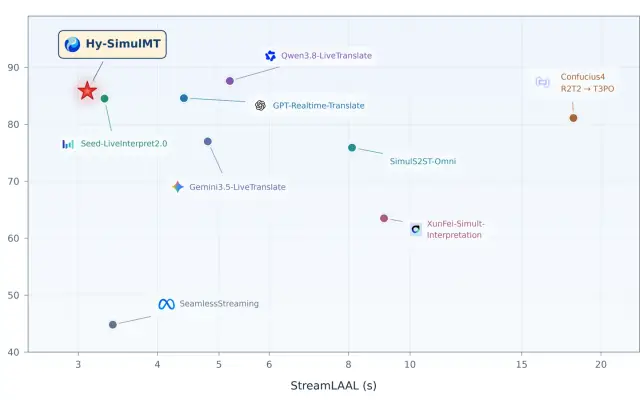
Tencent Hunyuan open-source simultaneous speech MT (30B-A3B). Bidirectional Chinese–English.
Hibiki-Zero
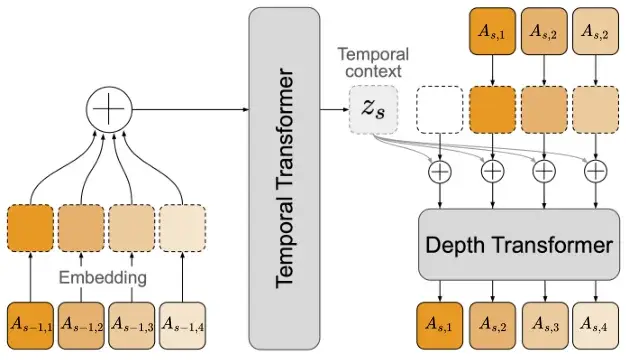
Kyutai 3B streaming speech-to-speech (fr/es/pt/de→en). Weights CC-BY-NC-SA-4.0.
FAQ
Is there a free open-source Otter alternative I can run locally?
pyannote speaker-diarization-community-1 is a gated Hugging Face pipeline (CC-BY-4.0 on the card; 2,840 likes as of 2026-10-13) loaded by the MIT-licensed pyannote.audio toolkit. It labels speaker turns on an audio file after you accept the card and pass a Hugging Face token. It is not an Otter-class live meeting agent with summaries and calendar bots.
Does community-1 transcribe words?
The public GitHub README documents speaker diarization output (start, stop, speaker id). It does not, in the sections we opened, ship an end-to-end Otter-style transcript-plus-summary product. Combine it with a separate ASR stack if you need words; we have not tested that glue.
What is precision-2?
A premium pyannoteAI pipeline in the same README that runs on pyannoteAI servers. It is not the open community-1 checkpoint this hub lists.
Why not Whisper?
whisper.cpp is the local STT engine on Descript alternatives (MIT, 54,489 stars as of 2026-10-19). This Otter hub lists speaker-aware pipelines. Granite Speech 5.0 is the IBM Apache-2.0 ASR/AST family added 2026-10-24; speaker tags are on granite-speech-4.1-2b-plus, not on 5.0-2b.
What is Granite Speech 5.0?
IBM’s October 2026 Apache-2.0 speech family. granite-speech-5.0-2b (48 likes) does multilingual ASR and translation. granite-speech-4.1-2b-plus (101 likes) emits [Speaker N]: tags. Neither is an Otter meeting agent.
What is Hy-SimulMT?
Tencent Hunyuan’s ungated Apache-2.0 30B-A3B simultaneous speech-to-speech checkpoint (18 likes, 45 GitHub stars, 2026-10-27). Card prose is bidirectional Chinese–English live translation plus SimulInfer. It is not an Otter meeting agent and not Hy-Memory.
What is Hibiki-Zero?
Kyutai’s ungated 3B streaming speech-to-speech card (59 likes, 278 GitHub stars, 2026-10-27). Card prose is French, Spanish, Portuguese, and German into English with built-in voice transfer. Weights README says CC BY-NC-SA 4.0; inference code is MIT. It is not an Otter meeting agent. Compare Hibiki-Zero vs Hy-SimulMT.
What is Nemotron 3.5 Transcribe?
NVIDIA’s ungated OpenMDW-1.1 30B-A4B offline speech card (182 likes, 2026-10-29). File ASR/AST with in-checkpoint speaker tags. Not a streaming meeting agent. Not Nemotron 3.5 Bolt or Super VL (those are VLMs). Compare Nemotron 3.5 Transcribe vs Granite Speech 5.0.
Sources & verification
- https://huggingface.co/pyannote/speaker-diarization-community-1
- https://github.com/pyannote/pyannote-audio
- https://www.pyannote.ai
- https://otter.ai/
- https://huggingface.co/ibm-granite/granite-speech-5.0-2b
- https://huggingface.co/ibm-granite/granite-speech-4.1-2b-plus
- https://huggingface.co/blog/ibm-granite/granite-speech-5
- https://huggingface.co/tencent/Hy-SimulMT-30B-A3B
- https://github.com/Tencent-Hunyuan/Hy-SimulMT
- https://huggingface.co/kyutai/hibiki-zero-3b-pytorch-bf16
- https://github.com/kyutai-labs/hibiki-zero
- https://kyutai.org/blog/2026-02-12-hibiki-zero/
- https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Transcribe-30B-A4B
- https://huggingface.co/nvidia/NVIDIA-Nemotron-3.5-Transcribe-30B-A4B/blob/main/LICENSE
License notes are not legal advice. Read the original LICENSE. Trademark & disclaimer.