
Open-Source ElevenLabs Alternative (2026, Free)
 Identifying ElevenLabs · Mark source
This hub lists open-weight text-to-speech models that people compare with ElevenLabs-class hosted voice products. ElevenLabs is named only to identify that product class. Lead rows now include Gradium Phonon (on-device 31M Apache-2.0) and Fish Audio Drama 3. We do not rank voice quality against ElevenLabs.
- Phonon — On-device TTS from Gradium. Default 31M English weights are Apache-2.0; 40M variants are CC BY-NC.
- GPT-SoVITS — MIT few-shot voice-cloning TTS. One minute of data is the project’s own claim.
- Fish Audio Drama 3 — Open-weight 35B MoE text-to-speech model (~3B active) with a directed-performance decoder.
How we pick
- Official Hugging Face card we could open (API or README).
- License copied from the LICENSE file on that host, even when cardData is stale.
- No unsourced “beats ElevenLabs” claims; vendor or third-party tables stay labeled as such.
Comparison
| Name | License | Developer | Type / modalities |
|---|---|---|---|
| Phonon | MIT OR Apache-2.0 | See page | See page |
| GPT-SoVITS | MIT | See page | See page |
| Fish Audio Drama 3 | other | Fish Audio (39 AI, INC.) | audio, speech, text |
| LFM3-Omni-2B | other | Liquid AI | text, image, video, audio, speech |
Listed options: Phonon (Gradium on-device TTS; phonon-31m-en is Apache-2.0, 40m variants are CC BY-NC), Fish Audio Drama 3, GPT-SoVITS (MIT, 63,196 stars, 2026-10-19), and LFM3-Omni-2B (Liquid AI 2.17B omni with speech out — not a dedicated TTS studio; added 2026-10-31). Related local speech (speaker turns, not TTS) is on Otter.ai alternatives. Transcription (the other direction) is on Descript alternatives (whisper.cpp). Song generation is on Suno alternatives (ACE-Step 1.5). Chat models are on ChatGPT alternatives. Video generation is on Runway alternatives. Avatars: HeyGen alternatives. Still images beside a voiceover: PhotoCraft vs GIMP.
Sourced snapshot (2026-10-14)
| Field | Drama 3 |
|---|---|
| Hosts | huggingface.co/fishaudio/drama-3 (ungated); github.com/fishaudio/fish-speech |
| HF likes / downloads | 112 / 23 |
| GitHub stars / forks | 33,061 / 2,871 |
| Release | v3.0.0-beta prerelease, 2026-10-13T16:05:05Z |
| License file | Fish Audio Community License Agreement v1.0 (13 Oct 2026) |
| Params | 35B MoE, ~3B active |
| Official GPU | NVIDIA, ≥48 GB FP8 |
| Quality vs ElevenLabs | Not independently tested |
Why a TTS checkpoint is on an ElevenLabs hub
ElevenLabs sells hosted voice generation. Searchers still type “open source ElevenLabs alternative” when they want downloadable TTS weights. The open artifact we could fully source on 2026-10-14 is Drama 3: 112 likes, ungated, 35B MoE with a public Community License file.
That is an honest, narrow substitute: local (or self-hosted) speech from text, after you install fish-speech and download the card. It is not a drop-in ElevenLabs studio.
License in one paragraph
Read the LICENSE. Paraphrase only: research and non-commercial use are licensed; commercial use is licensed only under the USD 500,000 Annual Revenue threshold; Hosted Service (TTS/voice API to third parties) needs a separate agreement at any revenue; no cloning a real person’s voice without consent. Hugging Face cardData still says fish-audio-research-license — that label does not match the LICENSE file. Not legal advice.
How to choose
- Need Liquid’s 2.17B omni that can also speak (LFM Open License v1.0; not a voice studio): LFM3-Omni-2B.
- Need on-device English TTS with Apache-2.0 31M weights: Phonon. Do not treat the 40m line as commercial-free (CC BY-NC).
- Need open-weight TTS and can meet the NVIDIA / 48 GB note: Drama 3.
- Need MIT few-shot cloning code: GPT-SoVITS.
- Need speaker diarization (who spoke when), not TTS: pyannote community-1.
- Need local transcription (STT): whisper.cpp on Descript alternatives.
- Need a chat LLM: DeepSeek-V4.1-Flash via ChatGPT alternatives.
What “open” does not mean
Drama 3 is open-weight. The blog itself says it is “open-weight rather than open source.” The GitHub release is a prerelease. Official docs exclude CPU/MPS/ROCm for this checkpoint. Vendor-cited Artificial Analysis scores are not an ElevenLabs ranking.
Phonon’s 31m English checkpoint is Apache-2.0. The 40m line is CC BY-NC 4.0. Do not flatten that split into “Phonon is fully open / commercial-free.”
ElevenLabs’ marketing OG on this hub identifies the commercial search. Drama 3’s blog OG on the model page identifies the checkpoint. Neither image is a quality proof.
Listed options
Phonon
On-device TTS from Gradium. Default 31M English weights are Apache-2.0; 40M variants are CC BY-NC.
GPT-SoVITS
MIT few-shot voice-cloning TTS. One minute of data is the project’s own claim.
Fish Audio Drama 3
Open-weight 35B MoE text-to-speech model (~3B active) with a directed-performance decoder.
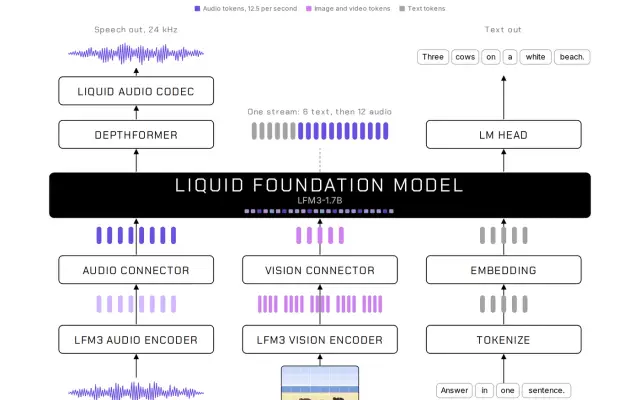
LFM3-Omni-2B
Liquid AI 2.17B omni — text/image/video/audio in, text+speech out. Not LFM3-1.7B or LFM2.5.
FAQ
Is there a free open-source ElevenLabs alternative I can run locally?
Fish Audio Drama 3 publishes ungated weights on Hugging Face (112 likes as of 2026-10-14): a 35B MoE TTS with about 3B active parameters. Official install.md requires an NVIDIA GPU and at least 48 GB VRAM for FP8. “Locally” here means the weights are downloadable; we have not measured VRAM on a forkalt machine. Hosted Fish Audio TTS is a different product.
Does Drama 3 match ElevenLabs quality?
We have no sourced bake-off against ElevenLabs. The Fish Audio blog cites Artificial Analysis Pronunciation Robustness at 93.2% overall for Drama 3 Preview; that is vendor-cited, not an ElevenLabs verdict.
What is the license?
The LICENSE file on fishaudio/drama-3 is Fish Audio Community License Agreement Version 1.0 (13 October 2026). Commercial use is limited by a USD 500,000 annual-revenue threshold; Hosted Services need a separate license. Not legal advice.
Why isn’t Whisper or another TTS on this list?
Whisper-family models are ASR (speech-to-text), not TTS. See Descript alternatives (whisper.cpp). Phonon (on-device, default 31M Apache-2.0) and GPT-SoVITS (MIT, 63,196 stars, pushed 2026-10-19) are TTS tool rows. Coqui TTS (MPL-2.0, 46,139 stars) last push was 2024-08-16 — named, not a lead row. Kokoro (hexgrad/kokoro, Apache-2.0, 9,490 stars, last push 2025-08-06) and Chatterbox (resemble-ai/chatterbox, MIT, 27,083 stars, last push 2026-07-21) are named only.
GPT-SoVITS vs Drama 3?
GPT-SoVITS is MIT training/inference for few-shot cloning. Drama 3 is Fish Audio’s open-weight 35B MoE checkpoint under a Community License. Different artifacts. No voice-quality rank.
Sources & verification
- https://huggingface.co/fishaudio/drama-3
- https://github.com/fishaudio/fish-speech
- https://fish.audio/blog/fish-audio-drama-3/
- https://huggingface.co/fishaudio/drama-3/resolve/main/LICENSE
- https://elevenlabs.io/
- https://github.com/RVC-Boss/GPT-SoVITS
- https://huggingface.co/gradium/phonon-31m-en
- https://github.com/gradium-ai/xn-ptts
- https://gradium.ai/phonon
- https://huggingface.co/LiquidAI/LFM3-Omni-2B
License notes are not legal advice. Read the original LICENSE. Trademark & disclaimer.