
Apache-2.0llmRuns locally33B (card)
Nanbeige4.3-33B: Specs, License & How to Run
Apache-2.0 33B text agent teacher from Nanbeige (BOSS Zhipin) with 512K context.
- License
- Apache-2.0
- Parameters
- 33B (card)
- HF likes
- 365 (2026-10-26)
- First seen
- 2026-10-24
TL;DR. Nanbeige4.3-33B is a llm model from Nanbeige (BOSS Zhipin). Parameters: 33B (card).License: Apache-2.0. It is listed under ChatGPT, Closed LLM APIs, Claude Code, Cursor.
| Developer | Nanbeige (BOSS Zhipin) |
|---|---|
| Type | llm |
| Architecture | Dense decoder-only Transformer (HF model_type llama; architecture LlamaForCausalLM). config.json: 52 layers, hidden 7168, 56 attention heads, 8 key/value heads, intermediate 22016, vocab 166912, max_position_embeddings 524288. Post-trained from Nanbeige/Nanbeige4.3-33B-Base. Text only. |
| Parameters | 33B (card) |
| Modalities | text |
| Languages | en, zh |
| Context | 524,288 tokens (512K; card + config.json) |
| License | Apache-2.0 — Hugging Face cardData.license and the README YAML both say apache-2.0 (opened 2026-10-26). There is no LICENSE file in the weight repo (raw /resolve/main/LICENSE, LICENSE.md, and LICENSE.txt all 404). The Base sibling also tags apache-2.0 and also has no LICENSE blob. Not legal advice. |
| Hardware | Not yet verified — HF usedStorage is 66,259,989,086 bytes (~61.7 GiB). safetensors.parameters sum to 33,118,977,024. Official SGLang/vLLM recipes use tensor parallel 4. Peak VRAM is not independently measured. No GGUF or INT4 sibling on this check. (not independently tested) |
| Hugging Face likes | 365 (as of 2026-10-26) |
| Model card | https://huggingface.co/Nanbeige/Nanbeige4.3-33B |
| First seen | 2026-10-24 |
Nanbeige4.3-33B is a dense 33B text model from Nanbeige LLM Lab, the Hugging Face org for BOSS Zhipin’s model team (huggingface.co/Nanbeige, opened 2026-10-26). Official hosts the same day: the ungated card Nanbeige/Nanbeige4.3-33B (created 2026-10-24T02:49:18Z; last modified 2026-10-25T11:11:17Z; 365 likes / 0 downloads) and the Base sibling Nanbeige/Nanbeige4.3-33B-Base (created 2026-10-24T02:46:52Z; 46 likes). Both tag apache-2.0. A raw LICENSE path 404’d on both.
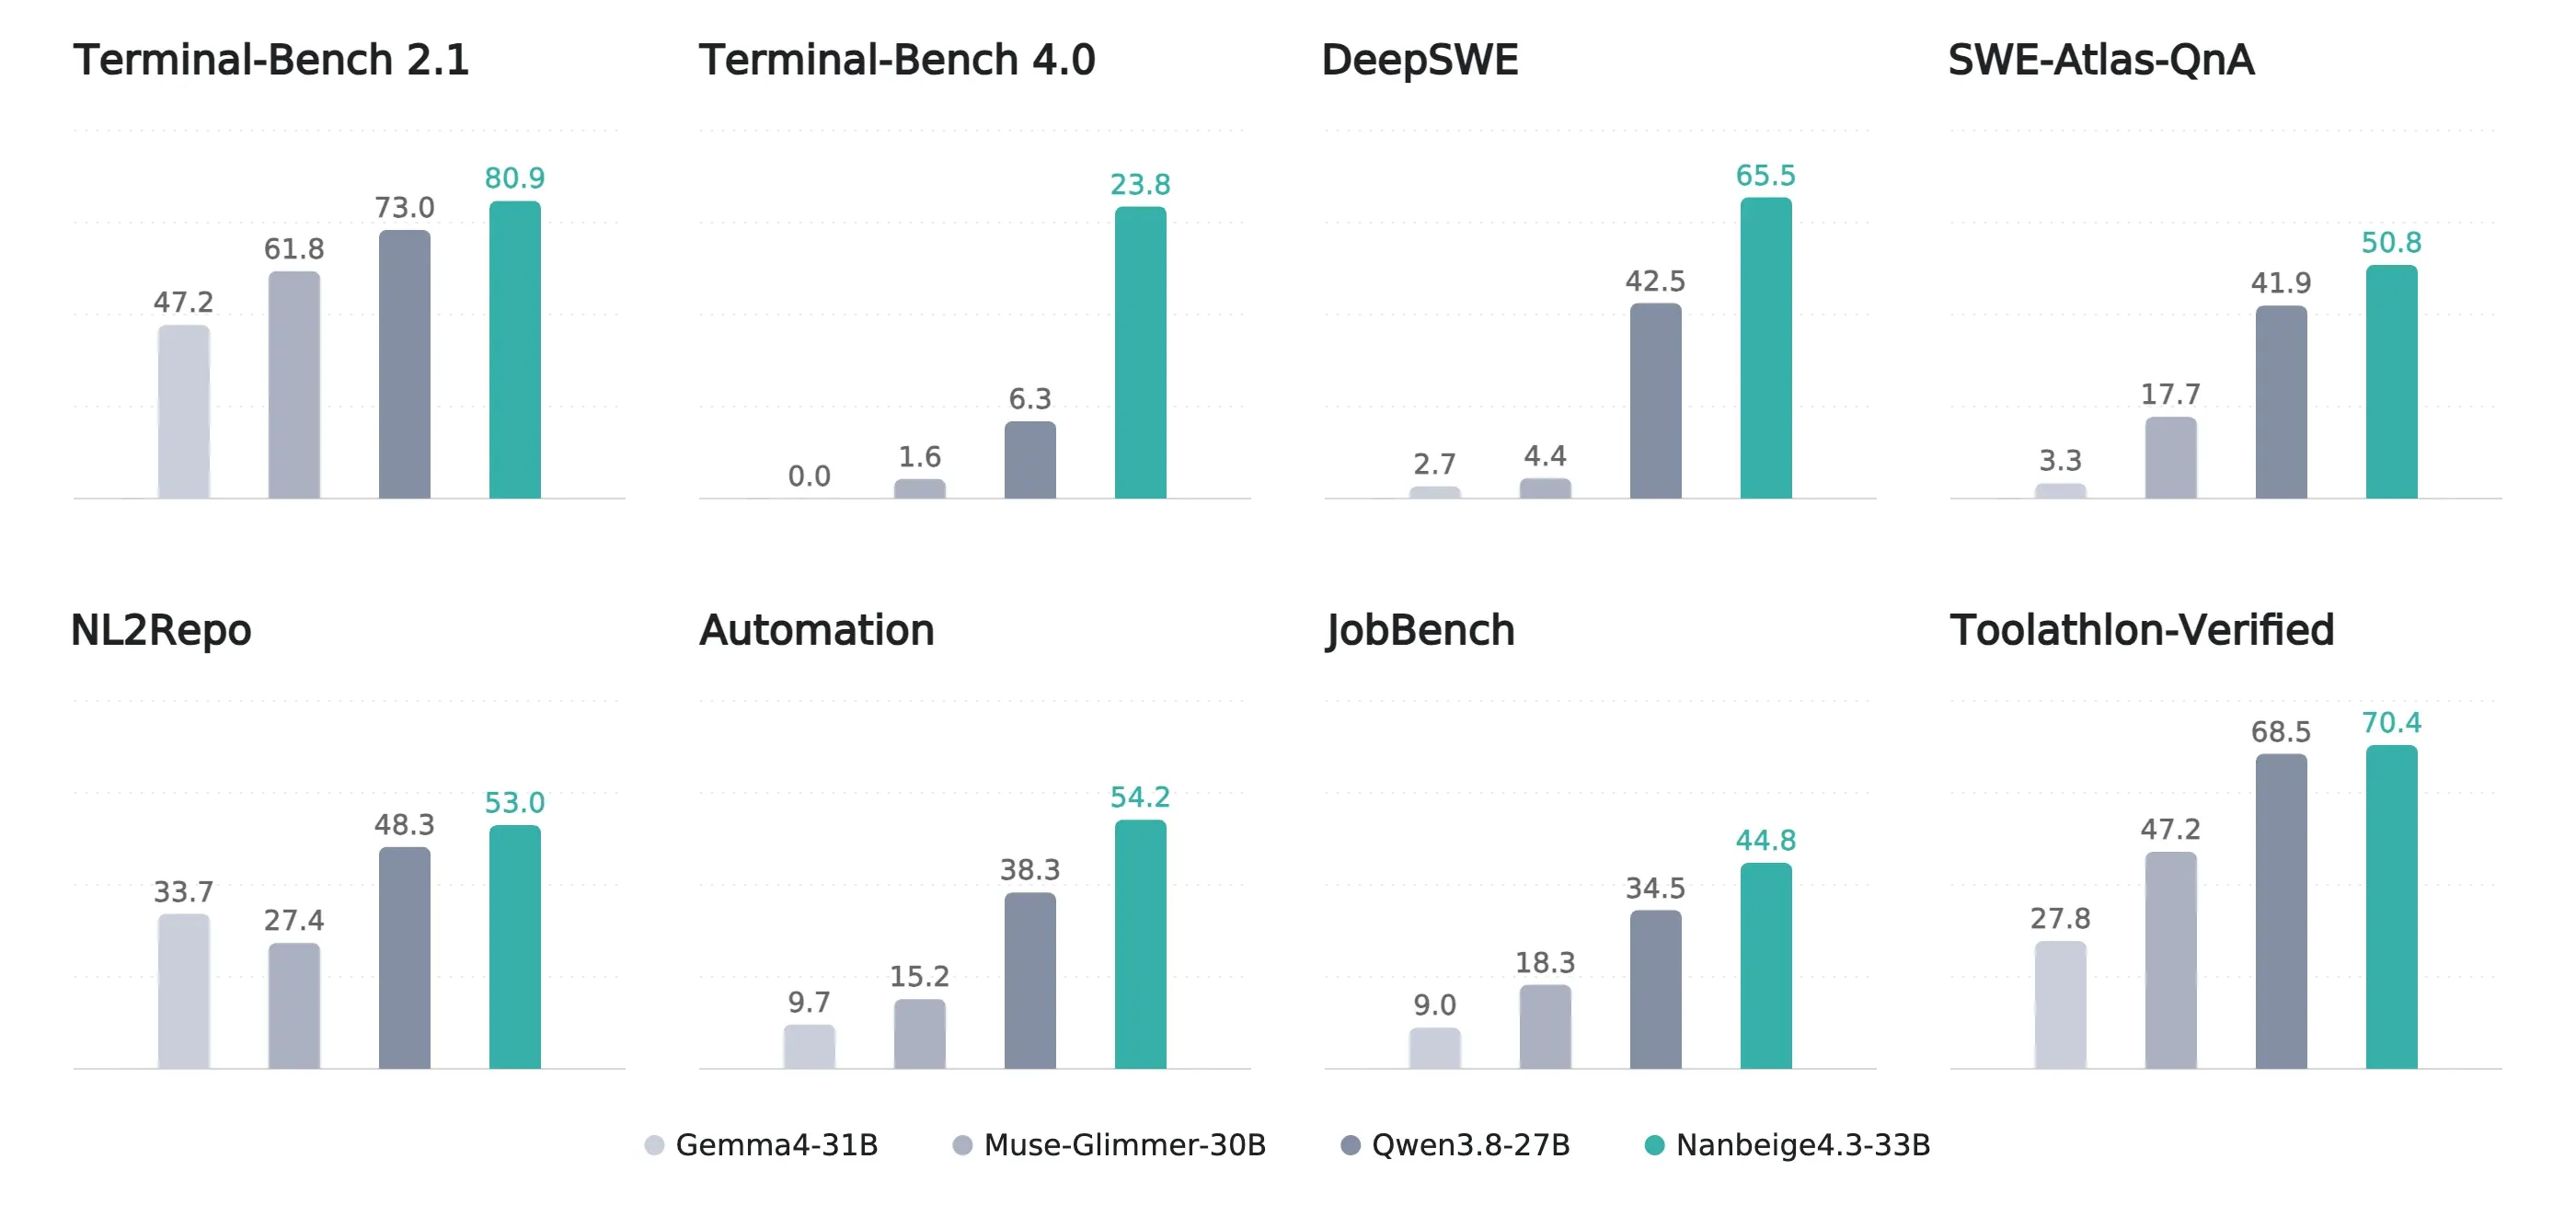
This page hangs off ChatGPT alternatives, closed LLM APIs, Claude Code alternatives, and Cursor alternatives. That mapping is editorial. We have no sourced quality comparison against ChatGPT, Claude Code, or Cursor. Head-to-head facts versus the same-site ~30B card the Nanbeige table names: Nanbeige4.3-33B vs Qwen3.8-27B. Muse-Glimmer-30B and Gemma4-31B are also columns on that table and are not pages here.
The card calls Nanbeige4.3-33B the flagship teacher for the Nanbeige4.3 series: a high-capacity agent to later distill into smaller models (it names Nanbeige4.3-3B as upcoming). It positions “complex coding and professional cowork.” Those sentences stay vendor. Hugging Face pipeline_tag is text-generation; model_type is llama. Languages on the card: en, zh.
What we verified (2026-10-26)
| Field | Value | Source |
|---|---|---|
| Host | huggingface.co/Nanbeige/Nanbeige4.3-33B (not gated) | HF API |
| Created / last modified | 2026-10-24T02:49:18Z / 2026-10-25T11:11:17Z | same |
| Likes / downloads | 365 / 0 | same |
| License tag + file | apache-2.0 / LICENSE blob 404 | HF cardData + raw fetch |
| Pipeline tag | text-generation | HF API |
| Architecture | llama / LlamaForCausalLM | config.json |
| Params (card) | 33B | card |
| safetensors.parameters | 33,118,977,024 | HF API |
| usedStorage (BF16) | 66,259,989,086 bytes (~61.7 GiB) | same |
| Layers / hidden / heads | 52 / 7168 / 56 Q, 8 KV | config.json |
| Documented context | 524,288 tokens | card + max_position_embeddings |
| Base sibling | Nanbeige4.3-33B-Base · 46 likes · same param count | HF API |
| Org | Nanbeige LLM Lab at BOSS Zhipin | huggingface.co/Nanbeige |
How to run (from the card, not tested)
The tokenizer chat template exposes enable_thinking (default on), preserve_thinking (the card recommends false for general chat and true for multi-turn tool use, office tasks, and code-agent workflows), and a tools path. The card recommends tool_call_format="xml"; json is also listed. Official benches used preserve_thinking=true.
Recommended sampling (copied):
| Scenario | Temperature | Top_p | Max new tokens |
|---|---|---|---|
| Agentic and tool-use | 1.0 | 0.95 | 65,536 |
| Reasoning and chat | 0.6 | 0.95 | 262,144 |
SGLang (card; --tp-size 4):
python -m sglang.launch_server \
  --model-path /path/to/Nanbeige4.3-33B \
  --host 0.0.0.0 \
  --port 8000 \
  --tp-size 4 \
  --mem-fraction-static 0.8 \
  --reasoning-parser qwen3 \
  --tool-call-parser qwen3_coder
vLLM (card; --tensor-parallel-size 4):
vllm serve /path/to/Nanbeige4.3-33B \
  --host 0.0.0.0 \
  --port 8000 \
  --tensor-parallel-size 4 \
  --gpu-memory-utilization 0.8 \
  --enable-auto-tool-choice \
  --reasoning-parser qwen3 \
  --tool-call-parser qwen3_coder
Transformers is also documented (trust_remote_code=True, use_fast=False on the tokenizer). Engine page: vLLM.
License
Card tag apache-2.0 on the 33B and Base cards (2026-10-26). No LICENSE blob in either repo on this check. Not legal advice.
What we did not invent
- “State-of-the-art among ~30B open models” stays vendor.
- Card bench rows stay self-reported. On that table, Qwen3.8-27B leads SWE-Bench Pro and GDPval; Nanbeige leads most other listed rows, including Terminal-Bench 2.1 (80.9 vs 73.0) and DeepSWE (65.5 vs 42.5). We do not merge those into a rank.
- Peak VRAM, tokens/s, and laptop-class GGUF paths are not on this card.
- We do not rank Nanbeige against Cursor, Claude Code, ChatGPT, Flint, or Raon-1-mini.
Related ~30B open weights: Qwen3.8-27B — Nanbeige4.3-33B vs Qwen3.8-27B — Flint (39.8B/2.5B coding MoE), Raon-1-mini (28.8B/4.3B preview), Sage-A1.5 (35B science/agent VLM). Serving: vLLM. Agents: Cline, OpenCursor.
Benchmarks
Quoted from the cited source. forkalt has not independently reproduced these numbers.
| Name | Score | Source |
|---|---|---|
| Terminal-Bench 2.1 (card, Terminus 2) | 80.9 (self-reported) | https://huggingface.co/Nanbeige/Nanbeige4.3-33B |
| DeepSWE (card, mini-swe-agent v2.4.6) | 65.5 (self-reported) | https://huggingface.co/Nanbeige/Nanbeige4.3-33B |
| SWE-Bench Pro (card, mini-swe-agent v2.4.6) | 60.3 (self-reported) | https://huggingface.co/Nanbeige/Nanbeige4.3-33B |
| Automation Bench v1.0.6 (card) | 54.2 (self-reported) | https://huggingface.co/Nanbeige/Nanbeige4.3-33B |
| GPQA Diamond (card) | 89.5 (self-reported) | https://huggingface.co/Nanbeige/Nanbeige4.3-33B |
Deploy options
Comparisons
FAQ
Is Nanbeige4.3-33B open weight and Apache-2.0?
The ungated card Nanbeige/Nanbeige4.3-33B (created 2026-10-24T02:49:18Z; 365 likes / 0 downloads in the 2026-10-26 API check) tags license apache-2.0. The same tag is on Nanbeige4.3-33B-Base (46 likes). A raw LICENSE file 404’d on both cards. Not legal advice.
Who makes it?
The Hugging Face org Nanbeige describes itself as Nanbeige LLM Lab, a research team at BOSS Zhipin (zhipin.com). The card author is Nanbeige. This page does not list individual contributors.
Does it replace Cursor, Claude Code, or ChatGPT?
No sourced bake-off on this site. The card positions a ~30B teacher for agentic coding and professional cowork, and names a later 3B distillation. That is product-class mapping, not a quality rank. See Nanbeige4.3-33B vs Qwen3.8-27B.
How does it compare to Qwen3.8-27B?
The Nanbeige card prints a self-reported table versus Qwen3.8-27B, Muse-Glimmer-30B, and Gemma4-31B at highest thinking effort. Nanbeige leads most listed rows; Qwen3.8-27B leads SWE-Bench Pro (61.7 vs 60.3) and GDPval (86.4 vs 84.8) on that same table. Those numbers stay vendor. Identification facts: 33B text / 512K versus 27B VLM / 262K native. See the vs page.
Can I run it on one GPU?
The card does not publish a single-GPU VRAM figure. Official serve recipes use tensor parallel 4. BF16 usedStorage is ~61.7 GiB. forkalt has not loaded the checkpoint.
Sources & verification
- https://huggingface.co/Nanbeige/Nanbeige4.3-33B
- https://huggingface.co/Nanbeige/Nanbeige4.3-33B-Base
- https://huggingface.co/Nanbeige
- https://huggingface.co/Qwen/Qwen3.8-27B
License notes are not legal advice. Read the original LICENSE. Trademark & disclaimer.