
othermultimodalRuns locally~1T (card)
Mistral Large 4: Specs, License & How to Run
Mistral ~1T/52B ungated multimodal MoE (text+image→text), 1M context. Le Chonk.
- License
- other
- Parameters
- ~1T (card) (active 49B per token; 52B including embeddings and output layers (card))
- HF likes
- 1,301 (2026-10-30)
- First seen
- 2026-09-30
TL;DR. Mistral Large 4 is a multimodal model from Mistral AI. Parameters: ~1T (card) (active 49B per token; 52B including embeddings and output layers (card)).License: other. It is listed under ChatGPT, Closed LLM APIs, Claude Code.
| Developer | Mistral AI |
|---|---|
| Type | multimodal |
| Architecture | Granular Mixture-of-Experts. Card: 128 routed experts (4 active per token) plus 1 shared expert; Pixtral-style vision encoder; native text + image in, text out. HF model_type mistral_large4; architecture MistralLarge4ForConditionalGeneration; pipeline_tag image-text-to-text. Main card quantization_config.quant_method is fp8. Checkpoint ships an embedded DSpark speculative-decoding draft head (3 dense MLA draft layers; block of 3 tokens). |
| Parameters | ~1T (card) · active 49B per token; 52B including embeddings and output layers (card) |
| Modalities | text, image |
| Languages | en, fr, de, es, pt, it, ja, ko, ru, zh, ar, fa, id, ms, ne, pl, ro, sr, sv, tr, uk, vi, hi, bn, bg, hr, cs, da, nl, et, fi, el, hu, ga, lv, lt, mt, sk, sl |
| Context | 1,048,576 tokens (card / native 1M window) |
| License | other — LICENSE file is titled Mistral Ecosystem Open-Weight License, a modified MIT grant (attribution 2026 - Mistral). Section 2: if the Licensee or affiliates operate a Model as a Service business, they must enter a separate commercial license with Mistral before using the Model or derivatives for any commercial purpose. Section 3: that MaaS requirement does not apply to (a) internal use that does not make the Model available to third parties, or (b) use through Mistral’s official products. “Model as a Service” is defined as giving a third party access for inference or post-training (for instance via API or hosted endpoints) with meaningful control over inputs, parameters, or training data; it does not include end-user products with model capabilities solely embedded in specific features or harnesses, or mere relaying of requests to models hosted by others. Same LICENSE file on the NVFP4 sibling. Not legal advice. |
| Hardware | Not yet verified — Datacenter-class. The official vLLM Docker example uses --tensor-parallel-size 8. Hugging Face usedStorage on the FP8 card is 1,060,608,252,777 bytes (~988 GiB / ~1.06 TB on disk). The NVFP4 sibling usedStorage is 610,096,072,460 bytes (~568 GiB). Peak VRAM is not independently measured. The card says the NVFP4 checkpoint targets Blackwell GPUs (vLLM and SGLang). (not independently tested) |
| Hugging Face likes | 1,301 (as of 2026-10-30) |
| Model card | https://huggingface.co/mistralai/Mistral-Large-4-1T-A52B |
| First seen | 2026-09-30 |
Mistral Large 4 (also Le Chonk) is Mistral AI’s ungated natively multimodal Mixture-of-Experts checkpoint. Official hosts we opened on 2026-10-30: the ungated FP8 card mistralai/Mistral-Large-4-1T-A52B (created 2026-09-30T18:35:13Z; last modified 2026-10-29T14:51:07Z; 1,301 likes / 1,239 downloads), the ungated NVFP4 sibling mistralai/Mistral-Large-4-1T-A52B-NVFP4 (created 2026-10-15T19:09:41Z; 50 likes / 315 downloads), the Mistral Ecosystem Open-Weight LICENSE, the OSS post Mistral Large 4 (Le Chonk) is now open weight, and Hugging Face’s Welcome Le Chonk (published 29 October 2026). API gated was false on both cards. Hugging Face pipeline_tag is image-text-to-text.
This page hangs off ChatGPT alternatives, closed LLM APIs, and Claude Code alternatives. Those mappings are editorial (chat / API / coding-agent search). We have no sourced quality comparison against ChatGPT, Claude Code, or Muse Spark Open. Head-to-head facts: Mistral Large 4 vs Muse Spark Open.
The card calls it “our largest and most capable model to date” and a 1-trillion-parameter natively multimodal MoE with 49 billion active parameters per token (52 billion including embeddings and output layers), trained from scratch on 3,800 NVIDIA Grace Blackwell GPUs in Mistral datacenters in Europe. Those adjectives and the GPU count stay vendor. The Hugging Face blog states two official variants: FP8 and NVFP4.
Do not flatten this card into a consumer GPU story. runsLocally: true means the weights are downloadable without a gate.
What we verified (2026-10-30)
| Field | Value | Source |
|---|---|---|
| Host (FP8) | huggingface.co/mistralai/Mistral-Large-4-1T-A52B (not gated) | HF API |
| Created / last modified | 2026-09-30T18:35:13Z / 2026-10-29T14:51:07Z | same |
| Likes / downloads | 1,301 / 1,239 | same |
| License tag | other | HF cardData |
| LICENSE file | Mistral Ecosystem Open-Weight License (modified MIT) | LICENSE |
| Pipeline tag | image-text-to-text | HF API |
| Architecture | mistral_large4 / MistralLarge4ForConditionalGeneration | config |
| Params (card) | ~1T total; 49B active/token; 52B including embeddings | card |
| Quantization (lead card) | FP8 (quant_method: fp8) |
config |
| usedStorage (FP8) | 1,060,608,252,777 bytes (~988 GiB / ~1.06 TB) | HF API |
| NVFP4 sibling | ungated; 50 likes / 315 downloads; usedStorage 610,096,072,460 | HF API |
| Context | 1M tokens (card) | card |
| DSpark | embedded draft head; num_speculative_tokens 3 |
card |
Languages on cardData |
38 ISO codes (EN, FR, DE, ES, …; includes EU official set on the card) | HF cardData |
| Card “160+ languages” | vendor sentence | card |
We keep Mistral’s ~1T / 49B / 52B quotes. We do not invent a 1.05T parameter reconciliation. Disk size (~1.06 TB FP8 usedStorage) is not a parameter count.
How to run (from the official card, not tested)
Copied names only. forkalt has not loaded a checkpoint.
Recommended sampling on the card: temperature=1.0, top_p=0.95. Reasoning effort low / medium / high (default high).
vLLM Docker recipe from the card (vllm/vllm-openai:mistral-large-4):
docker run --runtime nvidia --gpus all \
  -v ~/.cache/huggingface:/root/.cache/huggingface \
  -p 8000:8000 \
  --ipc=host \
  vllm/vllm-openai:mistral-large-4 \
  --model mistralai/Mistral-Large-4-1T-A52B \
  --tensor-parallel-size 8 \
  --tool-call-parser mistral \
  --reasoning-parser mistral \
  --enable-auto-tool-choice \
  --gpu-memory-utilization 0.85
To enable the embedded DSpark head, the card adds:
--speculative-config '{"method": "dspark", "num_speculative_tokens": 3}'The card’s vendor line for DSpark is “up to 1.9x higher throughput.” That stays vendor. Actual gains depend on hardware and workload.
SGLang Docker image named on the card: lmsysorg/sglang:mistral-large-4, with --speculative-algorithm DSPARK and example --tp-size 8. Transformers path on the card uses AutoModelForMultimodalLM from main and torchrun --nproc-per-node 8. The Hugging Face blog also names llama.cpp GGUFs from Unsloth and the llama.cpp team; we did not open those sibling cards in this check.
The card also names Mistral Vibe (mistral-vibe) as a CLI coding assistant that can point at the Mistral API (mistral-large-4) or a local vLLM server. That is a harness label, not a forkalt test, and not a Claude Code clone.
Hosted Mistral API mistral-large-4 is a different artifact from the weight grant.
License
LICENSE is titled Mistral Ecosystem Open-Weight License. Opening sentence: this license is a modified version of the MIT license. Attribution notice: 2026 - Mistral. Hugging Face cardData.license is the opaque label other. Same file is listed on the NVFP4 sibling.
Paraphrase only, not legal advice:
- Include the copyright notice and this permission notice with copies or substantial portions.
- If you or affiliates operate a Model as a Service business, you must enter a separate commercial license with Mistral before using the Model or derivatives for any commercial purpose (contact form on mistral.ai).
- That MaaS requirement does not apply to internal use that does not make the Model available to third parties, or to use through Mistral’s official products.
- “Model as a Service” means giving a third party access for inference or post-training (for instance via API or hosted endpoints) with meaningful control over inputs, parameters, or training data. It does not include end-user products with model capabilities solely embedded in specific features or harnesses, or mere relaying of requests to models hosted by others.
What we did not invent
- VRAM, tokens/s, “frontier / SOTA / best open-weight” stay vendor.
- Card and OSS-blog bench rows stay self-reported (Artificial Analysis indexes, FrontierCode 2.0, Terminal-Bench 4.0, Cyber Index, Surge Code preference, 96.6% malicious-cyber refusal).
- We do not rank Mistral Large 4 against ChatGPT, Claude Code, GLM-5.3, Kimi K3, DeepSeek-V4.1-Flash, or Muse Spark Open.
Related on this site: Muse Spark Open — Mistral Large 4 vs Muse Spark Open — GLM-5.3-Flash — DeepSeek-V4.1-Flash — Kimi K3 — Reflection Beam. Serving: vLLM. UIs: Open WebUI, LibreChat, Jan. Catalog: home. Editorial: About.
Benchmarks
Quoted from the cited source. forkalt has not independently reproduced these numbers.
| Name | Score | Source |
|---|---|---|
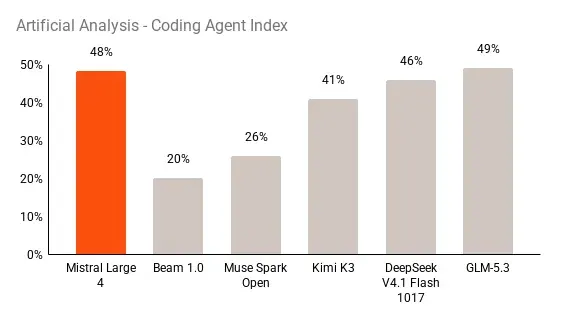
| Artificial Analysis Coding Agent Index (card / OSS blog) | 48% (self-reported) | https://mistral.ai/news/mistral-large-4-oss/ |
| Artificial Analysis Intelligence Index v5 (card) | 26 (self-reported) | https://huggingface.co/mistralai/Mistral-Large-4-1T-A52B |
| Cognition FrontierCode 2.0 (OSS blog) | 19.7% (self-reported) | https://mistral.ai/news/mistral-large-4-oss/ |
| Terminal-Bench 4.0 (OSS blog) | 41% (self-reported) | https://mistral.ai/news/mistral-large-4-oss/ |
| Artificial Analysis Cyber Index (OSS blog) | 51% (self-reported) | https://mistral.ai/news/mistral-large-4-oss/ |
Deploy options
- local: Hugging Face weights (FP8)
- local: Hugging Face weights (NVFP4)
- local: vLLM Docker recipe (card)
- hosted: Mistral API (mistral-large-4)
Comparisons
FAQ
Is Mistral Large 4 open weight, and can I use it commercially?
The ungated card mistralai/Mistral-Large-4-1T-A52B ships a LICENSE file titled Mistral Ecosystem Open-Weight License (a modified MIT grant). Hugging Face cardData.license is other. Internal use that does not expose the model to third parties is described as outside the MaaS clause. Operating a Model-as-a-Service business requires a separate commercial license with Mistral. Read the file. Not legal advice.
FP8, NVFP4, and DSpark — what actually shipped?
The lead card is the FP8 checkpoint (HF tags include fp8; quantization_config.quant_method fp8). The NVFP4 sibling mistralai/Mistral-Large-4-1T-A52B-NVFP4 is ungated (50 likes / 315 downloads in the 2026-10-30 API check). Both cards document an embedded DSpark draft head. vLLM enables it with --speculative-config method dspark and num_speculative_tokens 3. Vendor throughput claims stay vendor.
Does it beat Muse Spark Open, GLM-5.3, or ChatGPT?
We have no sourced bake-off. Card and OSS blog rows (Artificial Analysis Coding Agent Index 48%, Intelligence Index v5 score 26, FrontierCode 2.0 19.7%, Terminal-Bench 4.0 41%, Cyber Index 51%) are self-reported. See Mistral Large 4 vs Muse Spark Open. We do not rank writing or coding quality against ChatGPT.
Will it run on a laptop?
No sourced laptop recipe. runsLocally means the weights are downloadable without a gate. The published vLLM Docker serve uses tensor parallel 8. Treat hardware as datacenter-class until a named-GPU run exists.
Sources & verification
- https://huggingface.co/mistralai/Mistral-Large-4-1T-A52B
- https://huggingface.co/mistralai/Mistral-Large-4-1T-A52B/raw/main/LICENSE
- https://huggingface.co/mistralai/Mistral-Large-4-1T-A52B-NVFP4
- https://mistral.ai/news/mistral-large-4-oss/
- https://huggingface.co/blog/mistral-large4
- https://github.com/vllm-project/vllm
License notes are not legal advice. Read the original LICENSE. Trademark & disclaimer.