
Apache-2.0llmRuns locally4B (card); 4.54B (HF safetensors F16)
Qwen3.5-4B-3D-Coder: Specs, License & How to Run
Community Apache-2.0 4B Three.js / coding fine-tune. Not official Qwen.
- License
- Apache-2.0
- Parameters
- 4B (card); 4.54B (HF safetensors F16)
- HF likes
- 478 (2026-11-02)
- First seen
- 2026-10-25
TL;DR. Qwen3.5-4B-3D-Coder is a llm model from CCORE (community; not Qwen). Parameters: 4B (card); 4.54B (HF safetensors F16).License: Apache-2.0. It is listed under Claude Code, Cursor, ChatGPT, Closed LLM APIs.
| Developer | CCORE (community; not Qwen) |
|---|---|
| Type | llm |
| Architecture | Independent fine-tune of Qwen/Qwen3.5-4B (card + cardData.base_model). HF model_type qwen3_5; architecture Qwen3_5ForConditionalGeneration. text_config: 32 layers, hidden_size 2560, 16 Q / 4 KV heads, intermediate 9216, vocab 248320, max_position_embeddings 262144, hybrid linear + full attention (full_attention every 4th layer). Early preview; the card says the author is still training. Distinct from official Qwen/Qwen3.8-27B and from Sperid Labs Idol (image-to-3D splat). |
| Parameters | 4B (card); 4.54B (HF safetensors F16) |
| Modalities | text, image, code |
| Languages | en |
| Context | 262,144 tokens (config); llama.cpp example uses 65,536 |
| License | Apache-2.0 — LICENSE on ccore/Qwen3.5-4B-3D-Coder is Apache License 2.0 (cardData.license apache-2.0, opened 2026-11-02). The card states this is an independent CCORE fine-tune of Qwen/Qwen3.5-4B, not an official Qwen release. Hosted Qwen Cloud terms are unrelated. Not legal advice. |
| Hardware | Not yet verified — Card ships FP16 Safetensors (4 shards), Q4_K_M GGUF, Q8_0 GGUF, and an optional BF16 vision projector (~644 MiB / 676 MB sibling). HF usedStorage is 31,354,574,590 bytes (~29.2 GiB) for the whole repo. Peak VRAM is not independently measured. Card: llama.cpp vision load tested locally with llama.cpp b11889; FP16 text load verified with Transformers 5.20.2. Those are upstream tests, not forkalt runs. (not independently tested) |
| Hugging Face likes | 478 (as of 2026-11-02) |
| Model card | https://huggingface.co/ccore/Qwen3.5-4B-3D-Coder |
| First seen | 2026-10-25 |
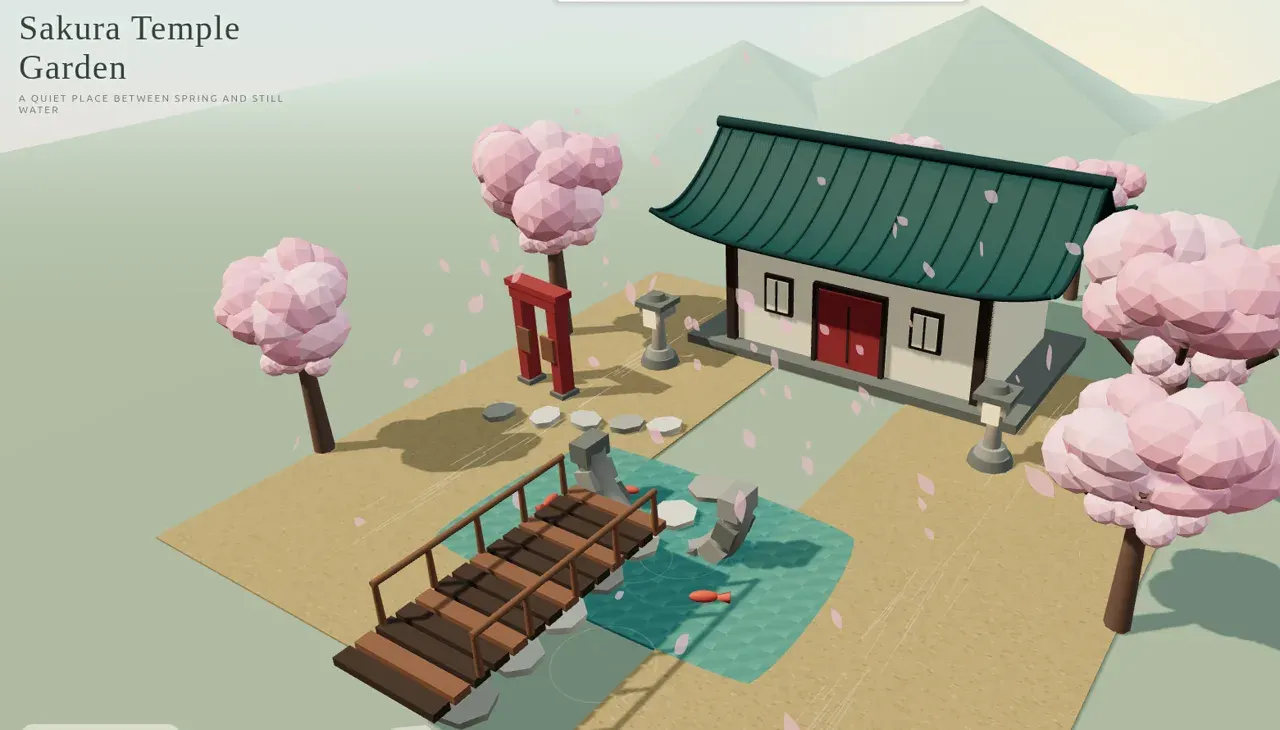
Qwen3.5-4B-3D-Coder is a community 4B coding preview from CCORE: general-purpose coding with a focus on self-contained Three.js scenes. Official hosts we opened on 2026-11-02: the ungated card ccore/Qwen3.5-4B-3D-Coder (created 2026-10-25T05:43:34Z; last modified 2026-10-30T15:47:46Z; 478 likes / 44,825 downloads), the Apache 2.0 LICENSE, config.json, the named base Qwen/Qwen3.5-4B (1,176 likes / 6,588,471 downloads; Apache-2.0), the MIT dataset ccore/ThreeJS-3D-Scenes (33 likes / 1,781 downloads; 4,146 examples), and the technical report PDF. API gated was false.
The card’s first identification sentence is the one that matters: this is an independent fine-tune of Qwen3.5-4B. It is not an official Qwen release. Official Qwen already on this site: Qwen3.8-27B. Head-to-head facts: Qwen3.5-4B-3D-Coder vs Qwen3.8-27B.
This page hangs off Claude Code alternatives, Cursor alternatives, ChatGPT alternatives, and closed LLM APIs. Those mappings are editorial for a local coding checkpoint. We have no sourced quality comparison against Claude Code, Cursor, or ChatGPT.
It is not Idol (Sperid Labs image-to-3D Gaussian splat) and not SenseNova 6.8 Code2Video (official-ish 27B code-driven video fine-tune of Qwen3.8-27B).
“Early preview,” “still training,” and “one-shot success has improved substantially” stay author / vendor.
What we verified (2026-11-02)
| Field | Value | Source |
|---|---|---|
| Host | huggingface.co/ccore/Qwen3.5-4B-3D-Coder (not gated) | HF API |
| Created / last modified | 2026-10-25T05:43:34Z / 2026-10-30T15:47:46Z | same |
| Likes / downloads | 478 / 44,825 | same |
| License tag + file | apache-2.0 / Apache License 2.0 | HF cardData + LICENSE |
| Relation | finetune of Qwen/Qwen3.5-4B |
HF cardData |
| Official? | No — card: “not an official Qwen release” | README |
| Architecture | qwen3_5 / Qwen3_5ForConditionalGeneration |
config.json |
| Params (card / safetensors) | 4B / 4,539,265,536 F16 | README + HF API |
| usedStorage | 31,354,574,590 bytes (~29.2 GiB) | HF API |
| text_config | 32 layers / hidden 2560 / 16 Q, 4 KV / vocab 248,320 | config.json |
| Context (config) | 262,144 | max_position_embeddings |
| Files | FP16 ×4 shards, Q4_K_M, Q8_0, optional mmproj | HF siblings |
| Dataset | ccore/ThreeJS-3D-Scenes · MIT · 4,146 rows · 33 likes | HF dataset API |
October 27 GGUF refresh, October 29 FP16 + dataset + PDF, and October 30 optional vision projector are dated on the README we opened. The card says the Q4/Q8 files now contain the October 27 checkpoint.
How to run (from the official card, not tested)
Copied names only. forkalt has not loaded a checkpoint and has not rendered a Three.js file.
GGUF (card): temperature 0.6–0.8, top_p 0.90–0.95, top_k 20–40, repeat penalty 1.0. LM Studio: disable multi-token prediction (MTP); the card says LM Studio enables it by default.
FP16 Transformers (card): temperature 0.6, top_k 20, top_p 0.95, repetition penalty 1.0; author says loading + text generation was verified with Transformers 5.20.2.
Vision GGUF (optional, 2026-10-30): download mmproj-Qwen3.5-4B-BF16.gguf (~644 MiB; unmodified projector from lmstudio-community/Qwen3.5-4B-GGUF, Apache-2.0) and load it with llama.cpp:
llama-server \
  -m Qwen3.5-4B-3D-Coder-Q4_K_M.gguf \
  --mmproj mmproj-Qwen3.5-4B-BF16.gguf \
  --n-gpu-layers all --flash-attn on \
  --ctx-size 65536 --parallel 1
Card: tested with llama.cpp b11889. Image tokens share the context window. That is an upstream short test, not a forkalt run.
Three.js system prompt copied from the card: use only the Three.js core ES module from cdnjs 0.160.0; do not import addons or legacy examples/js paths.
License
LICENSE is Apache License 2.0. Card tag apache-2.0. The dataset is MIT. The optional projector is Apache-2.0 from the lmstudio-community Qwen3.5-4B GGUF. Not legal advice.
What we did not invent
- Scene quality, “one-shot success,” and known-issue notes (duplicate variable names) stay author.
- We do not rank this card against Claude Code, Cursor, Qwen3.8-27B, Spark-X2.6-4B, or Flint.
- Peak VRAM is not independently measured.
- This is not official Qwen and not an image-to-3D splat.
Related: Qwen3.5-4B-3D-Coder vs Qwen3.8-27B — Qwen3.8-27B (official 27B VLM) — Spark-X2.6-4B (~4B on-device coding/agent) — Flint (39.8B/2.5B coding MoE) — SenseNova 6.8 Code2Video (code-driven video; different job) — Idol (image-to-3D splat; different job). Serving: vLLM. Agents: Cline, OpenCursor. Catalog: home. Corrections: contact.
Deploy options
Comparisons
FAQ
Is this an official Qwen model?
No. The card says it is an independent fine-tune by CCORE of Qwen/Qwen3.5-4B and “is not an official Qwen release.” Official Qwen cards already on this site include Qwen3.8-27B. Compare Qwen3.5-4B-3D-Coder vs Qwen3.8-27B.
Are the weights public, and what is the license?
Yes. huggingface.co/ccore/Qwen3.5-4B-3D-Coder is ungated (created 2026-10-25T05:43:34Z; last modified 2026-10-30T15:47:46Z; 478 likes / 44,825 downloads in the 2026-11-02 API check). LICENSE is Apache License 2.0. cardData.license is apache-2.0. The training set ccore/ThreeJS-3D-Scenes is MIT (33 likes). Not legal advice.
How big is it?
The card calls it a 4B preview. Hugging Face safetensors.parameters total 4,539,265,536 F16 (~4.54B). The official base Qwen/Qwen3.5-4B reports 4,659,865,088 BF16 tensors. We copy both the 4B marketing line and the tensor sums; we do not pick a winner.
Does it replace Claude Code, Cursor, or Qwen3.8-27B?
No sourced bake-off. This page identifies a community coding / Three.js fine-tune. “One-shot success has improved substantially” is the author’s qualitative note, not a leaderboard. See Claude Code alternatives and Qwen3.5-4B-3D-Coder vs Qwen3.8-27B.
Sources & verification
- https://huggingface.co/ccore/Qwen3.5-4B-3D-Coder
- https://huggingface.co/ccore/Qwen3.5-4B-3D-Coder/raw/main/LICENSE
- https://huggingface.co/ccore/Qwen3.5-4B-3D-Coder/raw/main/config.json
- https://huggingface.co/Qwen/Qwen3.5-4B
- https://huggingface.co/datasets/ccore/ThreeJS-3D-Scenes
- https://huggingface.co/Qwen/Qwen3.8-27B
License notes are not legal advice. Read the original LICENSE. Trademark & disclaimer.