
otheraudioRuns locally2B (card; safetensors 2,002,332,928)
LFM3-Audio-2B: Specs, License & How to Run
Liquid AI 2B audio any-to-any — text/audio in, text+speech out. Not Omni, not 1.7B.
- License
- other
- Parameters
- 2B (card; safetensors 2,002,332,928)
- HF likes
- 177 (2026-11-02)
- First seen
- 2026-09-08
TL;DR. LFM3-Audio-2B is a audio model from Liquid AI. Parameters: 2B (card; safetensors 2,002,332,928).License: other. It is listed under ElevenLabs, Closed LLM APIs.
| Developer | Liquid AI |
|---|---|
| Type | audio |
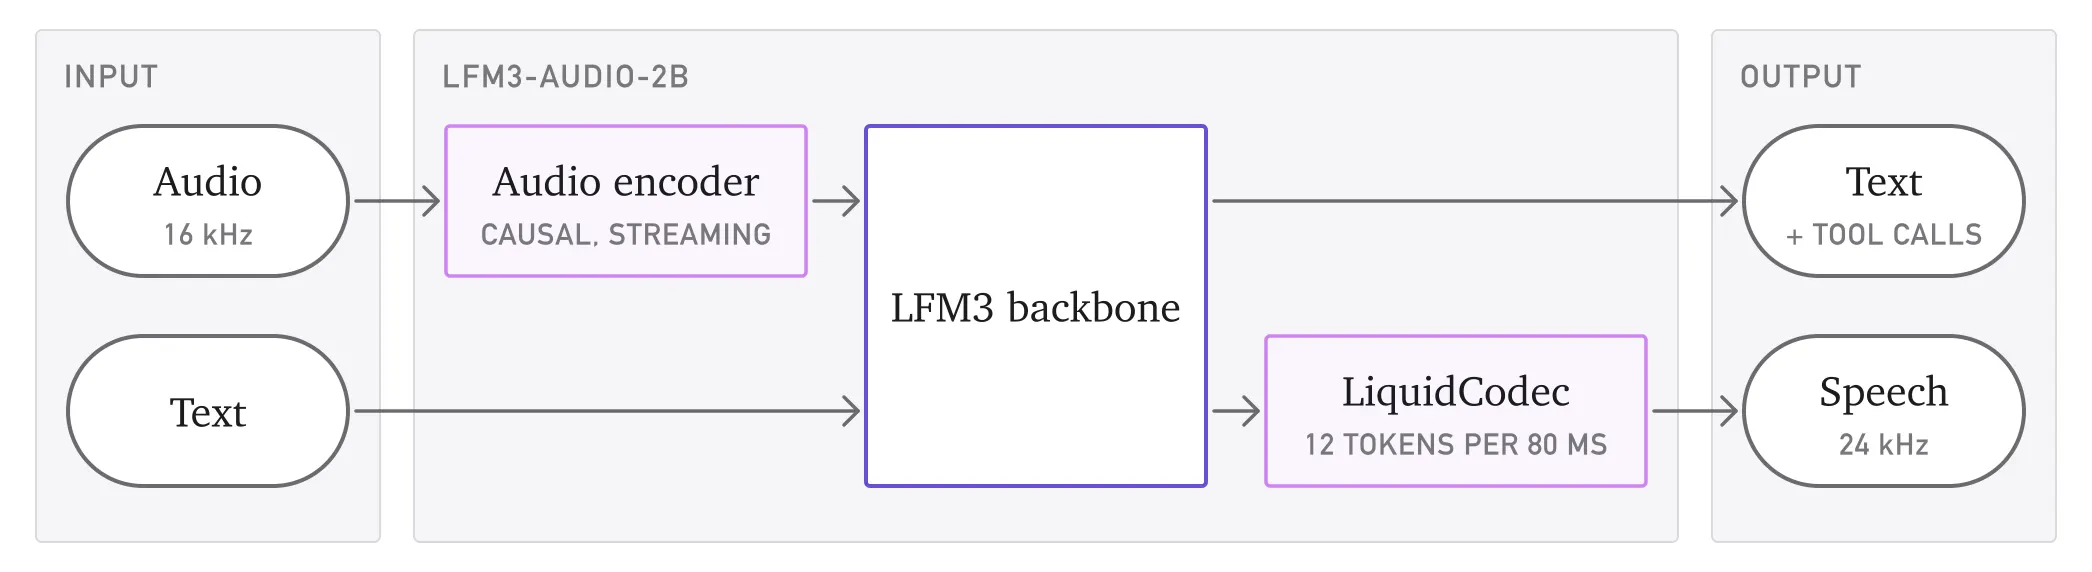
| Architecture | lfm3_audio. Card: LFM3 backbone, causal audio encoder (16 kHz in), LiquidCodec tokenizer (12 discrete tokens per 80 ms; 24 kHz speech out). pipeline_tag any-to-any. Distinct from LFM3-1.7B (text-only 1.73B / 256K), LFM3-Omni-2B (2.17B text/image/video/audio in), and LFM2.5-24B-A2B (24.0B / 2.45B text MoE). Card: not recommended for agentic coding or complex multi-step reasoning because of its small size. Custom code; load with trust_remote_code=True. |
| Parameters | 2B (card; safetensors 2,002,332,928) |
| Modalities | text, audio, speech |
| Languages | English, Arabic, Danish, German, Greek, Finnish, French, Hebrew, Italian, Japanese, Korean, Dutch, Polish, Portuguese, Spanish, Swedish, Turkish, Chinese |
| Context | 32K tokens (input + output) |
| License | other — LICENSE on LiquidAI/LFM3-Audio-2B is LFM Open License v1.0 (cardData.license other / license_name lfm1.0). Licensor is Liquid AI, Inc. Section 5 conditions Commercial Use on You/Legal Entity not exceeding annual revenue Threshold of USD 10,000,000. Above the threshold, Commercial Use is not licensed under this agreement. Qualified Non-Profits using the work for non-commercial or research purposes are exempt from the threshold. Same grant on the GGUF / MLX / ONNX siblings we opened. Not legal advice. |
| Hardware | Not yet verified — Card: designed to run locally on laptops and edge devices. HF usedStorage on the BF16 card is 4,169,781,494 bytes (~3.88 GiB). Siblings LiquidAI/LFM3-Audio-2B-GGUF, LFM3-Audio-2B-MLX-4bit, and LFM3-Audio-2B-ONNX were ungated on 2026-11-02. Peak VRAM and tok/s are not independently measured. Streaming claims (time to first token as low as 50 ms; LiquidCodec ~87× real time on one Apple M4 Max CPU thread) stay vendor. (not independently tested) |
| Hugging Face likes | 177 (as of 2026-11-02) |
| Model card | https://huggingface.co/LiquidAI/LFM3-Audio-2B |
| First seen | 2026-09-08 |
LFM3-Audio-2B is Liquid AI’s audio checkpoint in the LFM3 family: text or audio in, text and 24 kHz speech out. Official hosts we opened on 2026-11-02: the ungated card LiquidAI/LFM3-Audio-2B (created 2026-09-08T18:23:36Z; last modified 2026-10-31T00:51:45Z; 177 likes / 5,688 downloads), siblings LFM3-Audio-2B-GGUF (37 likes / 41,574 downloads), LFM3-Audio-2B-MLX-4bit (9 likes / 1,013 downloads), and LFM3-Audio-2B-ONNX (8 likes / 500 downloads), the LFM Open License v1.0, the LFM3 collection, and the family post Introducing LFM3. API gated was false on every card in that set.
It is not LFM3-1.7B (text-only 1.73B / 256K) and not LFM3-Omni-2B (2.17B; also sees images and video). Sibling facts for those two: LFM3-1.7B vs LFM3-Omni-2B. Family facts versus the earlier Liquid MoE: LFM3 vs LFM2.5-24B-A2B. Dedicated TTS (different job): Audio8-TTS-Realistic-0.6B and Qwen3-TTS.
This identification page hangs off ElevenLabs alternatives for speech-out and closed LLM APIs for a local audio agent. Those mappings are editorial. We have no sourced quality comparison against ElevenLabs or named closed APIs.
pipeline_tag is any-to-any. Card jobs copied: voice chat (English only for spoken Q&A with reasoning on text-only replies), multilingual transcribe / synthesize / translate (18 speech locales), audio understanding, and tool calling. The “improves over LFM2.5-Audio” sentence stays vendor.
What we verified (2026-11-02)
| Field | Value | Source |
|---|---|---|
| Host | huggingface.co/LiquidAI/LFM3-Audio-2B (not gated) | HF API |
| Created / last modified | 2026-09-08T18:23:36Z / 2026-10-31T00:51:45Z | same |
| Likes / downloads | 177 / 5,688 | same |
| License tag + file | other / lfm1.0 + LFM Open License v1.0 |
HF cardData + LICENSE |
| Pipeline tag | any-to-any | HF API |
| Params (card) | 2B total | README “Model details” |
| safetensors.parameters | 2,002,332,928 | HF API |
| usedStorage (BF16) | 4,169,781,494 bytes (~3.88 GiB) | same |
| Context | 32K tokens (input + output) | README |
| Inputs | Text or 16 kHz audio | README |
| Outputs | Text, 24 kHz speech, or interleaved | README |
| GGUF sibling | 37 likes / 41,574 downloads | HF API |
Speech locales on the card: Arabic, Danish, German, Greek, British English, American English, Finnish, French, Hebrew, Italian, Japanese, Korean, Dutch, Polish, Portuguese, Spanish, Swedish, Turkish, Chinese.
How to run (from the official README, not tested)
Copied names only. forkalt has not loaded a checkpoint.
The card lists BF16 (vLLM, SGLang, Transformers), GGUF (llama.cpp), MLX-4bit, and ONNX. Install line on the card: pip install "transformers>=5.20.2" torch accelerate librosa soundfile. Load with AutoModelForMultimodalLM / AutoProcessor and trust_remote_code=True. The processor loads codec weights from audio_tokenizer/.
Sampling copied for speech or interleaved: audio_temperature=1.0, audio_top_k=128, audio_repetition_penalty=1.1, audio_repetition_window=4096. Text-only: suppress_mixed=True, suppress_audio_out=True. TTS system prompt copied: Perform TTS in <language> using a <gender> voice. ASR: Perform ASR in <language>. LiveASR: Perform live ASR. (English only on the card). Voice chat: Respond with interleaved text and audio.
Hosted Liquid Playground is a different artifact from the weight grant.
Vendor benches (self-reported)
Copied LFM3-Audio 2B column only from the card table (Liquid-measured; other columns exist and are not copied here as a ranking): English ASR WER 6.23, multilingual ASR 6.03, English TTS UTMOSv2 3.83, VoiceBench 73.13, tool-calling internal eval 58.50, MMAR 50.60. Those are self-reported. They are not an ElevenLabs ranking and not a forkalt bake-off against LFM3-Omni-2B (Omni’s 2026-10-31 card printed a different English ASR 6.36 / TTS 3.80 row — still vendor, still a different checkpoint).
Streaming claims on the same card: time to first token “as low as 50 ms”; LiquidCodec “about 87× real time on a single CPU thread on Apple M4 Max.” Vendor, not our stopwatch.
License
LICENSE is LFM Open License v1.0. Licensor is named Liquid AI, Inc. Section 5: Commercial Use rights are conditioned on You or Your Legal Entity not exceeding the Threshold of USD 10,000,000 annual revenue. Commercial Use by an entity over that threshold is not licensed under this agreement. Qualified Non-Profit Organizations using the work for Non-Commercial or Research Purposes are exempt from the threshold. Not legal advice.
Related on this site: LFM3 (family) — LFM3-1.7B — LFM3-Omni-2B — LFM3-1.7B vs LFM3-Omni-2B — LFM2.5-24B-A2B — Audio8-TTS-Realistic-0.6B — Qwen3-TTS — Drama 3 — Phonon — Nemotron 3.5 Transcribe (ASR, file-oriented). Serving: vLLM. Chat weights: Nemotron 3.5 Bolt. Catalog: home. Corrections: contact.
Benchmarks
Quoted from the cited source. forkalt has not independently reproduced these numbers.
| Name | Score | Source |
|---|---|---|
| English ASR WER (card, ESB / Open ASR) | 6.23 (self-reported) | https://huggingface.co/LiquidAI/LFM3-Audio-2B |
| Multilingual ASR WER/CER (card, FLEURS) | 6.03 (self-reported) | https://huggingface.co/LiquidAI/LFM3-Audio-2B |
| English TTS UTMOSv2 (card) | 3.83 (self-reported) | https://huggingface.co/LiquidAI/LFM3-Audio-2B |
| VoiceBench (card) | 73.13 (self-reported) | https://huggingface.co/LiquidAI/LFM3-Audio-2B |
Deploy options
- local: Hugging Face weights (BF16 / Transformers / vLLM / SGLang)
- local: Hugging Face GGUF (llama.cpp)
- local: Hugging Face MLX-4bit
- local: Hugging Face ONNX
- hosted: Liquid Console API
FAQ
Is LFM3-Audio-2B the same as LFM3-Omni-2B or LFM3-1.7B?
No. LFM3-Audio-2B is the audio checkpoint (text or 16 kHz audio in; text and 24 kHz speech out; 32K). LFM3-Omni-2B also takes images and video. LFM3-1.7B is text-only 1.73B / 256K. Same LFM Open License v1.0; different job. See LFM3, LFM3-Omni-2B, and LFM3-1.7B vs LFM3-Omni-2B.
Are the weights public?
Yes. LiquidAI/LFM3-Audio-2B is ungated (created 2026-09-08T18:23:36Z; last modified 2026-10-31T00:51:45Z; 177 likes / 5,688 downloads in the 2026-11-02 API check). Siblings LFM3-Audio-2B-GGUF (37 likes / 41,574 downloads), LFM3-Audio-2B-MLX-4bit (9 likes / 1,013 downloads), and LFM3-Audio-2B-ONNX (8 likes / 500 downloads) were also ungated that day. Collection: huggingface.co/collections/LiquidAI/lfm3.
Can I use it commercially?
The LICENSE file is LFM Open License v1.0. Section 5 conditions Commercial Use on You/Legal Entity not exceeding USD 10,000,000 annual revenue. Above that threshold, Commercial Use is not licensed under this agreement. Qualified Non-Profits for non-commercial/research purposes are exempt from the threshold. Not legal advice.
Does it replace ElevenLabs or a closed chat API?
No sourced bake-off. Speech-out is one audio mode (card TTS prompt “Perform TTS in … using a … voice”), not a hosted voice studio. Chat mapping is editorial for a local audio any-to-any checkpoint. Card audio rows stay self-reported. See ElevenLabs alternatives and closed LLM APIs.
Sources & verification
- https://huggingface.co/LiquidAI/LFM3-Audio-2B
- https://huggingface.co/LiquidAI/LFM3-Audio-2B/raw/main/LICENSE
- https://huggingface.co/LiquidAI/LFM3-Audio-2B-GGUF
- https://huggingface.co/LiquidAI/LFM3-Audio-2B-MLX-4bit
- https://huggingface.co/LiquidAI/LFM3-Audio-2B-ONNX
- https://huggingface.co/LiquidAI/LFM3-Omni-2B
- https://huggingface.co/LiquidAI/LFM3-1.7B
- https://huggingface.co/collections/LiquidAI/lfm3
- https://www.liquid.ai/blog/lfm3
License notes are not legal advice. Read the original LICENSE. Trademark & disclaimer.