
Apache-2.0image-genRuns locally5B
MOSS-Image: Specs, License & How to Run
OpenMOSS bilingual (en/zh) 5B text-to-image family with Base and SFT checkpoints, Apache-2.0.
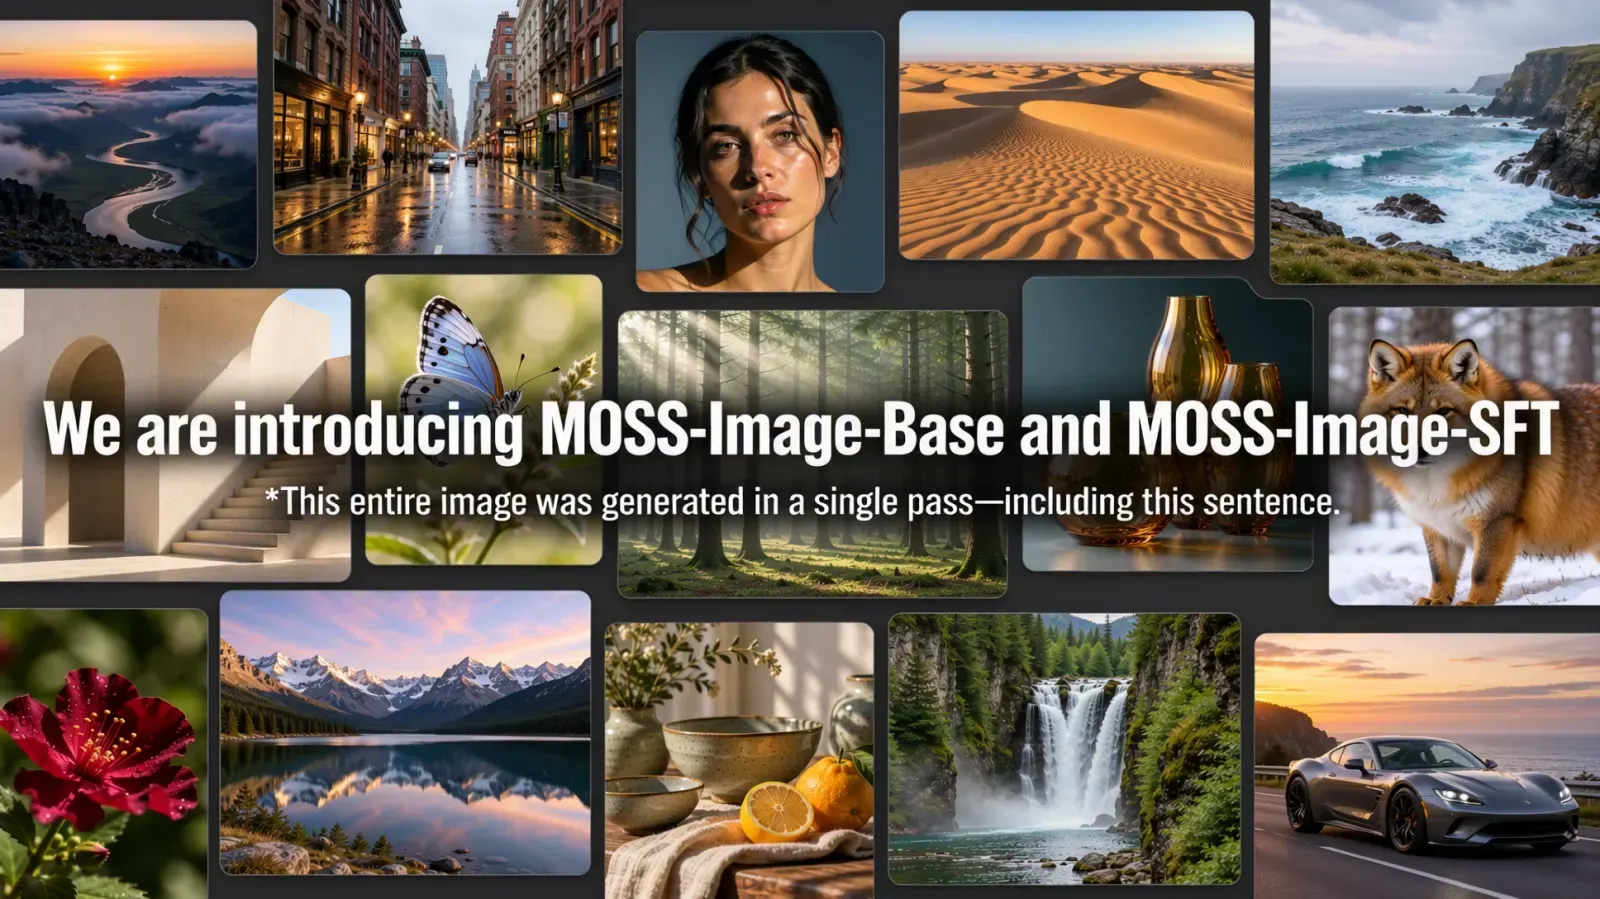
- License
- Apache-2.0
- Parameters
- 5B
- HF likes
- 291 (2026-10-19)
- First seen
- 2026-10-11
TL;DR. MOSS-Image is a image-gen model from OpenMOSS. Parameters: 5B.License: Apache-2.0. It is listed under Midjourney.
| Developer | OpenMOSS |
|---|---|
| Type | image-gen |
| Architecture | 5B diffusion transformer with a Qwen text encoder and bundled FLUX.2 small VAE decoder (official site / vLLM recipe / card) |
| Parameters | 5B |
| Modalities | image, text |
| Languages | en, zh |
| License | Apache-2.0 — Apache-2.0 on the Base and SFT Hugging Face cards, the Base LICENSE file, and the GitHub repository license field as of 2026-10-19. The site notes that pipeline code and third-party components retain their respective licenses. Not legal advice. |
| Hardware | Not yet verified — Official quick start asks for an NVIDIA GPU with CUDA, Python 3.10+, PyTorch 2.9+, and Diffusers. HF API usedStorage on both Base and SFT is 27,228,815,653 bytes (~25.4 GiB on disk); safetensors.parameters total 5,082,308,624 (~5.08B). Peak VRAM is not independently measured here. (not independently tested) |
| Hugging Face likes | 291 (as of 2026-10-19) |
| Model card | https://huggingface.co/OpenMOSS-Team/MOSS-Image-Base |
| First seen | 2026-10-11 |
MOSS-Image is an open text-to-image family from OpenMOSS. Official hosts we opened on 2026-10-19: OpenMOSS-Team/MOSS-Image-Base, OpenMOSS-Team/MOSS-Image-SFT, the Apache 2.0 LICENSE on the Base card, github.com/OpenMOSS/MOSS-Image (689 stars), the site openmoss.ai/MOSS-Image, and the Space OpenMOSS-Team/MOSS-Image.
This page is a spoke from open Midjourney-class alternatives. That hub names a product class. We do not claim Midjourney quality.
What we verified (2026-10-19)
| Field | Base | SFT | Source |
|---|---|---|---|
| Host | OpenMOSS-Team/MOSS-Image-Base |
OpenMOSS-Team/MOSS-Image-SFT |
HF API |
| Created | 2026-10-11T06:49:17Z | 2026-10-11T07:01:17Z | HF createdAt |
| Last modified | 2026-10-16T19:30:54Z | 2026-10-16T19:30:54Z | HF API |
| Gated | false | false | HF API |
| Likes / downloads | 291 / 1,791 | 339 / 2,087 | HF API |
| License | apache-2.0 | apache-2.0 | HF cardData |
| Pipeline tag | text-to-image | text-to-image | HF API |
| Languages | en, zh | en, zh | HF cardData |
| safetensors total | 5,082,308,624 | 5,082,308,624 | HF API |
| usedStorage | 27,228,815,653 bytes | 27,228,815,653 bytes | HF API |
| SFT base_model | — | OpenMOSS-Team/MOSS-Image-Base (finetune) |
HF cardData |
GitHub OpenMOSS/MOSS-Image: created 2026-10-16T01:18:13Z, Apache-2.0 license field, 689 stars / 31 forks, homepage http://openmoss.ai/MOSS-Image/, README news line [2026-10-16] introducing Base and SFT as publicly available.
The official site describes a 5B backbone, prompts up to 4K tokens, bilingual text rendering, JSON layout control, and Apache-2.0 weights. The Base README says the bundled VAE uses the FLUX.2 small decoder; transformer and text encoder run in bfloat16, VAE and initial noise in float32. A vLLM-Omni recipe names a Qwen3.5 text encoder pairing. Those architecture sentences are upstream. We do not invent a more specific encoder checkpoint id than the cards state.
How to run (from official README, not yet tested)
Default sampling copied from the Base card:
| Setting | Default |
|---|---|
| Sampler | Flow-matching Euler |
| Steps | 50 |
| CFG | 3 |
| Shift | 5 |
| Layer skipping | Negative branch, layer index 22 |
| Image size | Positive multiples of 16 (Python API) |
Install line from the card: pip install "diffusers>=0.38" "transformers>=5.3" "accelerate>=1.10" "safetensors>=0.6" "Pillow>=10". Load with DiffusionPipeline.from_pretrained("OpenMOSS-Team/MOSS-Image-Base", custom_pipeline="pipeline_moss_image", trust_remote_code=True, ...). Swap the repo id for SFT. ComfyUI: the README says search MOSS-Image in ComfyUI Manager; “integration into the official ComfyUI repository is in progress.” forkalt has not run the pipeline.
License
Apache License 2.0 on the Base LICENSE file, both HF cards, and the GitHub license field. The official site adds that pipeline code and third-party components retain their respective licenses. Not legal advice.
What we did not invent
We have no sourced bake-off against Midjourney, Qwen-Image-2.1-Turbo, Iris-3B, or FLUX 3 Image Klein. Hardware VRAM is not yet verified. The Space like count (64 in one web fetch) is not used as the model-card like count.
Related image checkpoints: Qwen-Image-2.1-Turbo (MOSS-Image vs Qwen-Image 2.1 Turbo), Iris-3B, FLUX 3 Image Klein. Hub: Midjourney-class alternatives.
Deploy options
Comparisons
FAQ
Are MOSS-Image weights public?
Yes. OpenMOSS-Team/MOSS-Image-Base (created 2026-10-11T06:49:17Z; 291 likes / 1,791 downloads in the 2026-10-19 API check) and OpenMOSS-Team/MOSS-Image-SFT (created 2026-10-11T07:01:17Z; 339 likes / 2,087 downloads) are ungated text-to-image cards. GitHub OpenMOSS/MOSS-Image (created 2026-10-16; 689 stars / 31 forks in the same-day GitHub check) announced Base and SFT as publicly available on 2026-10-16.
What is the difference between Base and SFT?
Both share the same architecture and sampling interface. SFT is described as fine-tuned from Base on curated data. The cards’ Base-vs-SFT example says SFT produces clearer text grouping and a more organized whiteboard layout. That is an upstream illustration, not a forkalt bake-off.
Is it bilingual, and can I control layout?
Hugging Face cardData.language is en and zh on both cards. The official site and README describe natural-language prompts, tag sequences, and JSON layouts (bounding boxes for objects and rendered text), with prompts up to 4K tokens. We have not generated images from those prompts.
Does it match Midjourney quality?
No. This page identifies an open text-to-image family. We have no sourced side-by-side against Midjourney.
Sources & verification
- https://huggingface.co/OpenMOSS-Team/MOSS-Image-Base
- https://huggingface.co/OpenMOSS-Team/MOSS-Image-SFT
- https://huggingface.co/OpenMOSS-Team/MOSS-Image-Base/blob/main/LICENSE
- https://github.com/OpenMOSS/MOSS-Image
- https://openmoss.ai/MOSS-Image/
- https://huggingface.co/spaces/OpenMOSS-Team/MOSS-Image
License notes are not legal advice. Read the original LICENSE. Trademark & disclaimer.