
Apache-2.0visionRuns locally1.3B (card; safetensors 1.300B)
MiniCPM-OCR 1.0: Specs, License & How to Run
OpenBMB Apache-2.0 ~1.3B OCR (zh/en). First OCR-specific MiniCPM-V/o card.
- License
- Apache-2.0
- Parameters
- 1.3B (card; safetensors 1.300B)
- HF likes
- 261 (2026-10-29)
- First seen
- 2026-10-21
TL;DR. MiniCPM-OCR 1.0 is a vision model from OpenBMB. Parameters: 1.3B (card; safetensors 1.300B).License: Apache-2.0. It is listed under Adobe Acrobat.
| Developer | OpenBMB |
|---|---|
| Type | vision |
| Architecture | Card: trained for OCR on top of MiniCPM-V 4.6; SigLIP vision encoder + Qwen3.5 language model. HF model_type minicpm_ocr; architecture MiniCPMOcrForConditionalGeneration. pipeline_tag image-text-to-text. text_config: qwen3_5_text, 24 layers, hidden 1024, vocab 248100, max_position_embeddings 262144. Parsing pipeline named on the card: MiniCPM-OCR 1.0 + PP-DocLayoutV3 + minicpmvocr SDK. This is document OCR, not MiniCPM-V 4.7 chat. |
| Parameters | 1.3B (card; safetensors 1.300B) |
| Modalities | image, text, document |
| Languages | zh, en |
| Context | 262,144 tokens (config.json text_config) |
| License | Apache-2.0 — Hugging Face cardData.license is apache-2.0 (opened 2026-10-29). The weight repo has no LICENSE sibling (resolve/main/LICENSE 404). GitHub OpenBMB/MiniCPM-OCR LICENSE is Apache License 2.0; the README states code, documentation, and model weights for MiniCPM-OCR 1.0 are Apache-2.0. Not legal advice. |
| Hardware | Not yet verified — HF usedStorage is 5,266,726,727 bytes (~4.91 GiB). safetensors.parameters sum to 1,300,434,160 BF16. Card names vLLM, SGLang, llama.cpp, Ollama, and DSpark draft siblings. Peak VRAM is not independently measured. Do not copy vendor pages/s or OmniDocBench rows as forkalt measurements. (not independently tested) |
| Hugging Face likes | 261 (as of 2026-10-29) |
| Model card | https://huggingface.co/openbmb/MiniCPM-OCR-1.0 |
| First seen | 2026-10-21 |
MiniCPM-OCR 1.0 is OpenBMB’s ungated ~1.3B OCR checkpoint — the first OCR-specific model in the MiniCPM-V/o family. Official hosts we opened on 2026-10-29: the card openbmb/MiniCPM-OCR-1.0 (created 2026-10-21T15:51:40Z; last modified 2026-10-28T15:53:59Z; 261 likes / 791 downloads) and github.com/OpenBMB/MiniCPM-OCR (237 stars / 16 forks; created 2026-10-27T13:22:00Z; last push 2026-10-28T15:06:49Z; LICENSE Apache-2.0). API gated was false. Hugging Face pipeline_tag is image-text-to-text.
This page hangs off Adobe Acrobat alternatives. That mapping is editorial for document OCR weights next to PDF toolboxes. We have no sourced quality comparison against Acrobat Pro OCR. Same-site OCR peers: Unlimited-OCR-2 — MiniCPM-OCR 1.0 vs Unlimited-OCR-2 — and DeepSeek-OCR. Same org, different job: MiniCPM-V 4.7 (on-device chat VLM).
The README calls it a text-centric document parser for text, tables, formulas, charts, seals, and key information extraction, in Chinese and English. Those capability lines stay vendor.
What we verified (2026-10-29)
| Field | Value | Source |
|---|---|---|
| Host | huggingface.co/openbmb/MiniCPM-OCR-1.0 (not gated) | HF API |
| Created / last modified | 2026-10-21T15:51:40Z / 2026-10-28T15:53:59Z | same |
| Likes / downloads | 261 / 791 | same |
| License tag | apache-2.0 | HF cardData |
| LICENSE on the weight repo | 404 | HF siblings |
| GitHub LICENSE | Apache License 2.0 | OpenBMB/MiniCPM-OCR LICENSE |
| GitHub stars / forks | 237 / 16 | GitHub API |
| Pipeline tag | image-text-to-text | HF API |
| Architecture | minicpm_ocr / MiniCPMOcrForConditionalGeneration | config.json |
| Params (card) | 1.3B | card |
| safetensors.parameters | 1,300,434,160 BF16 | HF API |
| usedStorage | 5,266,726,727 bytes (~4.91 GiB) | same |
| text_config | 24 layers / hidden 1024 / vocab 248,100 | config.json |
| Documented context | 262,144 | text_config.max_position_embeddings |
| Base (card) | MiniCPM-V 4.6; SigLIP + Qwen3.5 | card |
| Primary languages | Chinese and English | card + cardData.language |
Named siblings on the card (copied ids, not separately re-measured): GGUF, AWQ W4A16, GPTQ W4A16, DSpark draft BF16/GGUF. DSpark needs a matching draft from the same release.
How to run (from official docs, not tested)
The card and GitHub README recommend the minicpmvocr SDK with layout model PP-DocLayoutV3, and name backends vLLM, SGLang, llama.cpp, Ollama, Transformers. Agent setup pointer on the card: docs/SKILL_en.md in the GitHub repo. forkalt has not loaded the checkpoint or measured pages/s.
License
GitHub LICENSE is Apache License 2.0. README: weights, code, and documentation for MiniCPM-OCR 1.0 are Apache-2.0. Hugging Face card tag apache-2.0; no LICENSE blob on the weight repo (404 on 2026-10-29). Not legal advice.
What we did not invent
- Real5-OmniDocBench 93.68, OCRBench v2 54.7, and 1.2 pages/s on an RTX 5090 stay vendor / self-reported.
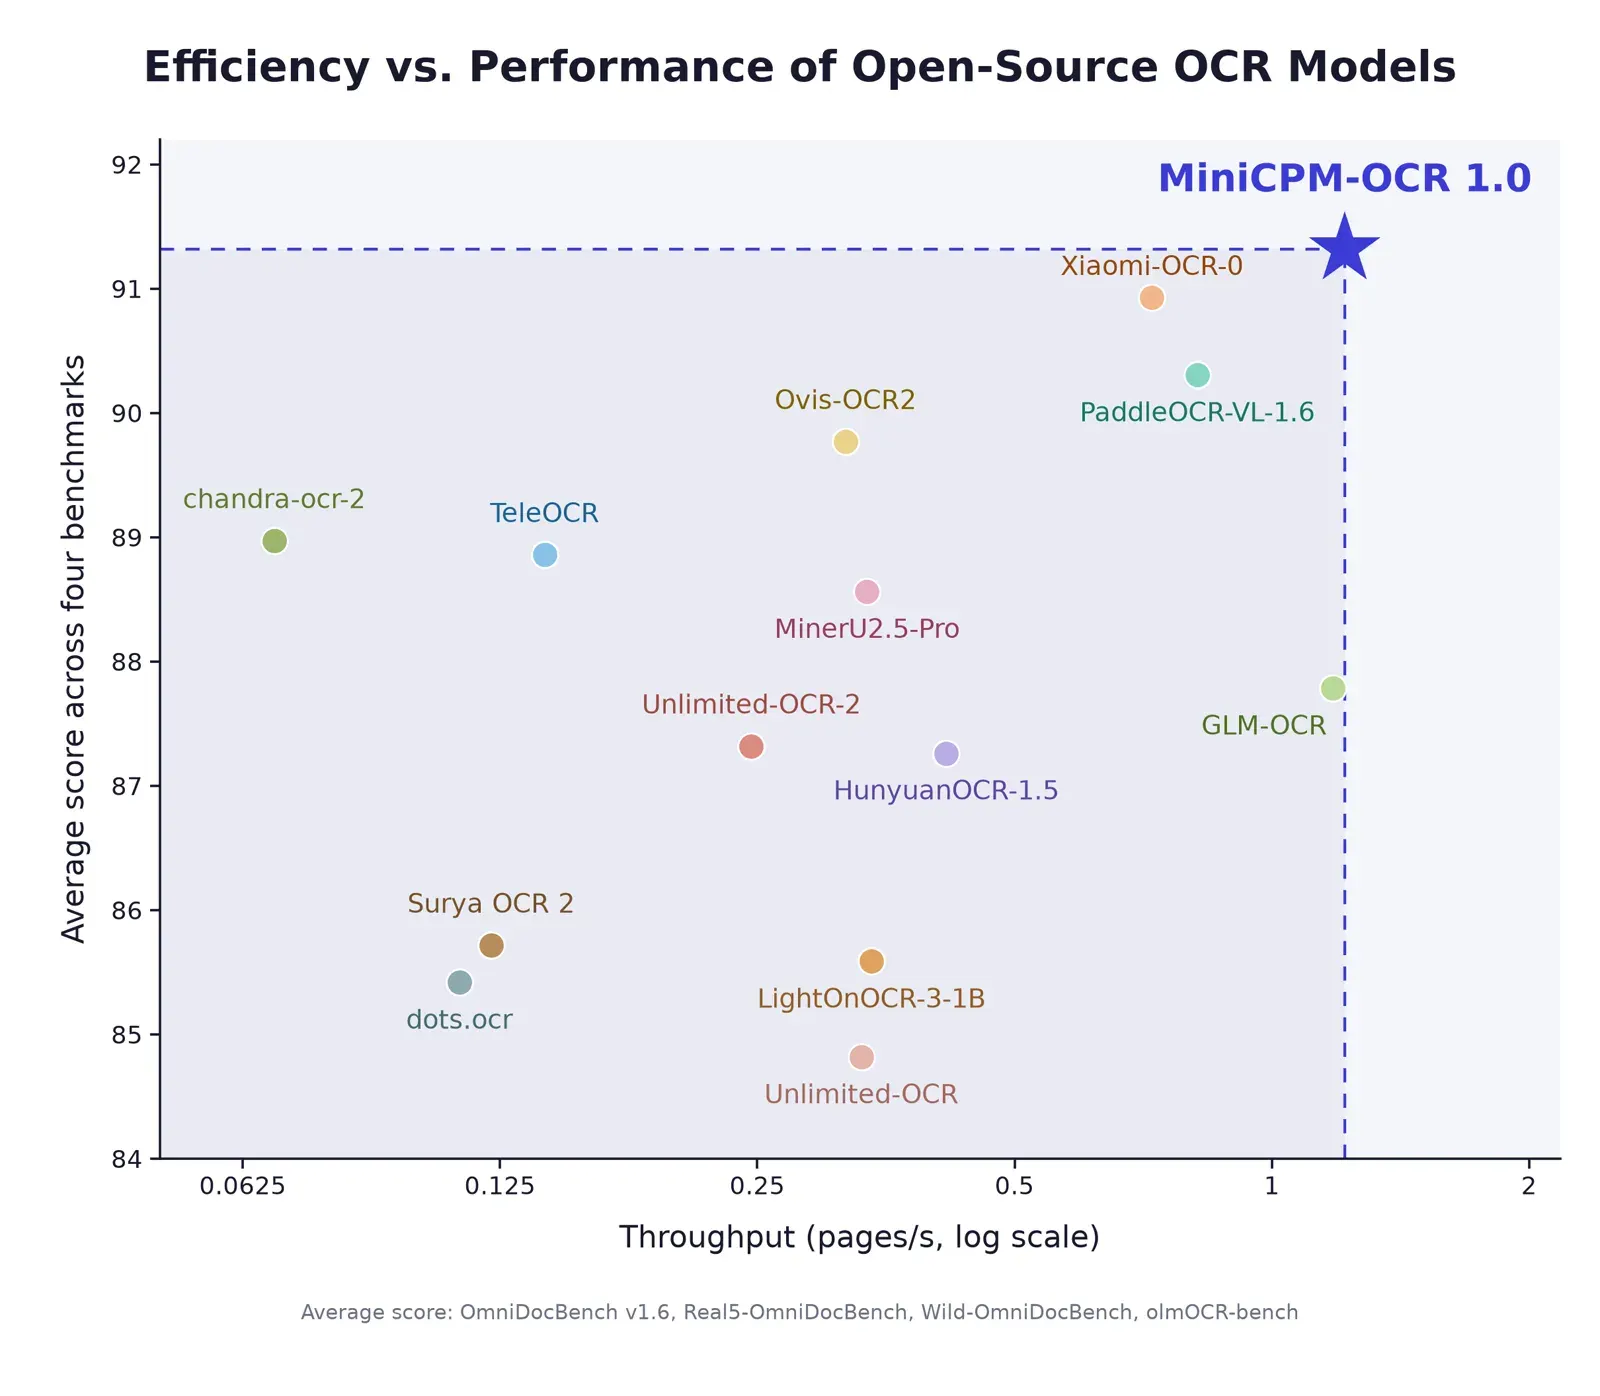
- Relative throughput vs PaddleOCR-VL-1.6 or MinerU2.5 Pro stays vendor.
- Peak VRAM is not independently measured.
- We do not rank MiniCPM-OCR 1.0 against Acrobat, Unlimited-OCR-2, or DeepSeek-OCR.
Related: Unlimited-OCR-2 — MiniCPM-OCR 1.0 vs Unlimited-OCR-2 — DeepSeek-OCR — Unlimited-OCR-2 vs DeepSeek-OCR — MiniCPM-V 4.7 (chat VLM, not this OCR card) — Stirling-PDF — Adobe Acrobat alternatives. Catalog: home. Editorial: About.
Benchmarks
Quoted from the cited source. forkalt has not independently reproduced these numbers.
| Name | Score | Source |
|---|---|---|
| Real5-OmniDocBench (vendor card) | 93.68 (self-reported) | https://huggingface.co/openbmb/MiniCPM-OCR-1.0 |
| OCRBench v2 (vendor card) | 54.7 (self-reported) | https://huggingface.co/openbmb/MiniCPM-OCR-1.0 |
| OmniDocBench v1.6 throughput (vendor; RTX 5090) | 1.2 pages/s (self-reported) | https://huggingface.co/openbmb/MiniCPM-OCR-1.0 |
Deploy options
- local: Hugging Face weights (BF16)
- local: GitHub SDK / docs
- local: GGUF (llama.cpp)
Comparisons
FAQ
Is MiniCPM-OCR 1.0 the same as MiniCPM-V 4.7?
No. MiniCPM-V 4.7 is OpenBMB’s on-device chat VLM (35B-A3B + 1B) on the ChatGPT hub. MiniCPM-OCR 1.0 is the first OCR-specific card in the MiniCPM-V/o family (~1.3B). Same org, different job.
Is it Apache-2.0?
Card tag apache-2.0. GitHub OpenBMB/MiniCPM-OCR LICENSE is Apache License 2.0 and the README covers weights, code, and docs. The Hugging Face weight repo had no LICENSE blob on 2026-10-29. Not legal advice.
Does it beat Unlimited-OCR-2 or Acrobat OCR?
We do not rank it. Card OmniDocBench / Real5 / throughput lines stay vendor. See MiniCPM-OCR 1.0 vs Unlimited-OCR-2. We have no sourced bake-off against Adobe Acrobat.
How big is it?
Card says 1.3B. Hugging Face safetensors.parameters sum to 1,300,434,160 BF16. usedStorage is ~4.91 GiB. Quantized GGUF/AWQ/GPTQ siblings are named on the card; we did not re-measure them.
Sources & verification
- https://huggingface.co/openbmb/MiniCPM-OCR-1.0
- https://github.com/OpenBMB/MiniCPM-OCR
- https://github.com/OpenBMB/MiniCPM-OCR/blob/main/LICENSE
- https://huggingface.co/baidu/Unlimited-OCR-2
- https://huggingface.co/deepseek-ai/DeepSeek-OCR
License notes are not legal advice. Read the original LICENSE. Trademark & disclaimer.